
Async transcription accuracy on hard audio: noisy call centers, overlapping speakers, and filler
Most speech-to-text demos run on clean audio — one speaker, a good mic, a quiet room. Production audio is the opposite: clipping headsets, people talking over each other, a card number read against a blaring TV.
 Real-time transcription that code-switches for multilingual speakersAssemblyai
How to remove or reduce background noise from audio for (stt) transcriptionAssemblyai
Redact PII in Audio with Make and AssemblyAIAssemblyai
LLM Gateway: The easiest and most reliable way to call multiple LLMsAssemblyai
Redact Personally Identifiable Information (PII) from audio with Node.jsAssemblyai
Speech-to-Text Accuracy on Podcasts, News Broadcasts, and Social MediaAssemblyai
 Video: Building a Live Transcription Badge With Deepgram - Deepgram Blog ⚡️Deepgram
 No Code Transcription: Simplifying Workflows with Deepgram and Make.comDeepgram
 Tagalog Speech to TextDeepgram
 Automate Audio Transcription with Zapier + DeepgramDeepgram
 Pancakes Are Delicious and Data Centers Are for Free StuffThenewstack
 Oso Unbundles Security AuthorizationThenewstack
 How Hunch supercharged AI workflows with Modal SandboxesModal
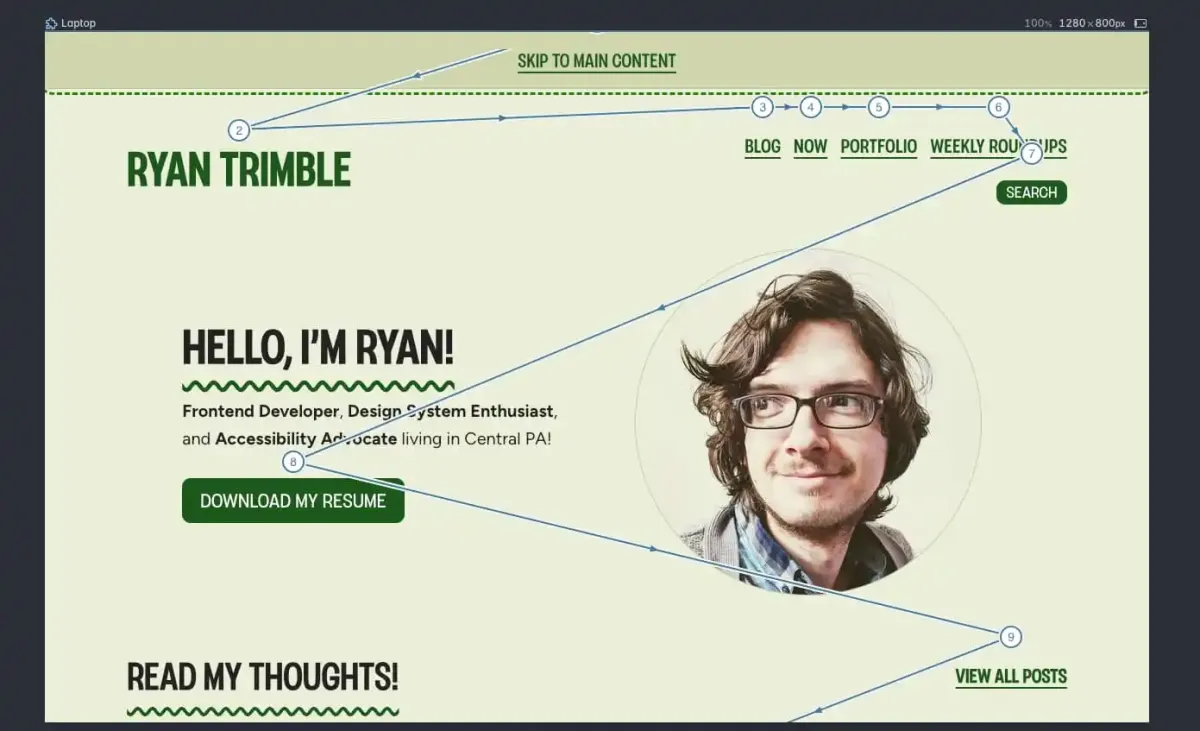 Clever Polypane Debugging Features I'm LovingCss Tricks
 Creating Color Themes With Custom Properties, HSL, and a Little calc()Css Tricks
 KAUST and Cerebras Named Gordon Bell Award Finalist for Solving Multi-Dimensional SeismicCerebras
 Cerebras Systems Enables GPU-Impossible™ Long Sequence Lengths Improving Accuracy in NaturalCerebras
 DockerCon LIVE with theCUBE: Call for Papers is OpenDocker
 6 tips every developer should know when using Cursor and Windsurf AIMintlify
 Why Medical Transcription is Hard for Humans and MachinesDeepgram
