
Accelerating Large Language Model Training with Variable Sparse Pre-training and Dense Fine-tuning
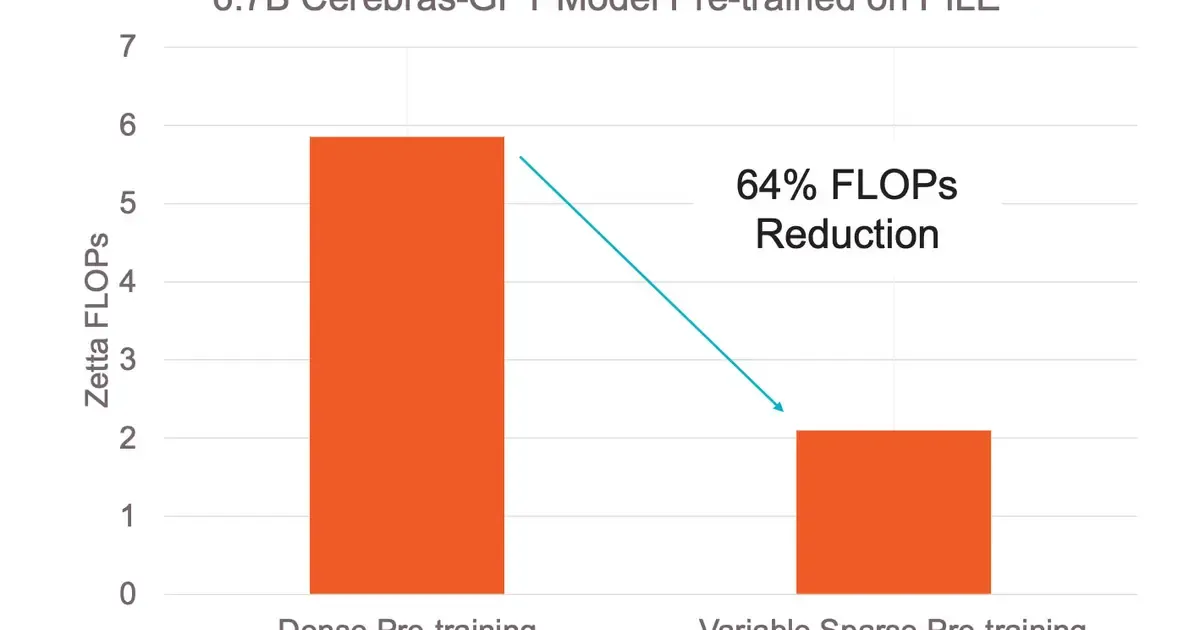
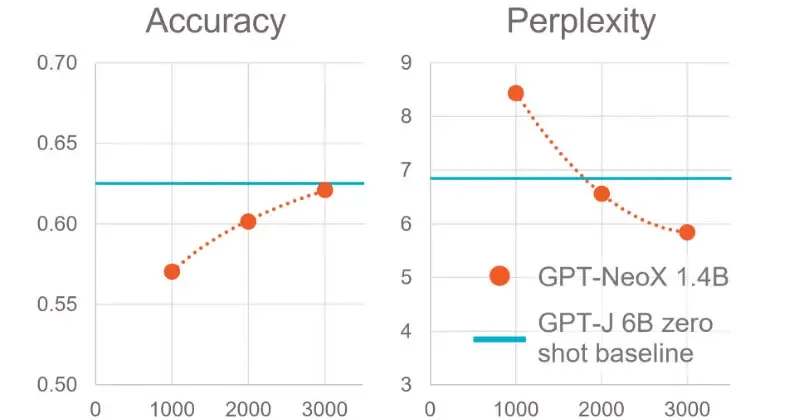
We reduced pre-training FLOPs by 64% using sparsity. To the best of our knowledge, this is the largest GPT model trained with unstructured weight sparsity while matching the quality of dense training.
 Fine-Tuning with Cerebras AI Model Studio Launchpad - CerebrasCerebras
 Training Multi-Billion-Parameter Models on a Single Cerebras System is Easy - CerebrasCerebras
 Accelerating GPT-5.6 Sol UltrafastCerebras
 The Cerebras AI Model Studio brings Wafer-Scale Cluster Acceleration to the Cloud - CerebrasCerebras
 How we fine-tuned Llama2-70B to pass the US Medical License Exam in a weekCerebras
 Visualizing Knowledge at Lightning Speed with Cerebras at Tako - CerebrasCerebras
 Trained on 100,000+ Voices: Deepgram Unveils Next-Gen Speaker Diarization and Language DetectionDeepgram
 The Language of LGBTQ Inclusion and Allyship - Deepgram Blog ⚡️Deepgram
 The Most Important Work in AI Training Is Also the Most Overlooked - Deepgram Blog ⚡️Deepgram
 New Spanish and Turkish Language Models and Updated General Models - Deepgram Blog ⚡️Deepgram
 How to implement AI training for employeesZapier
 AI frameworks: Definition, types, and how to chooseZapier
 OData or GraphQL? The Best Tech for Developing an API Is Neither or Both!Thenewstack
 Pkg.go.dev has a new look! - The Go Programming LanguageGo
Inside the Go Playground - The Go Programming LanguageGo
Real Go Projects: SmartTwitter and web.go - The Go Programming LanguageGo
The App Engine SDK and workspaces (GOPATH) - The Go Programming LanguageGo
Go on App Engine: tools, tests, and concurrency - The Go Programming LanguageGo
 The Go Memory Model - The Go Programming LanguageGo
Errors are values - The Go Programming LanguageGo
