
Cerebras Launches OpenAI’s gpt-oss-120B at a Blistering 3,000 tokens/sec
Cerebras powers the world's fastest AI inference on the biggest wafer chip. Cerebras CS-4 delivers up to 30x faster inference than GPUs.

 Introducing DocChat: GPT-4 Level Conversational QA Trained In a Few Hours - CerebrasCerebras
 Accelerating GPT-5.6 Sol UltrafastCerebras
 Visualizing Knowledge at Lightning Speed with Cerebras at Tako - CerebrasCerebras
 Breaking the Boundaries of Presence: Delphi's Digital Mind TechnologyCerebras
 Training Multi-Billion-Parameter Models on a Single Cerebras System is Easy - CerebrasCerebras
 Revolutionizing Life Science and Healthcare with Generative AI - CerebrasCerebras
 Trained on 100,000+ Voices: Deepgram Unveils Next-Gen Speaker Diarization and Language DetectionDeepgram
 Announcing Restore Stacks: Recover Deleted Stacks in the Pulumi CloudPulumi
 How to serve trillions of tokens for trillion-parameter coding agentsModal
 Anthropic integration with Modal brings scalable compute to Claude ScienceModal
 Building a Remote MCP Server: OAuth, Tool Design & Lessons from 4,000+ AI Queries | MotherDuckMotherduck
 What You Need To Know About OpenAI’s New 3D Model-Making AI, Point-E - Deepgram Blog ⚡️Deepgram
 How Sky Italia Digitizes Learning Paths to Accelerate New Product Launches by 4xSynthesia
 Synthesia launches talent experience program to learn from and reward the exceptional actors behindSynthesia
 upm Launches as a Fast, Tiny Package Manager Written in TypeScriptSocket
 Twitch Browser Extension Exposes 30,000 Users’ OAuth Tokens to Russian Bot ServiceSocket
 GlassWorm Loader Hits Open VSX via Developer Account CompromiseSocket
 737 Chrome VPN Extensions Linked to Brand Impersonation and Browser Traffic RedirectionSocket
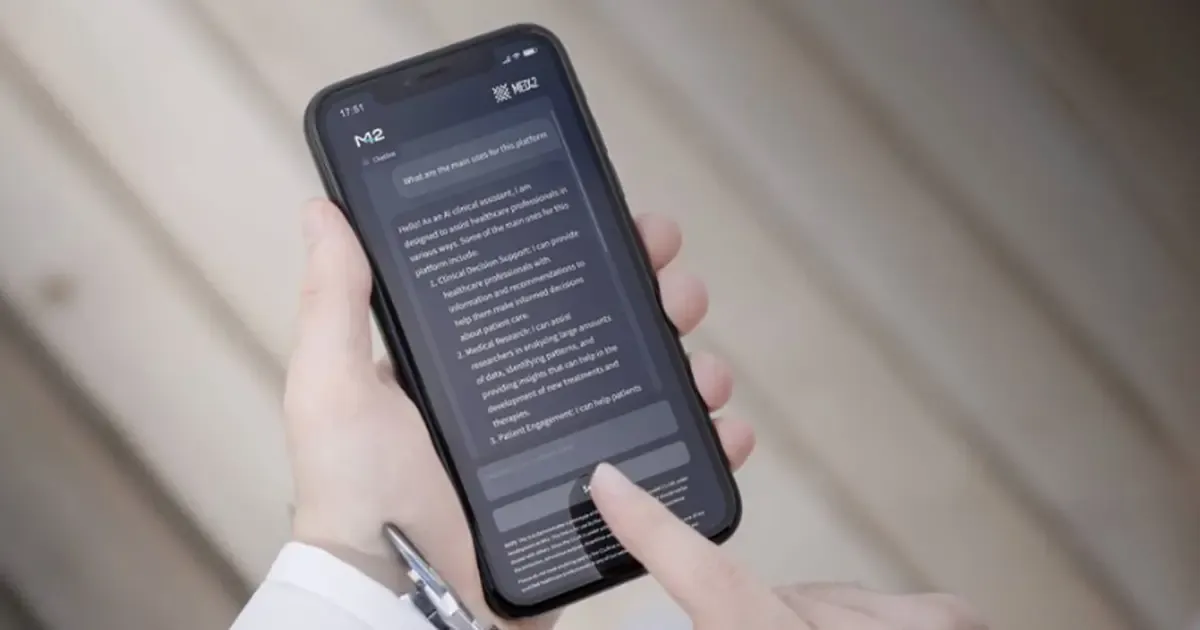 How we fine-tuned Llama2-70B to pass the US Medical License Exam in a weekCerebras
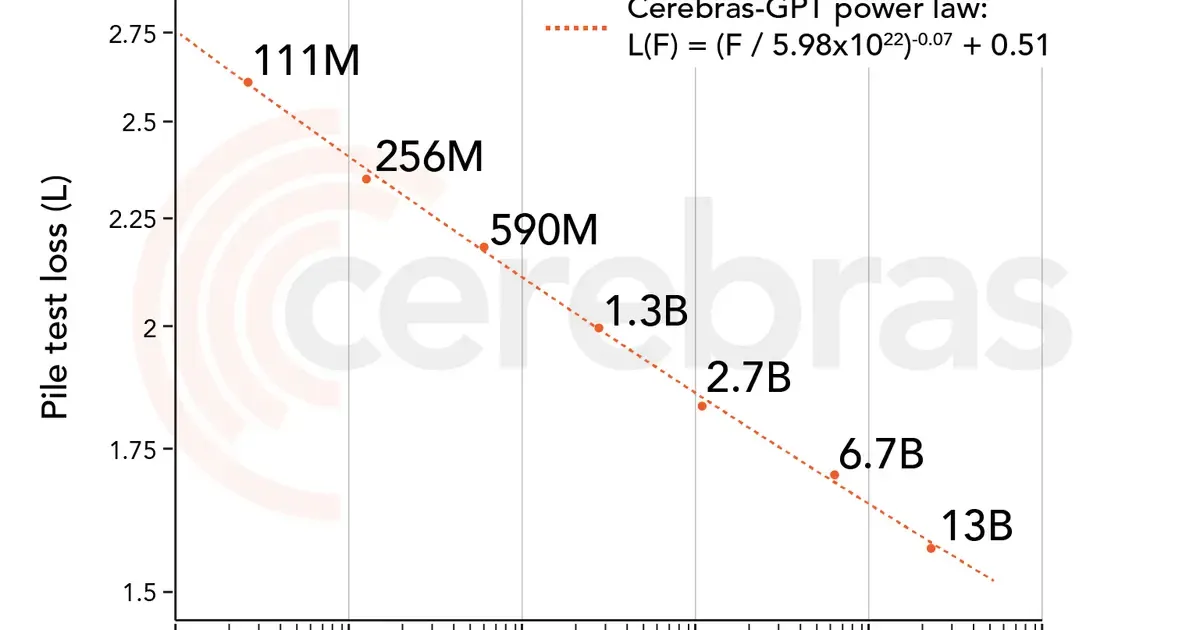 Cerebras-GPT: A Family of Open, Compute-efficient, Large Language Models - CerebrasCerebras
