
Cerebras Wafer-Scale Engine Achieves 210x Speedup Over NVIDIA H100 - Cerebras
Cerebras powers the world's fastest AI inference on the biggest wafer chip. Cerebras CS-4 delivers up to 30x faster inference than GPUs.
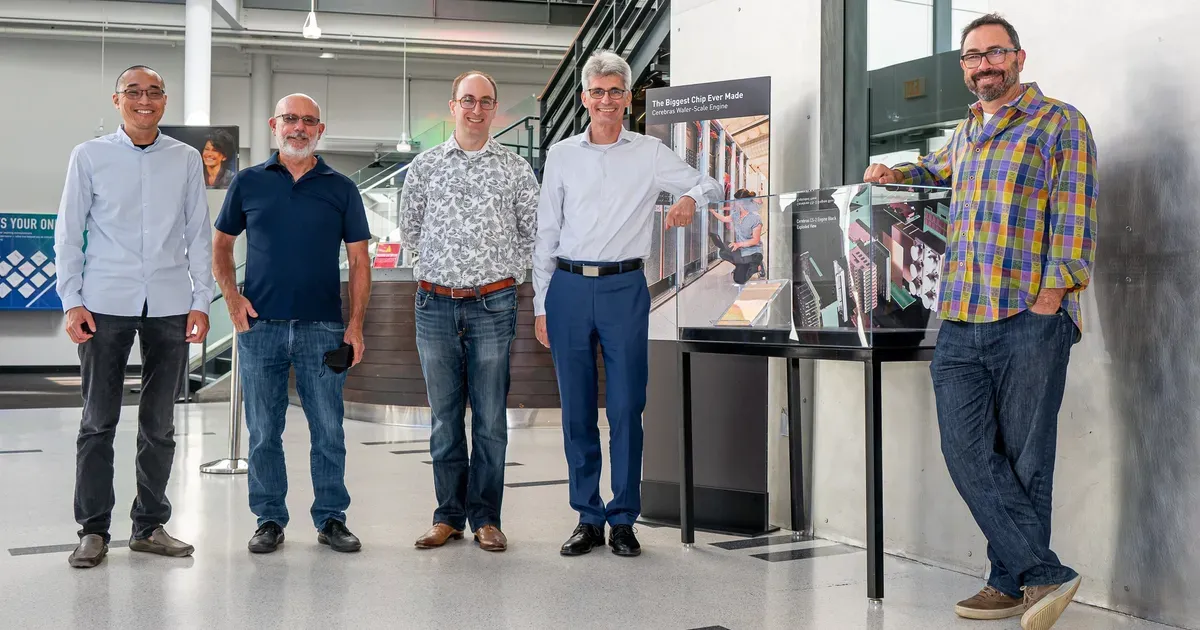 Cerebras Wafer-Scale Engine Inducted into the Computer History Museum - CerebrasCerebras
 Real-Time Computational Physics with Wafer-Scale Processing [updated]Cerebras
 The Cerebras AI Model Studio brings Wafer-Scale Cluster Acceleration to the Cloud - CerebrasCerebras
 Announcing the Cerebras Architecture for Extreme-Scale AI - CerebrasCerebras
 Visualizing Knowledge at Lightning Speed with Cerebras at Tako - CerebrasCerebras
 Breaking the Boundaries of Presence: Delphi's Digital Mind TechnologyCerebras
 How we grew Mintlify by doing things that don't scaleMintlify
 5 Reasons to Keep Contributing to Open-Source Projects - Deepgram Blog ⚡️Deepgram
 Redis Achieves ISO 27001 Cybersecurity CertificationRedis
 How to implement AI training for employeesZapier
 Pancakes Are Delicious and Data Centers Are for Free StuffThenewstack
 Flockport: Time to Start All Over Again and Return to LXC ContainersThenewstack
 Transform and Future-Proof Your Architecture with MACHThenewstack
 Selecting the Right Database for Your MicroservicesThenewstack
 The App Engine SDK and workspaces (GOPATH) - The Go Programming LanguageGo
Go on App Engine: tools, tests, and concurrency - The Go Programming LanguageGo
 Introducing: H100s on ModalModal
 Simulating Human Behavior with Cerebras - CerebrasCerebras
 100x Defect Tolerance: How Cerebras Solved the Yield Problem - CerebrasCerebras
 Cerebras Announces Six New AI Datacenters Across North America and Europe to Deliver Industry’sCerebras
