
Compressing KV cache memory by half with sparse attention
Cerebras powers the world's fastest AI inference on the biggest wafer chip. Cerebras CS-4 delivers up to 30x faster inference than GPUs.

 Memo-ry: Simplifying Daily Tasks for People with Memory Loss - CerebrasCerebras
 Visualizing Knowledge at Lightning Speed with Cerebras at Tako - CerebrasCerebras
 Breaking the Boundaries of Presence: Delphi's Digital Mind TechnologyCerebras
 Training Multi-Billion-Parameter Models on a Single Cerebras System is Easy - CerebrasCerebras
 Revolutionizing Life Science and Healthcare with Generative AI - CerebrasCerebras
 Cerebras Breaks Exascale Record for Molecular Dynamics Simulations - CerebrasCerebras
 The Go Memory Model - The Go Programming LanguageGo
 What is a Load/Store Unit?Modal
 Do AI Agents Need a Semantic Layer?Motherduck
 Docker Desktop 4.23: Updates to Docker Init, New Configuration Integrity Check, Quick SearchDocker
What is Global Memory?Modal
What is Memory Coalescing?Modal
 Memory snapshots: Checkpoint/restore for sub-second startupModal
What is Tensor Memory?Modal
 GPU Memory Snapshots: Supercharging sub-second startupModal
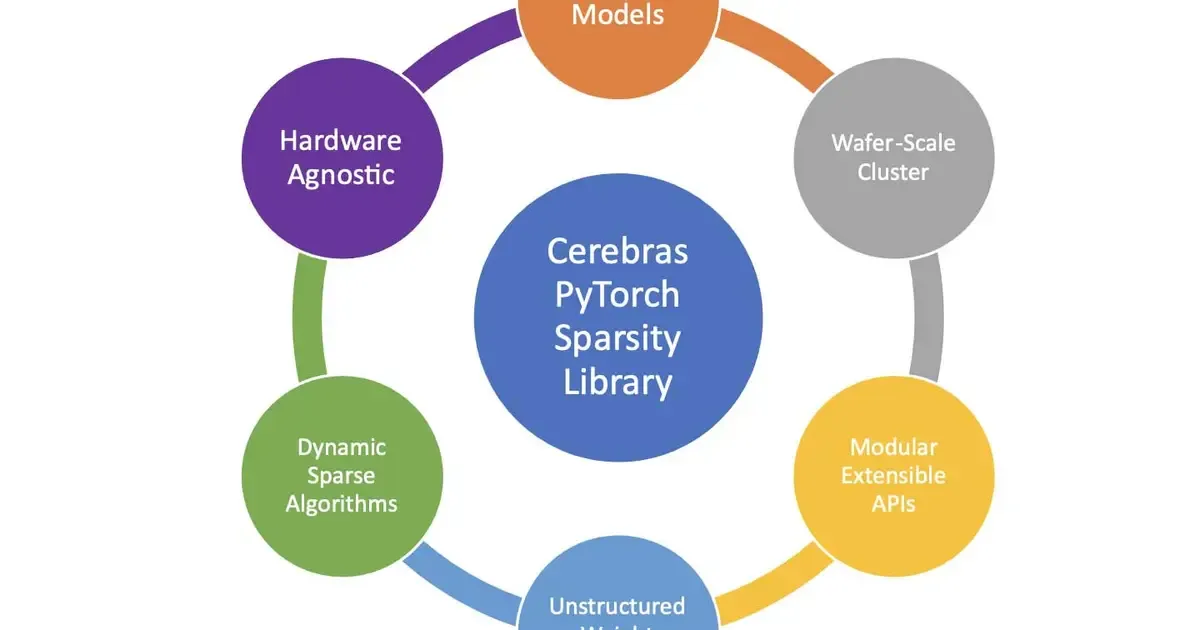 Sparsity Made EasyCerebras
 Introducing bunny.net Perma-Cache - Permanent CDN CachingBunny
 Introducing CDN Vary Cache By Cookie ValueBunny
 Vary This, Vary That - Introducing New Custom Query Parameter Vary Cache SettingsBunny
 Vercel Data Cache: A progressive cache, integrated with Next.jsVercel
