
Dolphin - Efficient Data Curation at Cognitive Computations with Cerebras - Cerebras
Cerebras powers the world's fastest AI inference on the biggest wafer chip. Cerebras CS-4 delivers up to 30x faster inference than GPUs.
 Visualizing Knowledge at Lightning Speed with Cerebras at Tako - CerebrasCerebras
 Breaking the Boundaries of Presence: Delphi's Digital Mind TechnologyCerebras
 Training Multi-Billion-Parameter Models on a Single Cerebras System is Easy - CerebrasCerebras
 Revolutionizing Life Science and Healthcare with Generative AI - CerebrasCerebras
 Cerebras Breaks Exascale Record for Molecular Dynamics Simulations - CerebrasCerebras
 The rise of slow personal assistantsCerebras
 Cloud Security Trends & Challenges: Complete GuideCybersecurity Exchange
 State of Speech: Our New Data Report Reveals ASR’s Untapped Potential - Deepgram Blog ⚡️Deepgram
 Build a Presentation Coaching Application with Recall - Deepgram Blog ⚡️Deepgram
 The Most Important Work in AI Training Is Also the Most Overlooked - Deepgram Blog ⚡️Deepgram
 Data Ingestion: 6 Ways to Speed Up Your ApplicationRedis
 5 ways to automate Browse AIZapier
 How to connect Google Sheets to NotionZapier
 Pancakes Are Delicious and Data Centers Are for Free StuffThenewstack
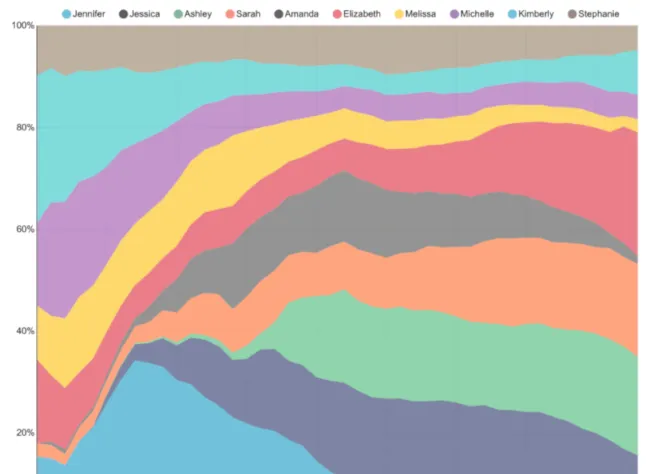 Explore and Visualize Data the Apache Superset WayThenewstack
 Go Concurrency Patterns: Pipelines and cancellation - The Go Programming LanguageGo
 Data connections - FeaturesJetbrains
 How a top tier European soccer team sped up their data processing and reduced costs by 50%Modal
 What is a Load/Store Unit?Modal
 Anthropic integration with Modal brings scalable compute to Claude ScienceModal
