
Blogs
How Cerebras serves GPT-5.6 Sol at up to 750 tokens per second
Learn how Cerebras serves OpenAI’s GPT-5.6 Sol at up to 750 output tokens per second—without shrinking the model or compromising intelligence.
 BlogsWhy Cyber Defense Needs Faster InferenceCerebras
BlogsAnnouncing Cerebras Cloud @ Cirrascale, Democratizing High-Performance AI Compute - CerebrasCerebras
BlogsLinear Scaling Made Possible with Weight Streaming - CerebrasCerebras
BlogsCerebras May 2025 NewsletterCerebras
Products & ServicesCustomizing your site with themes, styles, and tokensGitbook
Products & ServicesGitBook 3.0: Document everything, from start to shipGitbook
BlogsWhat a $20 Claude Code or Codex subscription actually buys, per ApertureTailscale
ResourcesAdvanced BotID ConfigurationVercel
BlogsAutomating Design Systems: Tips And Resources For Getting StartedSmashingmagazine
BlogsAI Adoption for National Security | CohereCohere
NewsCerebras Systems Announces Pricing of Initial Public OfferingCerebras
BlogsIntroducing OpenAI gpt-oss (20b & 120b)Fireworks
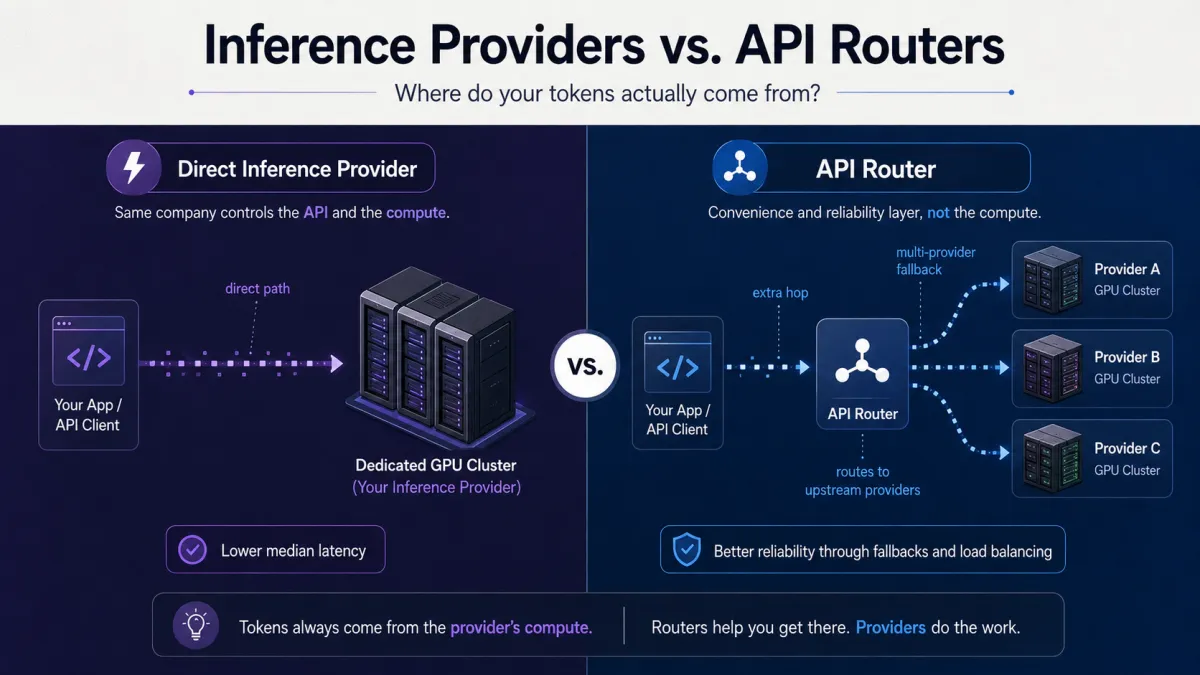 BlogsInference Providers vs. API Routers: Where Do Your Tokens Actually Come From?Fireworks
BlogsYouTube Shorts AI Avatars vs Digital Twin: ComparedHeygen
BlogsControl Planes for Database-Per-User in Neon - NeonNeon
BlogsIntegrating Design And Code With Native Design Tokens In PenpotSmashingmagazine
BlogsKeyframes Tokens: Standardizing Animation Across ProjectsSmashingmagazine
BlogsCohere Adds $100M in Second Close of Latest Round | CohereCohere
