
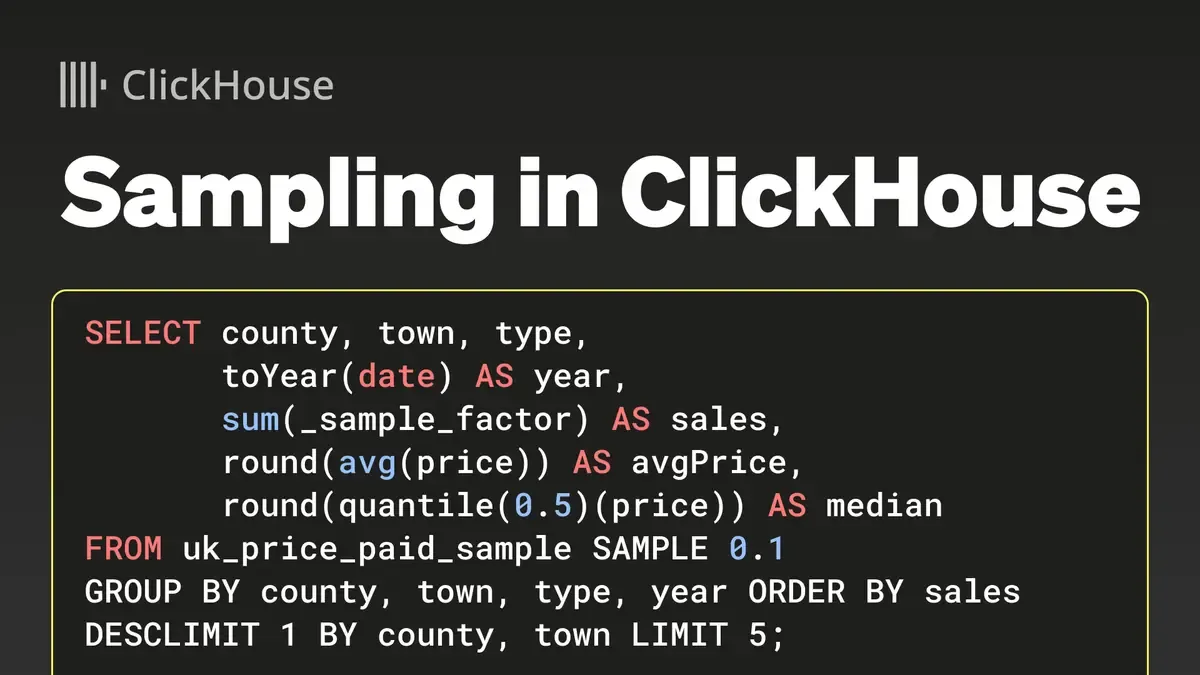
Native random sampling in ClickHouse
Learn how to use ClickHouse's SAMPLE BY clause to run fast, approximate queries on large datasets with minimal accuracy trade-off.
 Formats for input and output data - ClickHouse DocumentationClickhouse
DataStore accessors - ClickHouse DocumentationClickhouse
Embedded in ClickHouse - ClickHouse DocumentationClickhouse
Performance guide - ClickHouse DocumentationClickhouse
 DataStore Query building - ClickHouse DocumentationClickhouse
SQL reference - ClickHouse DocumentationClickhouse
 Mintlify Alternatives: What to Consider (and Why There's No True Substitute)Mintlify
 Happy National Native American Heritage Month! - Deepgram Blog ⚡️Deepgram
 This Week in Programming: Who's Headed to KubeCon?Thenewstack
 Puppet’s New Mission: Automating Cloud Native InfrastructureThenewstack
 Pulumi ESC and External Secrets Operator: The Perfect Solution for TodayPulumi
 The Serverless Backend for Analytics: Introducing MotherDuck’s Native Integration on VercelMotherduck
 Linux and Cloud Native Security: AlmaLinuxThenewstack
 Supply Chain Attacks and Cloud Native: What You Need to KnowThenewstack
 Rev Up Your Cloud-Native Journey: Join Docker at KubeCon + CloudNativeCon EU 2024 for InnovationDocker
 Configure OBI OpenTelemetry trace samplingOpentelemetry
Configure OBI Prometheus and OpenTelemetry metrics histogramsOpentelemetry
 Kubernetes-Run Analytics at the Edge: Postgres, Kafka, DebeziumThenewstack
 Kubernetes SDKs from the PulumiversePulumi
 Pulumi Kubernetes Operator 1.0Pulumi
