
Efficient LLM Finetuning with T-Few
We delve into the concept of T-Few finetuning, explore its benefits, and explain our implementation workflow.
 Build a Presentation Coaching Application with Recall - Deepgram Blog ⚡️Deepgram
 Introducing DocChat: GPT-4 Level Conversational QA Trained In a Few Hours - CerebrasCerebras
 Docker at Cloud Expo Asia: GenAI, Security, and New InnovationsDocker
 You can just ship agentsVercel
 Autogenerating API documentation from OpenAPIMintlify
 Enhancing Pulumi Copilot: Introducing System Prompts for Your OrganizationPulumi
 Product updates: Running batch jobs with 1M inputs, ephemeral apps, and a new TensorRT-LLM exampleModal
 Beating proprietary models with a quick fine-tuneModal
 The Cost of Javascript Frameworks | CSS-TricksCss Tricks
 Cerebras Systems and National Energy Technology Laboratory Set New Milestones for High-PerformanceCerebras
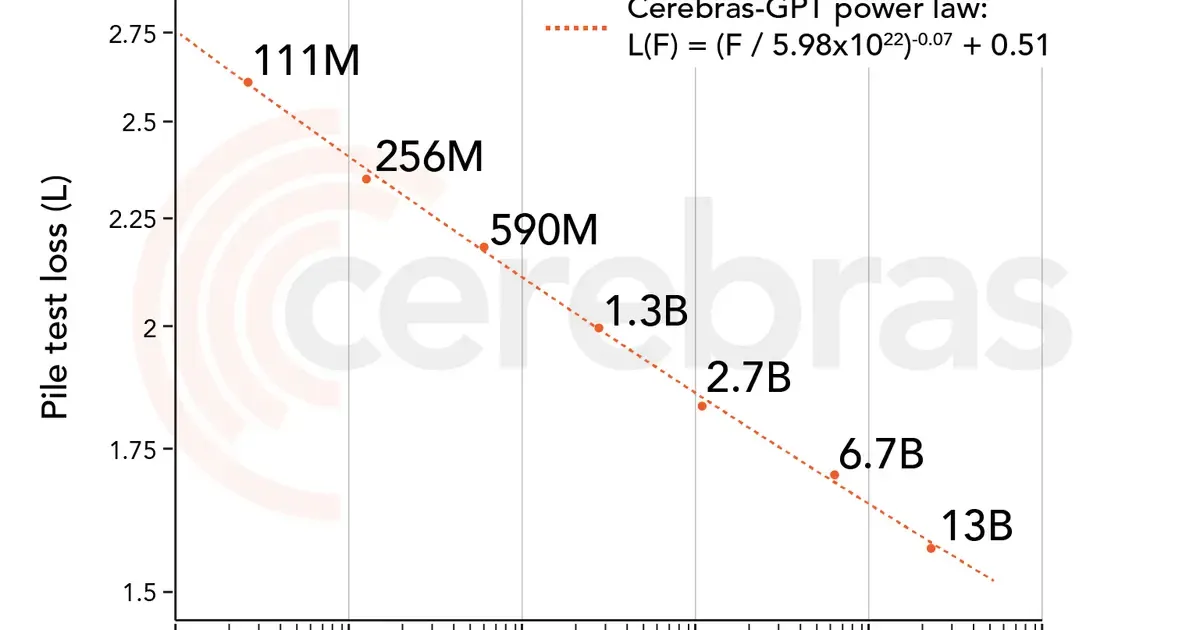 Cerebras-GPT: A Family of Open, Compute-efficient, Large Language Models - CerebrasCerebras
 Introducing Origin Shield Concurrency Limits and QueueingBunny
 How BunnyCDN shredded the size of your text files by 10-20% with BrotliBunny
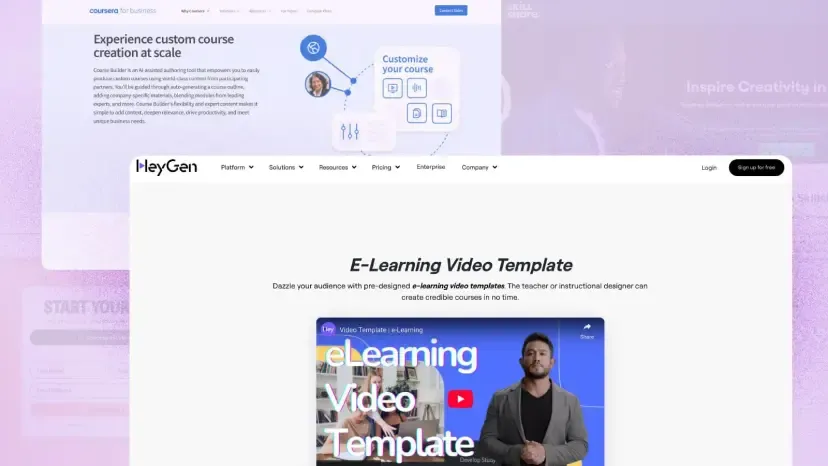 AI Video Generators for BusinessHeygen
