
Shared vs. Dedicated AI Inference: Embed & Rerank
Learn how embedding and reranking workloads, traffic patterns, latency, and cost determine the right deployment choice.
 The rise of slow personal assistantsCerebras
 Simulating Human Behavior with Cerebras - CerebrasCerebras
 100x Defect Tolerance: How Cerebras Solved the Yield Problem - CerebrasCerebras
 Cerebras Announces Six New AI Datacenters Across North America and Europe to Deliver Industry’sCerebras
 AMD and Cerebras Announce Disaggregated AI InferenceCerebras
 Cerebras Systems, Ranovus win $45 million US military deal to speed up chip connectionsCerebras
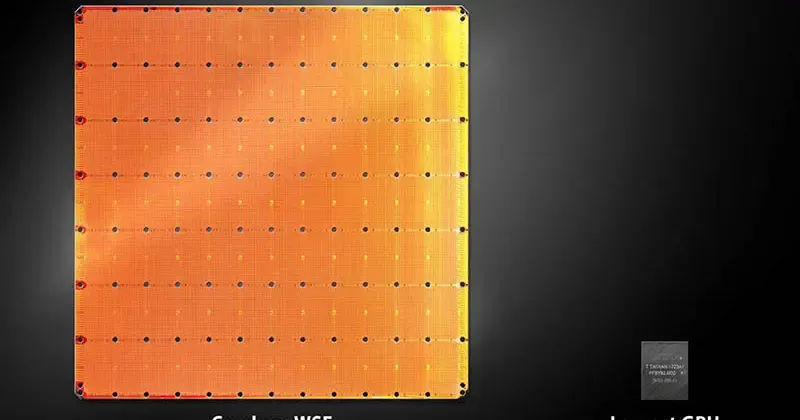 Cerebras Systems Unveils the Industry’s First Trillion Transistor Chip - CerebrasCerebras
 Cerebras Systems Raises $250M in Funding for Over $4B Valuation to Advance the Future of ArtificialCerebras
 GitHub - MintlifyMintlify
 Credit pricing - MintlifyMintlify
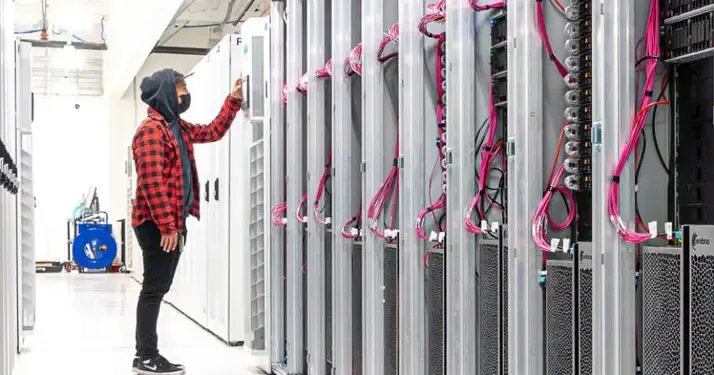 The Cerebras AI Model Studio brings Wafer-Scale Cluster Acceleration to the Cloud - CerebrasCerebras
 Cerebras Is Coming to AWS Bedrock for Fast AI InferenceCerebras
Cerebras Systems Announces Filing of Registration Statement for Proposed Initial Public OfferingCerebras
 Gemma 4 on Cerebras—The Fastest Inference is Now MultimodalCerebras
