
Advanced Prompt Caching at Scale
Learn how to scale prompt caching across LLM replicas with session affinity, tiered routing, and prefix-aware load balancing to cut latency and inference costs.
 How we grew Mintlify by doing things that don't scaleMintlify
 How to implement AI training for employeesZapier
 Pancakes Are Delicious and Data Centers Are for Free StuffThenewstack
 Transform and Future-Proof Your Architecture with MACHThenewstack
 Selecting the Right Database for Your MicroservicesThenewstack
 Summer Data Engineering RoadmapMotherduck
 Real-Time Computational Physics with Wafer-Scale Processing [updated]Cerebras
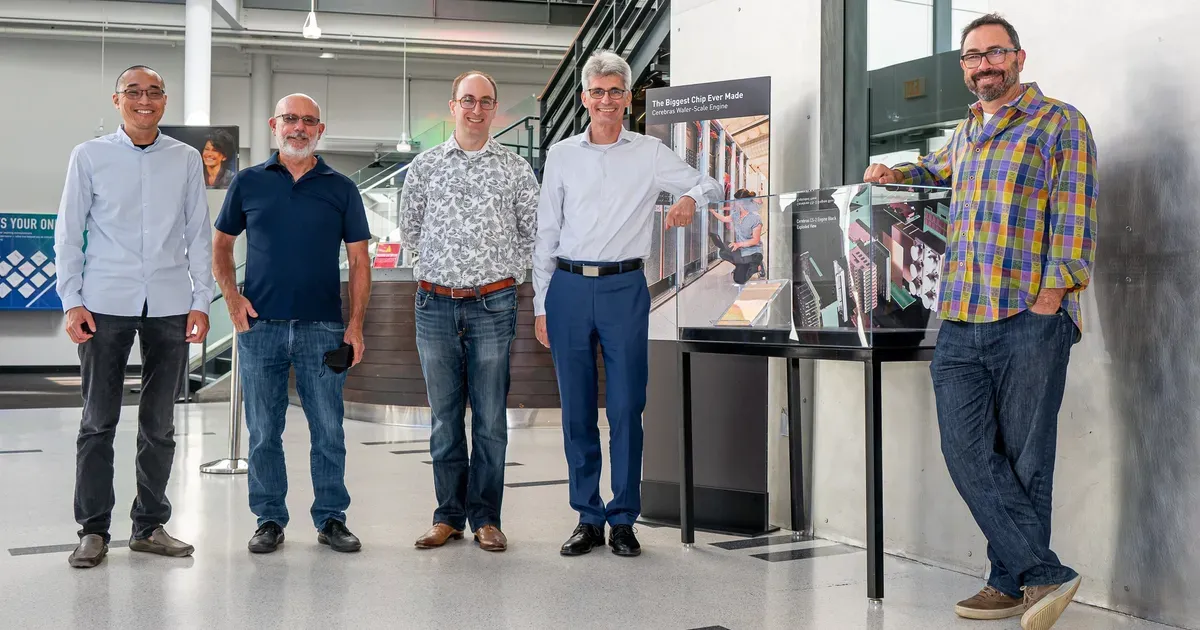 Cerebras Wafer-Scale Engine Inducted into the Computer History Museum - CerebrasCerebras
 AMD and Cerebras Announce Disaggregated AI InferenceCerebras
 A prompt guide to get the most out of HeyGen's new Video AgentHeygen
 How to Make AI Videos Look Professional in 2025Heygen
 20 Must-Attend Startup Events in San Francisco 2025 | HeyGenHeygen
 Creating an AI Summary App with Next.js | Vercel AcademyVercel
 From Hawking to Siri: The Evolution of Speech SynthesisDeepgram
