
Blogs
DigitalOcean Gradient™ AI GPU Droplets Optimized for Inference: Increasing Throughput at Lower the
We cover the optimization stack, the engineering reasoning behind each layer, and the benchmark methodology and our test results showing these gains.
 How to serve trillions of tokens for trillion-parameter coding agentsModal
 What is a Load/Store Unit?Modal
 Product updates: Datadog integration, lower function latency & moreModal
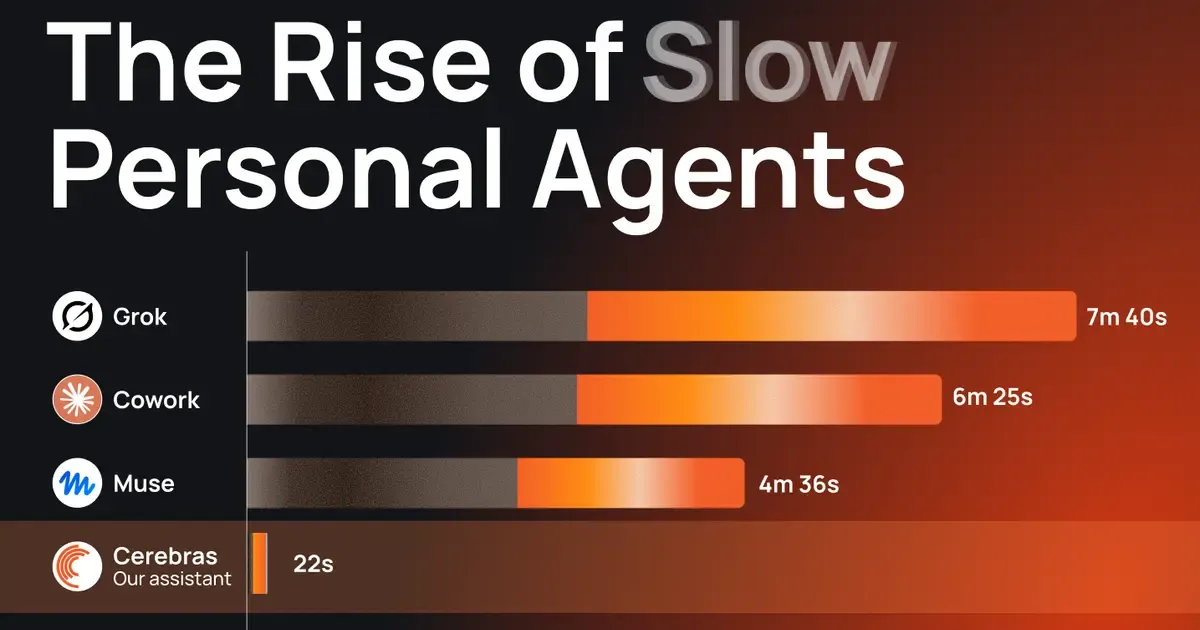 The rise of slow personal assistantsCerebras
 Simulating Human Behavior with Cerebras - CerebrasCerebras
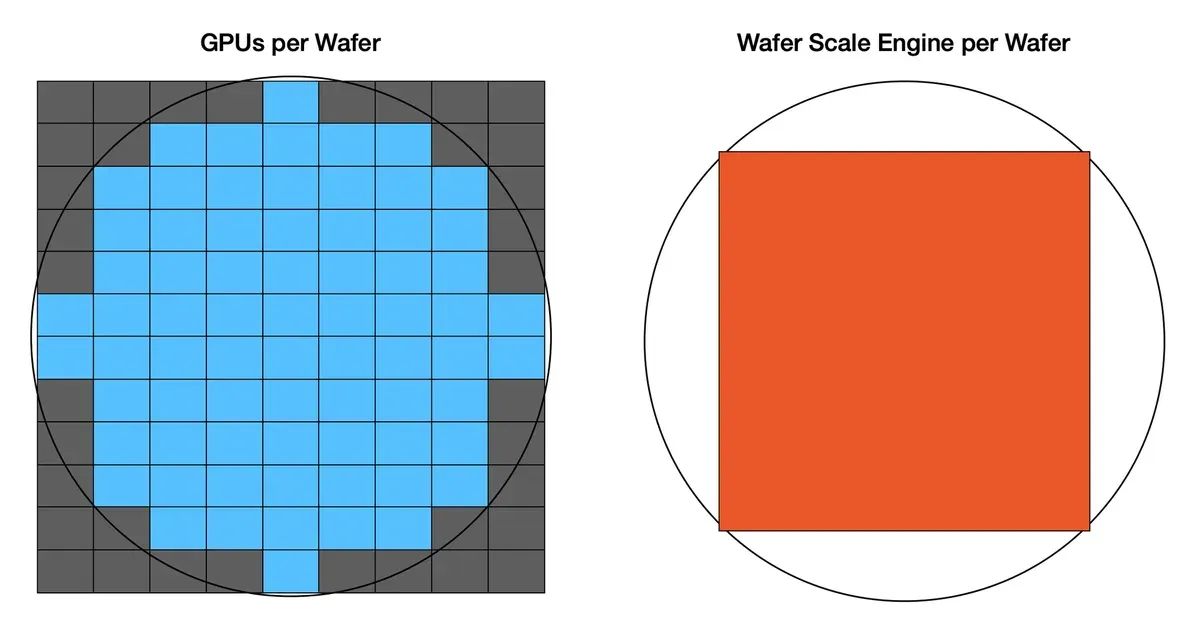 100x Defect Tolerance: How Cerebras Solved the Yield Problem - CerebrasCerebras
 Cerebras Announces Six New AI Datacenters Across North America and Europe to Deliver Industry’sCerebras
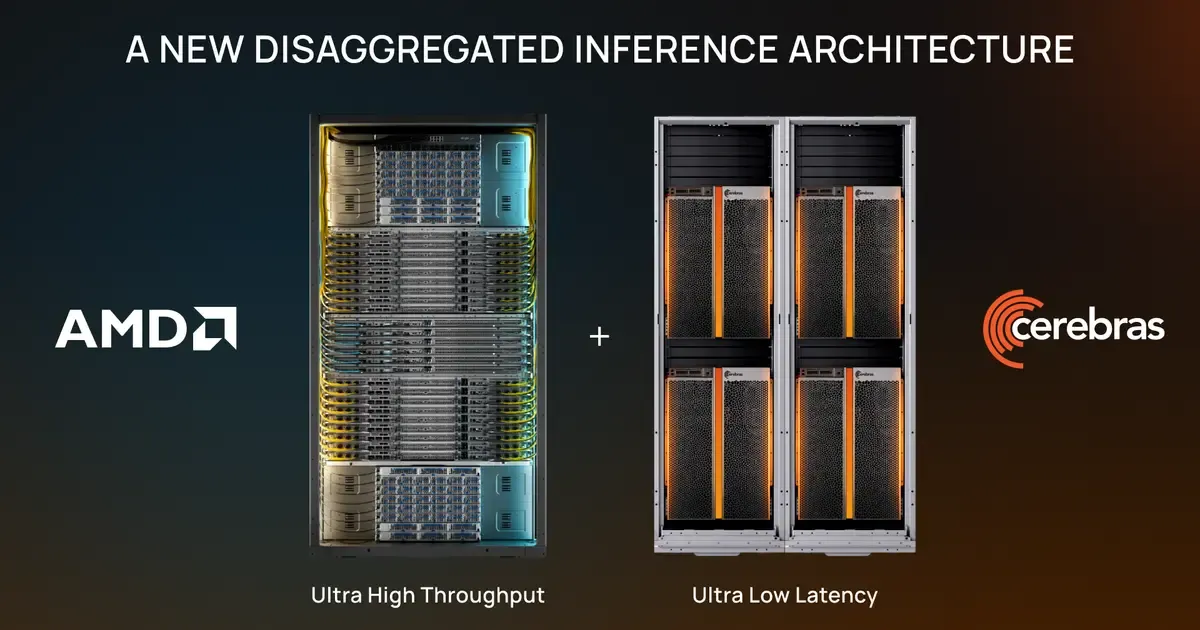 AMD and Cerebras Announce Disaggregated AI InferenceCerebras
Cerebras Systems Enables GPU-Impossible™ Long Sequence Lengths Improving Accuracy in NaturalCerebras
 Cerebras Systems, Ranovus win $45 million US military deal to speed up chip connectionsCerebras
 Cerebras Systems Raises $250M in Funding for Over $4B Valuation to Advance the Future of ArtificialCerebras
What is a Tensor Core?Modal
 GPU Memory Snapshots: Supercharging sub-second startupModal
 Run GPU jobs from Airflow with ModalModal
