
Blogs
The LLM Inference Trilemma: Throughput, Latency, Cost
Learn how to navigate the three-way tradeoff between throughput, latency, and cost when serving LLMs, with a practical framework for tuning deployments.
 Tagalog Speech to TextDeepgram
 Unpacking sandbox startup latency: why started ≠ readyModal
 Sidecars: A low-latency trust boundary for SandboxesModal
 Product updates: Datadog integration, lower function latency & moreModal
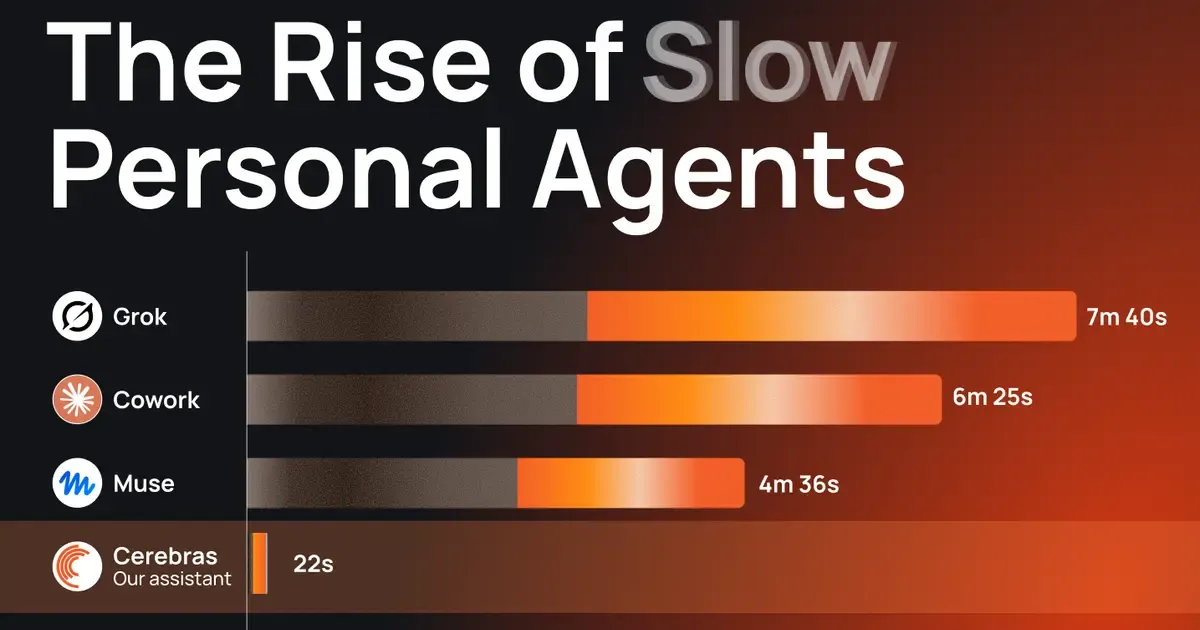 The rise of slow personal assistantsCerebras
 Simulating Human Behavior with Cerebras - CerebrasCerebras
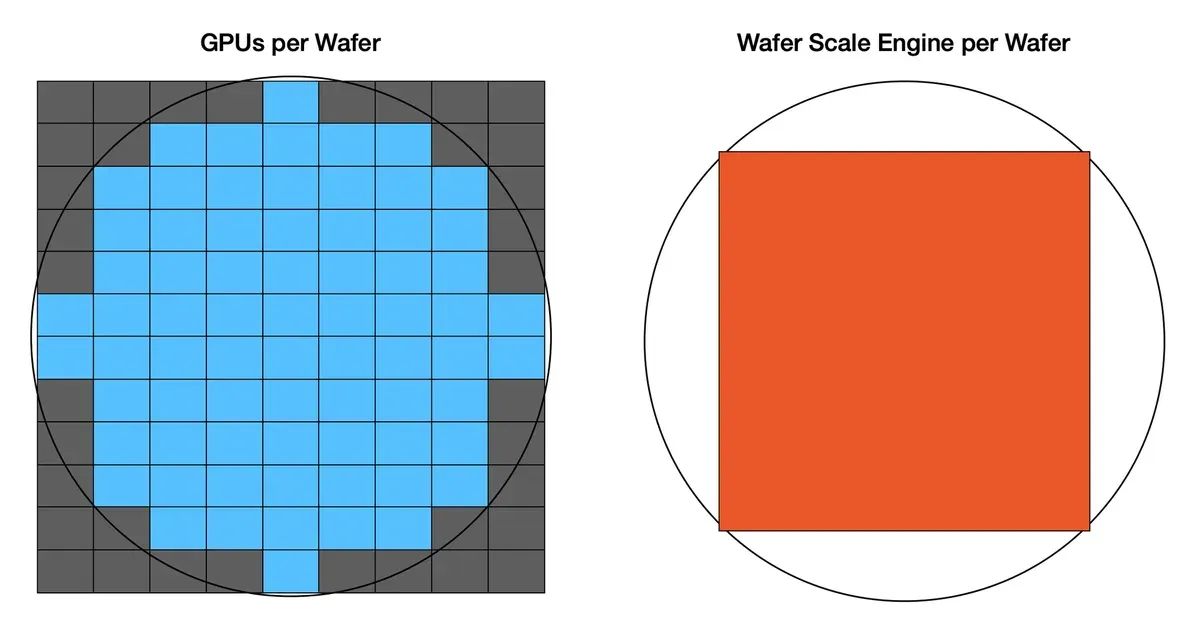 100x Defect Tolerance: How Cerebras Solved the Yield Problem - CerebrasCerebras
 Cerebras Announces Six New AI Datacenters Across North America and Europe to Deliver Industry’sCerebras
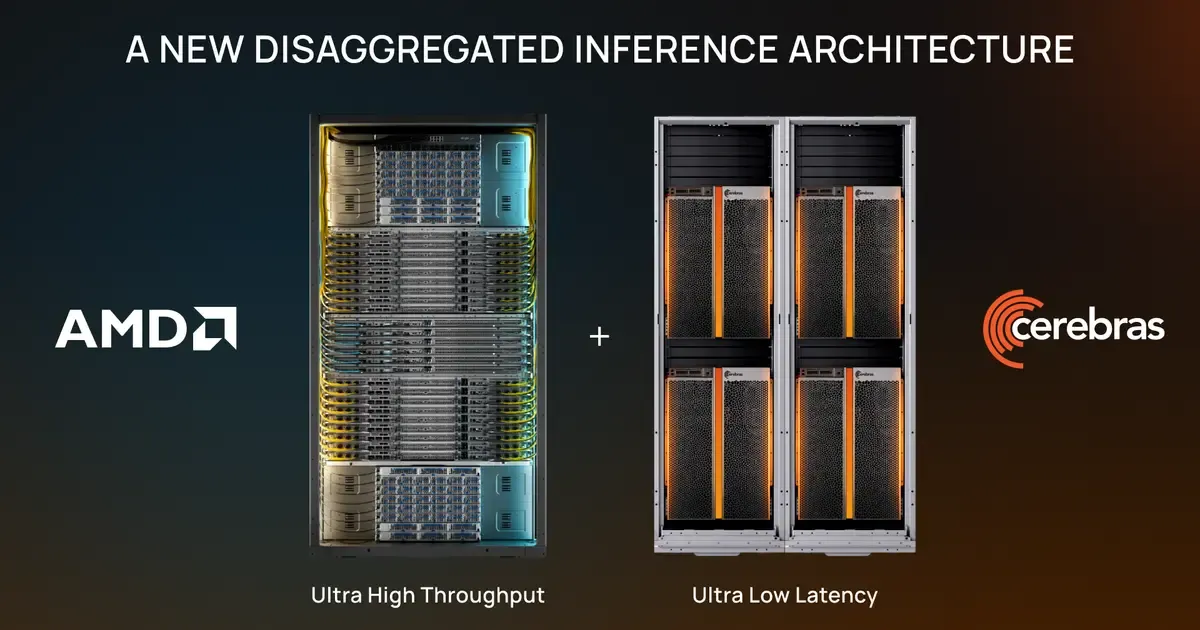 AMD and Cerebras Announce Disaggregated AI InferenceCerebras
 Cerebras Systems, Ranovus win $45 million US military deal to speed up chip connectionsCerebras
 Cerebras Systems Raises $250M in Funding for Over $4B Valuation to Advance the Future of ArtificialCerebras
 AI's Role in Video Marketing, Cost EfficiencyHeygen
 You can just ship agentsVercel
Real-Time Speech-to-Speech Translation: Architecture GuideDeepgram
