
Blogs
Accelerating Code Completion with Fireworks Fast LLM Inference
At Fireworks.ai, we provide the world's fastest LLM inference platform which enables developers to run, fine-tune, deploy, and share large language models (LLMs).
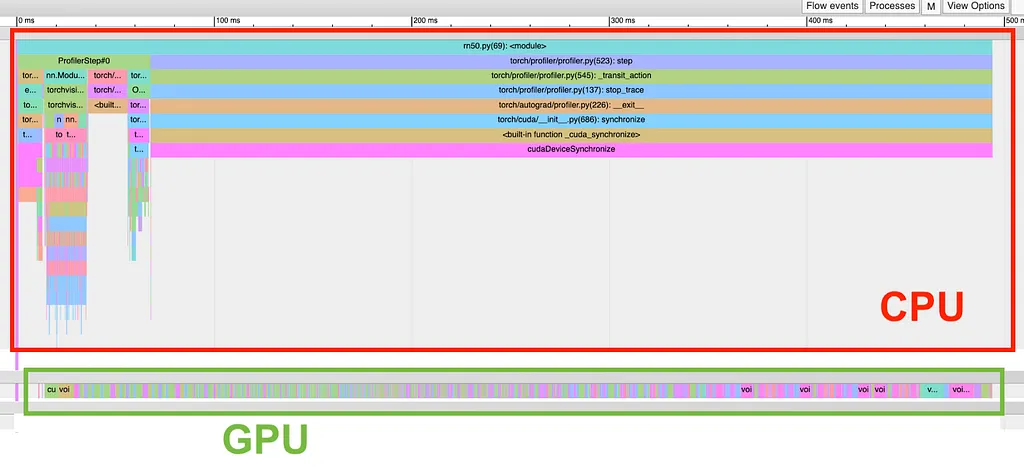 BlogsSpeed, Python: Pick Two. How CUDA Graphs Enable Fast Python Code for Deep LearningFireworks
BlogsSimplifying Code Infilling with Code Llama and Fireworks.aiFireworks
BlogsGLM 5.2 Fast is live on FireworksFireworks
BlogsThe Best 8 LLM API Providers in 2026Fireworks
BlogsIntroducing Fireworks on Microsoft Foundry: Bringing Best-in-Class Open Model inference to AzureFireworks
 BlogsInference Providers vs. API Routers: Where Do Your Tokens Actually Come From?Fireworks
EventsQuacking the Code to Multi-Tenant Embedded Analytics with GoodData & MotherDuckMotherduck
NewsAleph Alpha Selects Cerebras to Build Next-Gen Sovereign AI Models - CerebrasCerebras
BlogsCerebras Is Coming to AWS Bedrock for Fast AI InferenceCerebras
 NewsCerebras Systems Announces Filing of Registration Statement for Proposed Initial Public OfferingCerebras
BlogsGemma 4 on Cerebras—The Fastest Inference is Now MultimodalCerebras
ResourcesCalling Java from KotlinKotlinlang
BlogsAccelerating New Features in Docker DesktopDocker
Blogswith JupyterLab as a Docker ExtensionDocker
BlogsTrue planetary-scale storage is here! Hello Johannesburg!Bunny
BlogsHow to write technical documentation that developers actually useMintlify
BlogsBest Internal Documentation Tools for Engineering Teams (2026)Mintlify
Products & ServicesPolish Speech to Text API | Fast & Accurate Transcription | DeepgramDeepgram
Products & ServicesUkrainian Speech to Text API | Fast & Accurate Transcription | DeepgramDeepgram
Products & ServicesMalay Speech to Text API | Fast & Accurate Transcription | DeepgramDeepgram
