
Blogs
Deep-Dive into LLM Fine-Tuning
LLM fine-tuning improves accuracy, speed, and cost efficiency for specialized use cases. Get in-depth guidance for optimal fine-tuning with Fireworks.
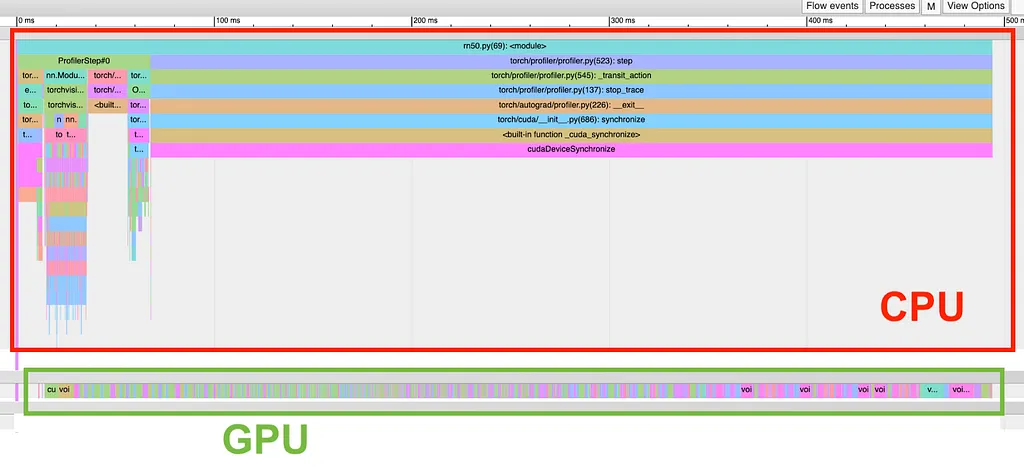 BlogsSpeed, Python: Pick Two. How CUDA Graphs Enable Fast Python Code for Deep LearningFireworks
BlogsLLM on the edge: Model picking with Fireworks Eval Protocol + OllamaFireworks
BlogsOpen, frontier, and yours: LangChain Deep Agents on NVIDIA Nemotron 3 Ultra, running on FireworksFireworks
BlogsStructured memory management for AI Applications and AI Agents with DuckDBMotherduck
BlogsBest Practices for Multi-Turn RLFireworks
BlogsWhy do all LLMs need structured output modes?Fireworks
BlogsFrontier-lab training infrastructure, now as a serviceFireworks
BlogsGLM 5.2 Fast is live on FireworksFireworks
BlogsIntroducing OpenAI gpt-oss (20b & 120b)Fireworks
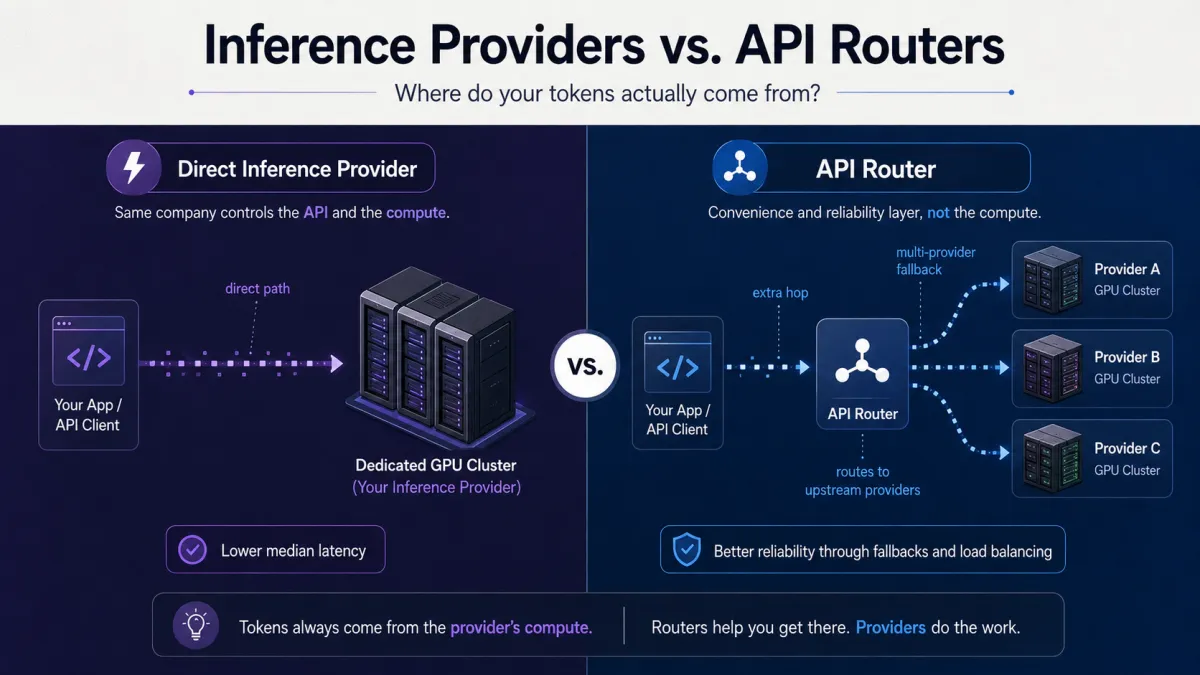 BlogsInference Providers vs. API Routers: Where Do Your Tokens Actually Come From?Fireworks
BlogsBuild a Talking Halloween Skeleton with Docker Model RunnerDocker
BlogsEasier Postgres fine-tuning with online_advisor - NeonNeon
BlogsBuilding a Deep Research Agent with Neon and Durable Endpoints - NeonNeon
ResearchLLM See, LLM Do: Guiding Data Generation to Target Non-Differentiable ObjectivesCohere
ResearchSparkles: Unlocking Chats Across Multiple Images for Multimodal Instruction-Following ModelsCohere
EventsThe Dive — MotherDuck at Snowflake Summit 2026 | In-Person Event | MotherDuck EventsMotherduck
BlogsAI That Quacks: Introducing DuckDB-NSQL-7B, A LLM for DuckDB SQLMotherduck
