
Blogs
FireAttention V3: Enabling AMD as a viable alternative for GPU inference
This time we are going to focus on a different GPU hardware, namely AMD MI300 GPU. While spec-wise it looks quite superior to NVIDIA H100 GPU we never know how it’s going to perform in real-world LLM inference settings until we run benchmarks, which represent practical LLM usage.
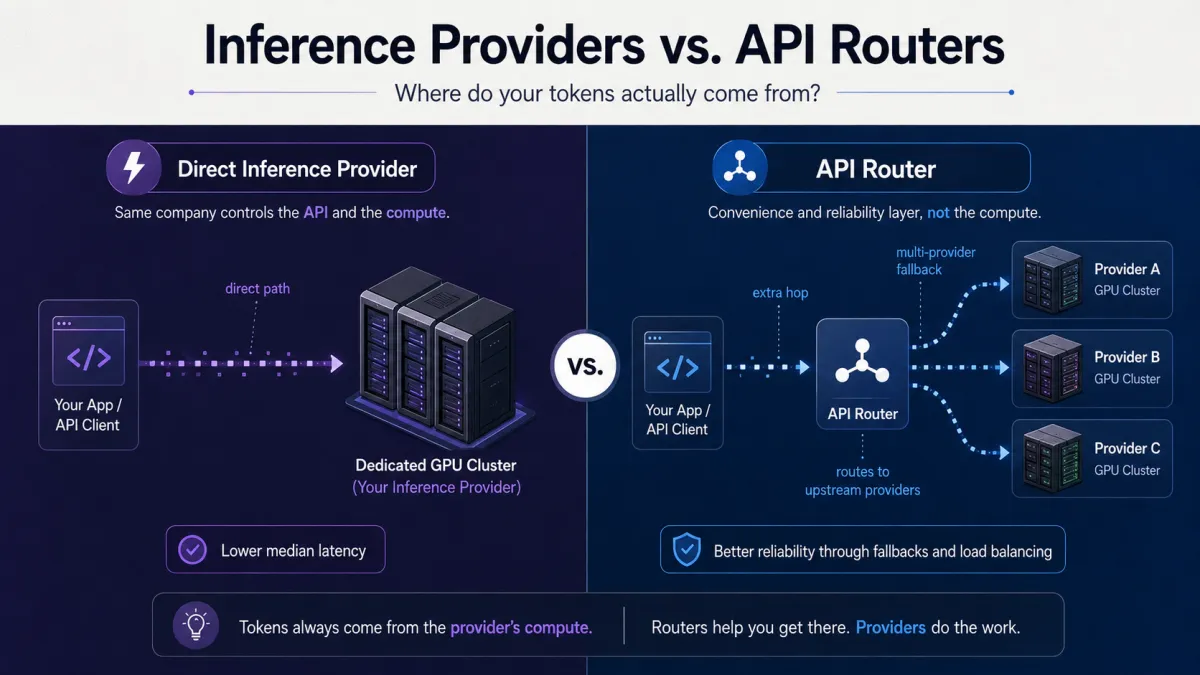 BlogsInference Providers vs. API Routers: Where Do Your Tokens Actually Come From?Fireworks
BlogsDeepSeek V4 Pro: Validating Frontier Models for ProductionFireworks
BlogsQwen 3.7 Plus is now live on FireworksFireworks
BlogsFireLLaVA: the first commercially permissive OSS LLaVA modelFireworks
NewsHow I Built an On-Premises AI Training Testbed with Kubernetes and KubeflowThenewstack
BlogsSecure Networking with Tailscale and Custom OIDC IntegrationTailscale
BlogsTranscribing on Fly GPU MachinesFly
BlogsThe 4 best ChatGPT alternatives in 2026 | ZapierZapier
BlogsEverything You Always Wanted to Know About Type Inference - And a Little Bit MoreGo
BlogsHow Eisan made POS analytics faster, cheaper, and more reliable with ClickHouse CloudClickhouse
BlogsSpeeding up GPU kernels by 38% with a multi-agent system · CursorCursor
BlogsCSS @scope: An Alternative To Naming Conventions And Heavy AbstractionsSmashingmagazine
ResearchThe Culture Funnel: You can’t align what isn’t in the dataCohere
ResearchBidirLM: From Text to Omnimodal Bidirectional Encoders by Adapting and Composing Causal LLMsCohere
BlogsDo you still need Elasticsearch for log analytics? ClickHouse says no.Clickhouse
BlogsHumanizing Digital Technology with NorbyCerebras
 BlogsWhy Cyber Defense Needs Faster InferenceCerebras
NewsAWS and Cerebras Collaboration Aims to Set a New Standard for AI Inference Speed and Performance inCerebras
