
Blogs
How Fireworks evaluates quantization precisely and interpretably
With the release of Llama 3.1, there’s been considerable discussion about the benefits and tradeoff of different quantization methods.
 BlogsFireworks Dev Day 2025 WrappedFireworks
BlogsOptimizing Retrieval Augmented Generation (RAG) with MongoDB Atlas and FireworksFireworks
BlogsFine-Tuning DeepSeek v3 & R1 to optimize quality, latency, & costFireworks
 BlogsMeet DeepL: What to expect in our Culture & Values interviewDeepL
 ResourcesLambda Functionsduckdb.org
 Products & ServicesAnalyst Reportsopensearch.org
 Products & ServicesYou can style alt text like any other textcss-tricks.com
 NewsU.S. officials wary of fake voter fraud stories hitting social mediacyberscoop.com
 NewsHow to improve threat detection in ICS environmentscyberscoop.com
 NewsPatagonia lawsuit raises thorny GenAI data issuescio.com
 Products & ServicesAWS Marketplace: Nomic Embed Text v1.5 Reviewsaws.amazon.com
 ResourcesGeneral | GraphQLcodecademy.com
ResourcesEmojicode | ↪️ Conditionalscodecademy.com
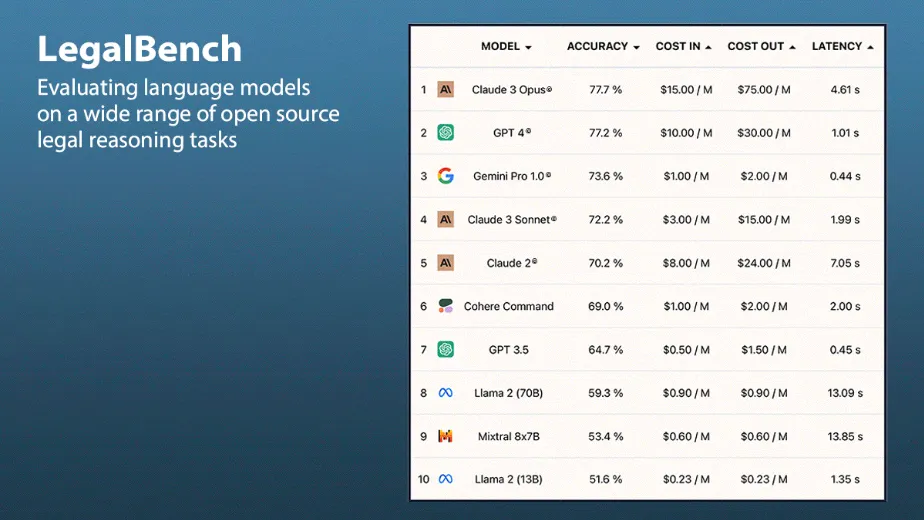 NewsVals AI Evaluates Large Language Models on Industry-Specific Tasksdeeplearning.ai
