
Blogs
Batch Processing with GroqCloud™ for AI Inference Workloads
Scale beyond speed with GroqCloud™ Batch Processing—efficiently handle massive AI workloads at enterprise scale.
 BlogsWhy Cyber Defense Needs Faster InferenceCerebras
NewsAWS and Cerebras Collaboration Aims to Set a New Standard for AI Inference Speed and Performance inCerebras
BlogsIntroducing Fireworks on Microsoft Foundry: Bringing Best-in-Class Open Model inference to AzureFireworks
BlogsAccelerate your Vision Pipelines with the new NVIDIA Nemotron Nano 2 VL Model on FireworksFireworks
 BlogsThe DeepSeek Model Lineup: V3.2, R1, and Distilled Variants Mapped to Production WorkloadsFireworks
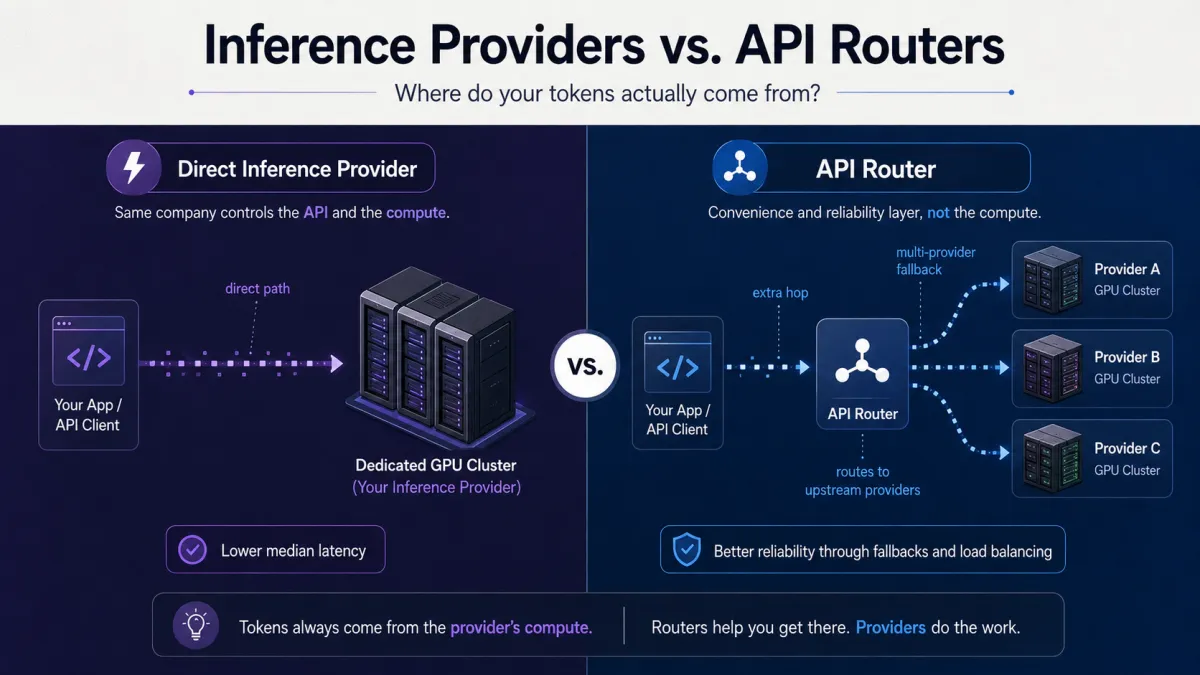 BlogsInference Providers vs. API Routers: Where Do Your Tokens Actually Come From?Fireworks
BlogsBenchmarking KubeVirt performance with virtbenchCncf
BlogsSecurity Profiles Operator v1: Stable APIs, Security Hardened, and Shaping Upstream KubernetesCncf
EventsCNCF Reveals KubeCon + CloudNativeCon North America 2026 Schedule, Adds New AI Inference + AgenticCncf
ResourcesServe structFastly
ResearchHere's a Free Lunch: Sanitizing Backdoored Models with Model MergeCohere
BlogsCerebras May 2025 NewsletterCerebras
