
Blogs
Virtualizing Our Storage Engine
Find out how virtualizing our storage engine led to significant improvement in query runtimes for bigger, more complex environments.
 The App Engine SDK and workspaces (GOPATH) - The Go Programming LanguageGo
Go on App Engine: tools, tests, and concurrency - The Go Programming LanguageGo
 Real-Time Computational Physics with Wafer-Scale Processing [updated]Cerebras
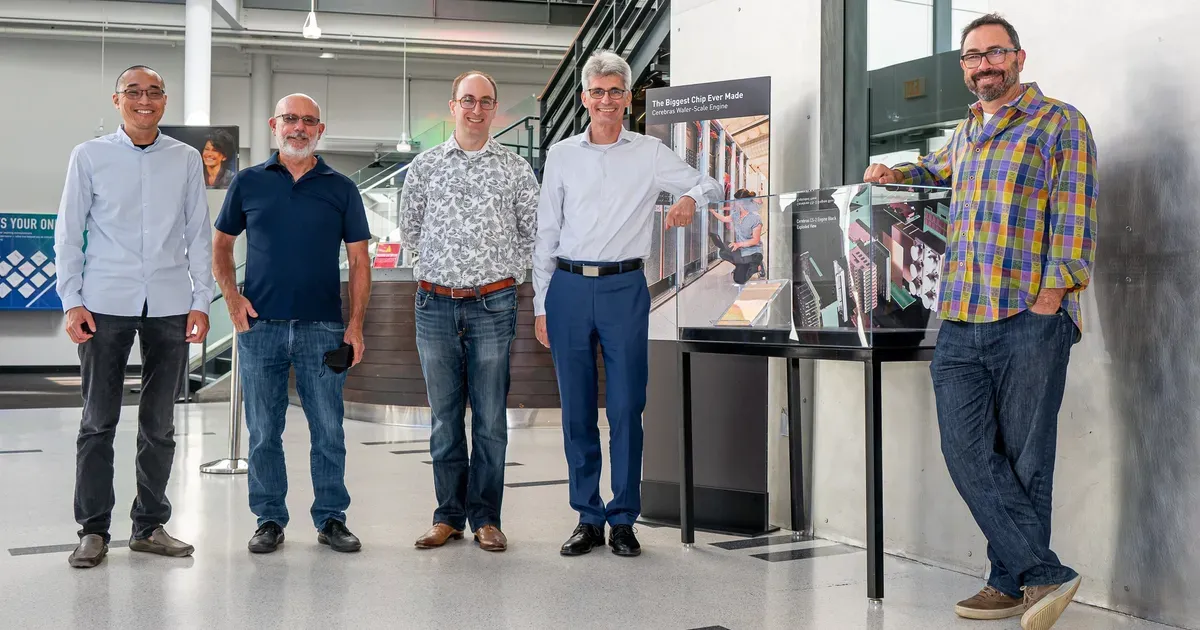 Cerebras Wafer-Scale Engine Inducted into the Computer History Museum - CerebrasCerebras
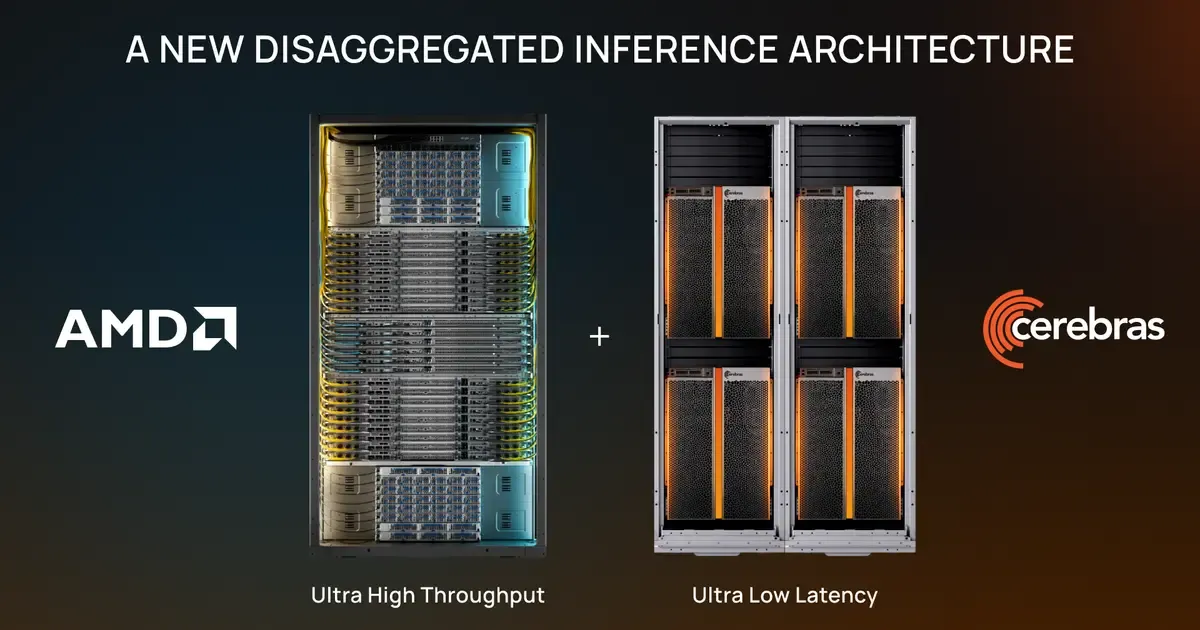 AMD and Cerebras Announce Disaggregated AI InferenceCerebras
 Capturing Logs in Docker DesktopDocker
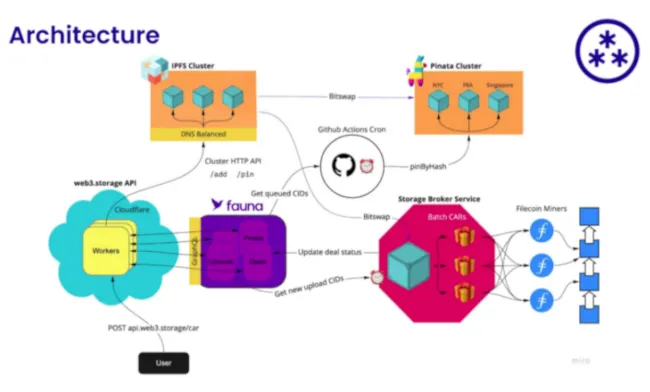 Web3.Storage: Free Decentralized Storage on FilecoinThenewstack
 Optimize Costs for Amazon S3 and Multi Cloud Object StorageDatadoghq
 Your DuckDB Flock Deserves A MotherMotherduck
 True planetary-scale storage is here! Hello Johannesburg!Bunny
 Introducing bunny.net Perma-Cache - Permanent CDN CachingBunny
 Innovation at the edge: How Edge Storage makes content delivery really hopBunny
 Storage Structure - bunny.net DocumentationBunny
 Introducing Data ExportsSocket
