
Blogs
Compute:Arena / Measuring Local Inference Across Models, Quants, Chips, and Runtimes
A Blog post by Base Compute on Hugging Face
 BlogsTransformers now runs llama.cpp quantshuggingface.co
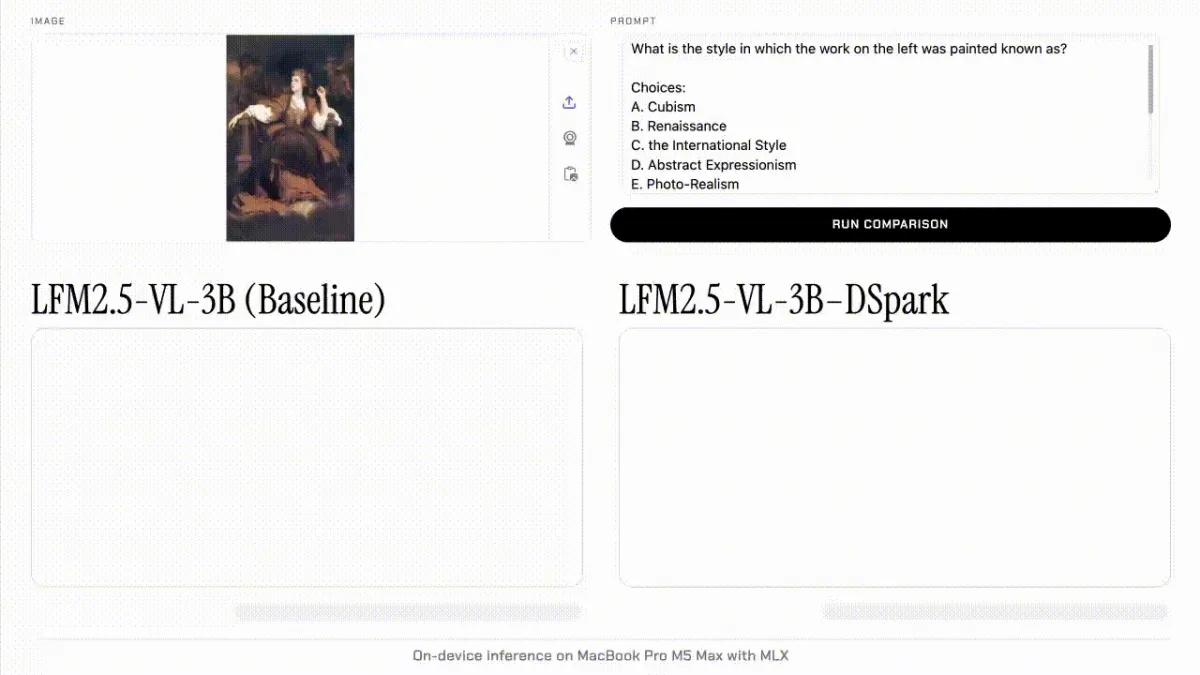 BlogsAccelerating vision-language models with LFM2.5-VL-DSparkhuggingface.co
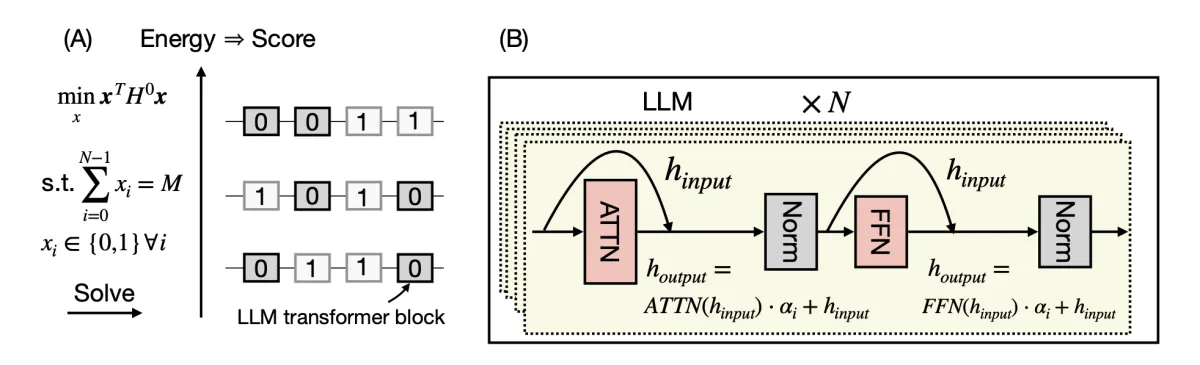 BlogsPruning LLMs Like a Physicist: Block Removal as an Ising Optimization Problemhuggingface.co
 BlogsJun Kim, oMLX creator and maintainer, joins Hugging Face to support the MLX communityhuggingface.co
 BlogsHow UK AISI and EvalEval Are Making Benchmark Results Reproduciblehuggingface.co
 BlogsHow to Use NVIDIA Warp and MjWarp to Accelerate Robotics Simulation and Learning Workflowshuggingface.co
Blogs10 best AI observability tools for monitoring and evaluating agents in 2026Mintlify
BlogsNew Spanish and Turkish Language Models and Updated General Models - Deepgram Blog ⚡️Deepgram
 BlogsLocal Kubernetes Development Using Minikube and Redis EnterpriseRedis
BlogsThe 8 Best HubSpot Alternatives in 2026Zapier
BlogsAI frameworks: Definition, types, and how to chooseZapier
BlogsHow We Eliminated Long-Lived CI Secrets Across 70+ ReposPulumi
BlogsDiscovered Stacks: One Place for All Your InfrastructurePulumi
BlogsPushing Pulumi ESC Secrets into External PlatformsPulumi
BlogsHow Hunch supercharged AI workflows with Modal SandboxesModal
BlogsAnthropic integration with Modal brings scalable compute to Claude ScienceModal
BlogsThe rise of slow personal assistantsCerebras
BlogsIntroducing DocChat: GPT-4 Level Conversational QA Trained In a Few Hours - CerebrasCerebras
BlogsSimulating Human Behavior with Cerebras - CerebrasCerebras
Blogs100x Defect Tolerance: How Cerebras Solved the Yield Problem - CerebrasCerebras
