
How to Avoid Cascading Failures in Distributed Systems
Cascading failures are failures that involve some kind of feedback mechanism. In distributed software systems they generally involve a feedback loop where some event causes either a reduction in capacity, an increase in latency, or a spike of errors.
 Natural Language Processing with Java - Second Edition: Book Review and InterviewInfoq
 Why the Dual Operating Model Impedes Enterprise AgilityInfoq
 How to Spark a Consumer-Grade UX RevolutionInfoq
 Stragglers, Not Failures: How Adaptive Hedged Requests Reduce p99 Latency by 74 PercentInfoq
Grab Redesigns Counter Service Storage for 50% Lower P99 LatencyInfoq
The Async Multiprocessing Has Sound Foundations in Linux, But Further Testing is NeededInfoq
 How a marketing agency increased client conversions 35% with Zapier CanvasZapier
 Cloud Systems: Deploying to Amazon ECSPulumi
 Managing dependencies - The Go Programming LanguageGo
 Unpacking sandbox startup latency: why started ≠ readyModal
 Scaling Organizations Should Consider Building a Website Backed by a CRM PlatformCss Tricks
 Cerebras Systems Announces Filing of Registration Statement for Proposed Initial Public OfferingCerebras
 KAUST and Cerebras Named Gordon Bell Award Finalist for Solving Multi-Dimensional SeismicCerebras
 Cerebras Raises $1 Billion Series H at $23 Billion ValuationCerebras
Cerebras Systems Enables GPU-Impossible™ Long Sequence Lengths Improving Accuracy in NaturalCerebras
 Cerebras Systems, Ranovus win $45 million US military deal to speed up chip connectionsCerebras
Cerebras Announces New Board Members and Chief Financial Officer - CerebrasCerebras
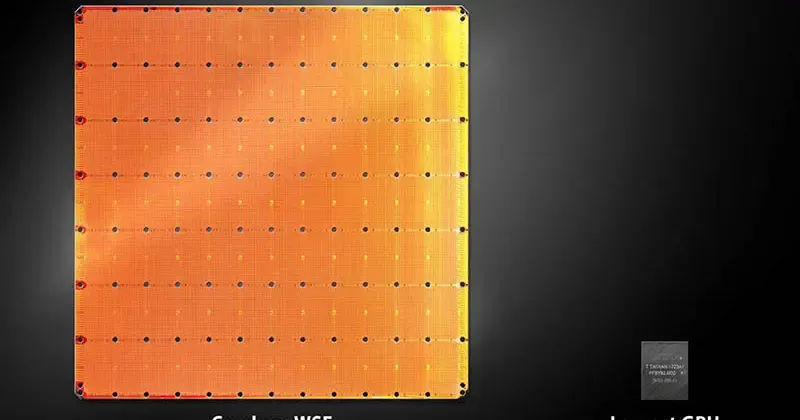 Cerebras Systems Unveils the Industry’s First Trillion Transistor Chip - CerebrasCerebras
 Cerebras Systems Raises $250M in Funding for Over $4B Valuation to Advance the Future of ArtificialCerebras
 Install the Collector on macOSOpentelemetry
