
The Schema Proliferation Problem in Kafka and Flink Pipelines: How to Solve It
Schema proliferation builds slowly and gets expensive fast. One schema per event type feels right until there are ten tables, union queries spanning all of them, and a single field rename touching every schema.
 Natural Language Processing with Java - Second Edition: Book Review and InterviewInfoq
 Why the Dual Operating Model Impedes Enterprise AgilityInfoq
 How to Spark a Consumer-Grade UX RevolutionInfoq
Grab Redesigns Counter Service Storage for 50% Lower P99 LatencyInfoq
The Async Multiprocessing Has Sound Foundations in Linux, But Further Testing is NeededInfoq
AI Agents with Cloud Credentials Are Outrunning Billing Guardrails Built for Human-Speed MistakesInfoq
 Oso Unbundles Security AuthorizationThenewstack
 Go Concurrency Patterns: Pipelines and cancellation - The Go Programming LanguageGo
 Anthropic integration with Modal brings scalable compute to Claude ScienceModal
 Some Things You Oughta Know When Working with Viewport UnitsCss Tricks
 MotherDuck Builder Office Hours - July 21Motherduck
 100x Defect Tolerance: How Cerebras Solved the Yield Problem - CerebrasCerebras
 GraphQL setup - MintlifyMintlify
 Troubleshooting .NET automatic instrumentation issuesOpentelemetry
 4 Ways to Get Your Code Back in Shape After Black FridayThenewstack
 What is OCSF and How Do You Implement It?Datadoghq
What is Root Cause Analysis?Datadoghq
 OpenAI Chat Completions Structured Outputs with AI GatewayVercel
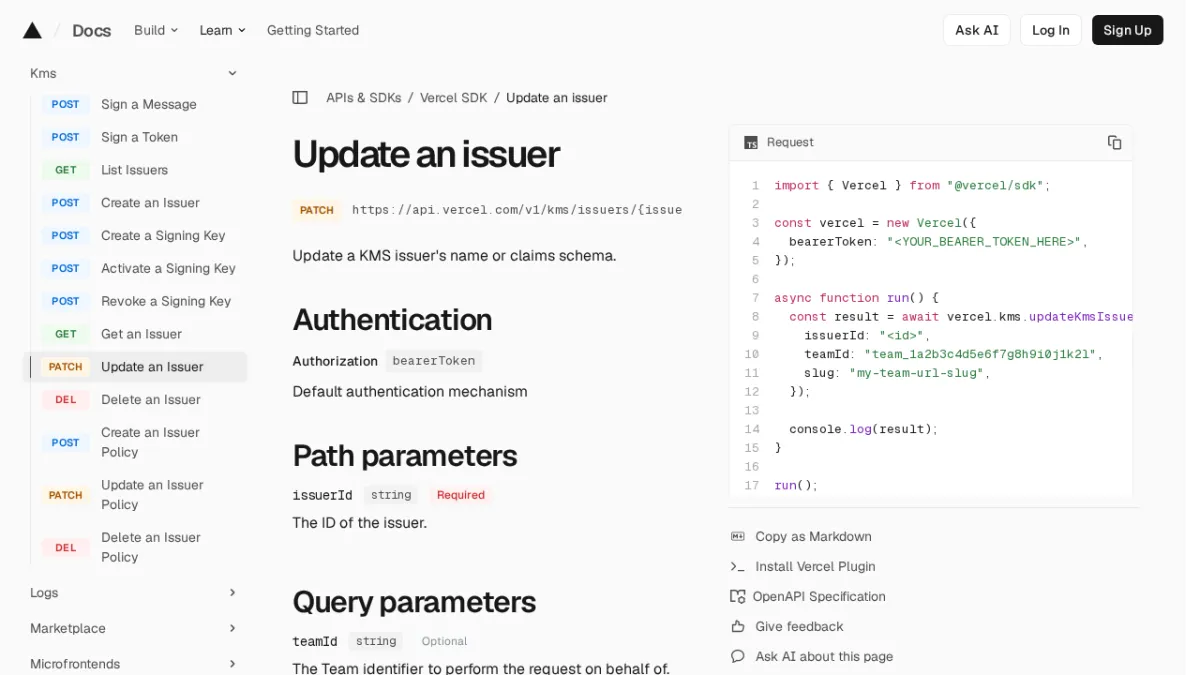 Update an issuer | Vercel SDKVercel
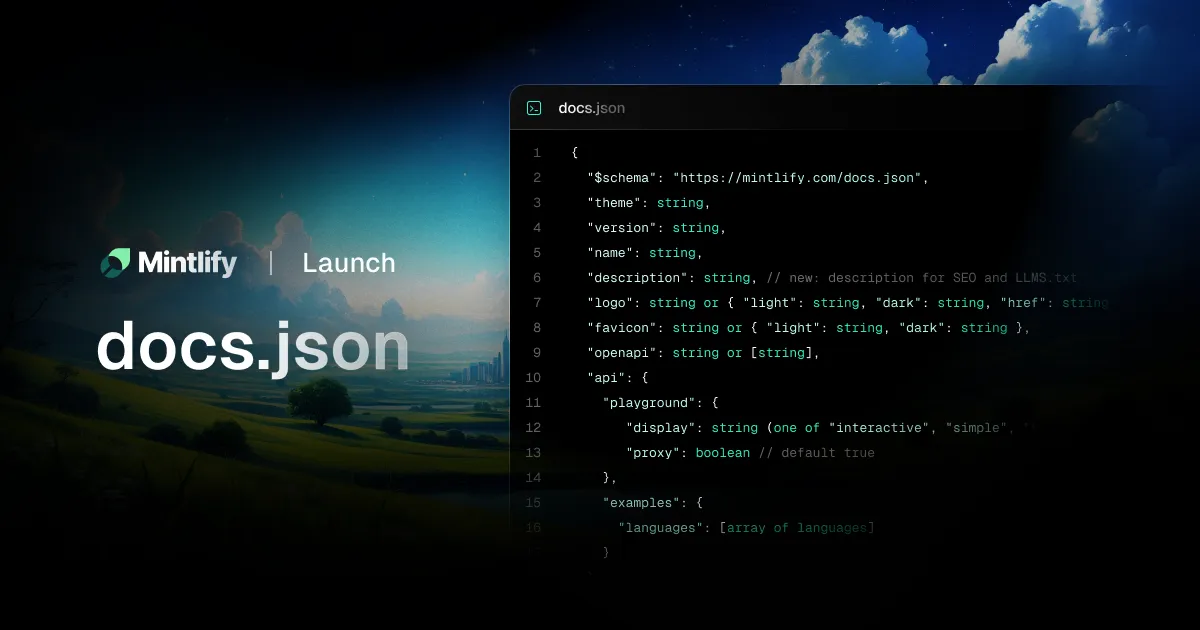 Refactoring mint.json into docs.jsonMintlify
