
Dollars per token considered harmful
Engineers of language model applications should think about requests, not tokens.
 Best practices for serverless inferenceModal
8 Top Open-Source OCR Models Compared: A Complete GuideModal
Google Cloud Run functions pricing: understanding costs and optimizationModal
Fine-tuning a FLUX.1-dev style LoRAModal
Azure Functions pricing: Consumption vs. Flex ConsumptionModal
Glossary: LLM fine-tuning hyperparametersModal
 Accelerating GPT-5.6 Sol UltrafastCerebras
 How ScanSource trains sales reps and saves 1000s of dollarsSynthesia
 Multi-token Residual PredictionModal
 Cerebras Is Coming to AWS Bedrock for Fast AI InferenceCerebras
 Gemma 4 on Cerebras—The Fastest Inference is Now MultimodalCerebras
 Introducing Usage Limits for Pulumi NeoPulumi
 How Greenly reduced time-to-deployment by 3x for internal and customer-facing appsRetool
 Scaling to 1 million concurrent sandboxes in secondsModal
 Token Authentication V2 Is Here - CDN Security UpgradedBunny
 Migrate to AI Gateway Using Your Coding AgentVercel
 How Bunny Optimizer GIF to WebP Conversion Saved One Company Thousands of Dollars Per MonthBunny
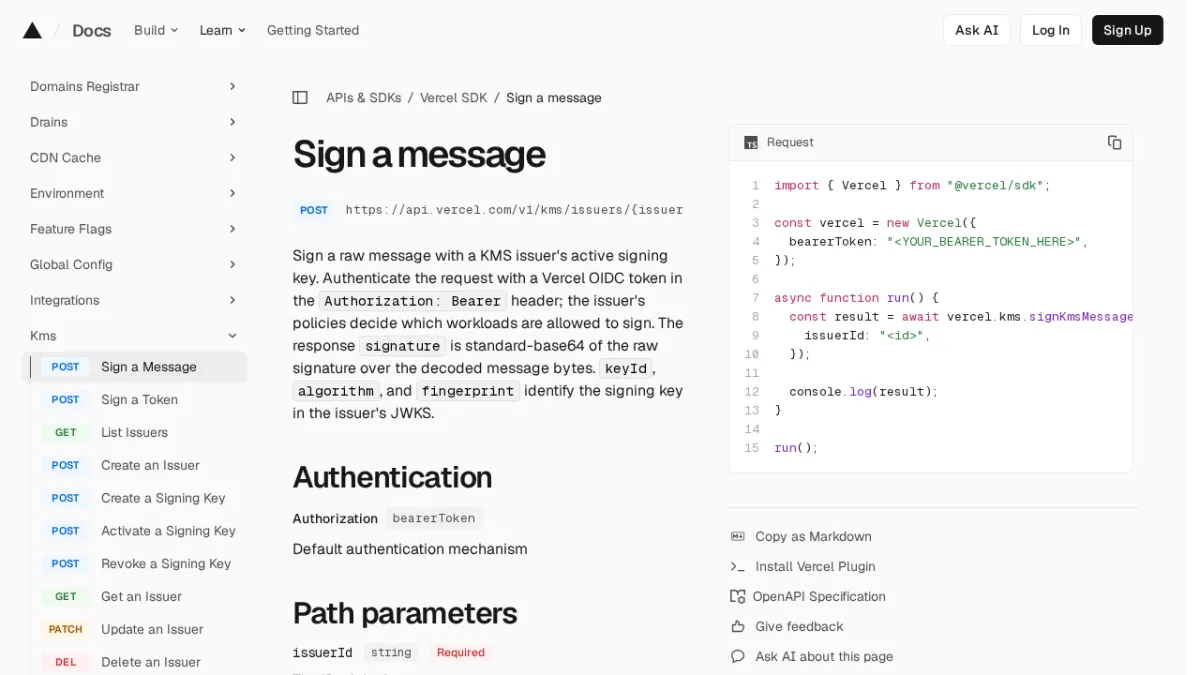 Sign a message | Vercel SDKVercel
 How Mach 1 uses Zapier MCP to run AI operations across 25 different companiesZapier
 CORS-safelisted response header - GlossaryDeveloper Mozilla
