
LoRA vs. QLoRA: Efficient fine-tuning techniques for LLMs
Learn the differences between LoRA and QLoRA, two different efficient fine-tuning techniques for large language models.
 How Ramp automated receipt processing with fine-tuned LLMsModal
Best practices for serverless inferenceModal
 Docker at Cloud Expo Asia: GenAI, Security, and New InnovationsDocker
 How AI Assistants Can Decode GitHub Repos for UI WritersDocker
 You can just ship agentsVercel
 Autogenerating API documentation from OpenAPIMintlify
 6 tips every developer should know when using Cursor and Windsurf AIMintlify
 Enhancing Pulumi Copilot: Introducing System Prompts for Your OrganizationPulumi
 Beating proprietary models with a quick fine-tuneModal
 Cerebras Systems and National Energy Technology Laboratory Set New Milestones for High-PerformanceCerebras
 How we fine-tuned Llama2-70B to pass the US Medical License Exam in a weekCerebras
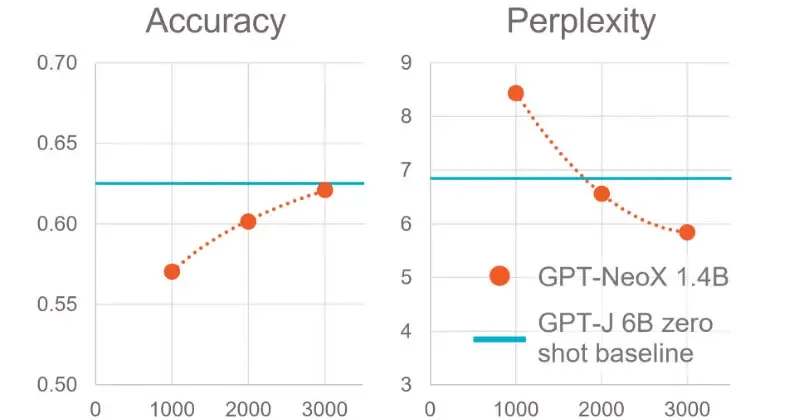 Fine-Tuning with Cerebras AI Model Studio Launchpad - CerebrasCerebras
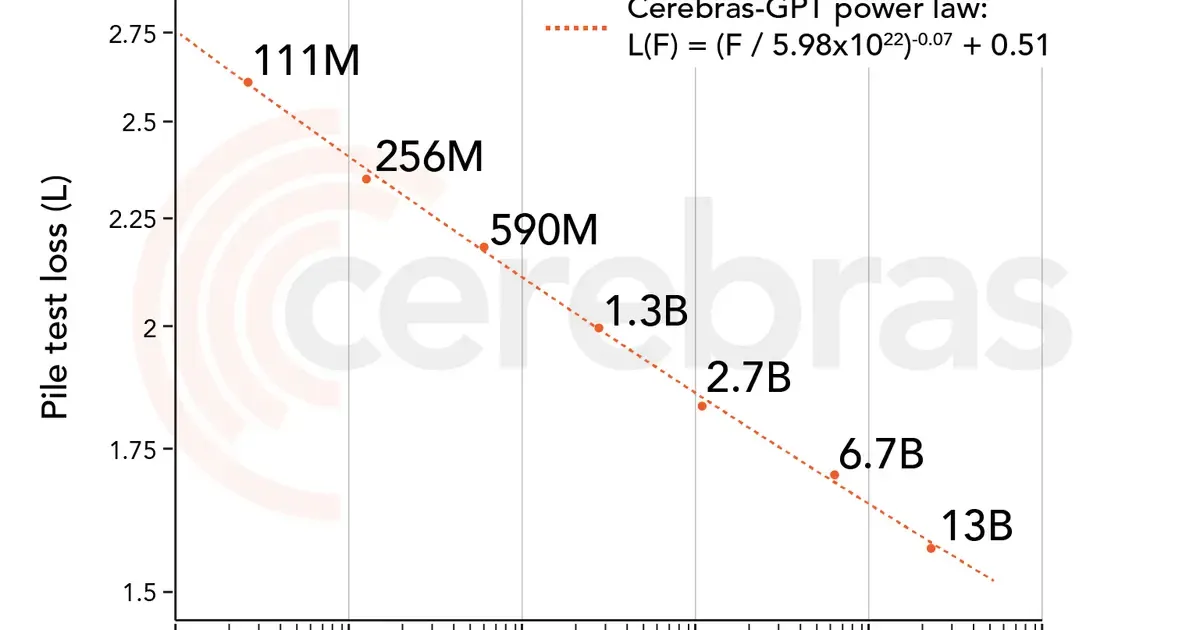 Cerebras-GPT: A Family of Open, Compute-efficient, Large Language Models - CerebrasCerebras
 AI Video Generators for BusinessHeygen
 How to structure documentation for both AI and human readersMintlify
 SuperGLUE: Understanding a Sticky Benchmark for LLMsDeepgram
