
Quail: Speeding up AI-SQL by jointly optimizing query planner and inference engine
I see it as a point on the LLM pareto optimal curve in a regime that had a large revealed latent demand (no thinking, single token, low latency acceptable intelligence) that was under-invested into because of a race to higher intelligence.
 Best practices for serverless inferenceModal
How much VRAM do I need for LLM inference?Modal
8 Top Open-Source OCR Models Compared: A Complete GuideModal
Google Cloud Run functions pricing: understanding costs and optimizationModal
Fine-tuning a FLUX.1-dev style LoRAModal
Azure Functions pricing: Consumption vs. Flex ConsumptionModal
 OData or GraphQL? The Best Tech for Developing an API Is Neither or Both!Thenewstack
 The App Engine SDK and workspaces (GOPATH) - The Go Programming LanguageGo
Go on App Engine: tools, tests, and concurrency - The Go Programming LanguageGo
 Analyze JSON Data Using SQL and DuckDBMotherduck
 Building a Remote MCP Server: OAuth, Tool Design & Lessons from 4,000+ AI Queries | MotherDuckMotherduck
 Summer Data Engineering RoadmapMotherduck
 It's Ducking Easy: From Zero to Insight with MotherDuck and dbtMotherduck
 SQL is Dead, Long Live SQL: Engineering a Reliable Analytics Agent from ScratchMotherduck
 The rise of slow personal assistantsCerebras
 Real-Time Computational Physics with Wafer-Scale Processing [updated]Cerebras
 Simulating Human Behavior with Cerebras - CerebrasCerebras
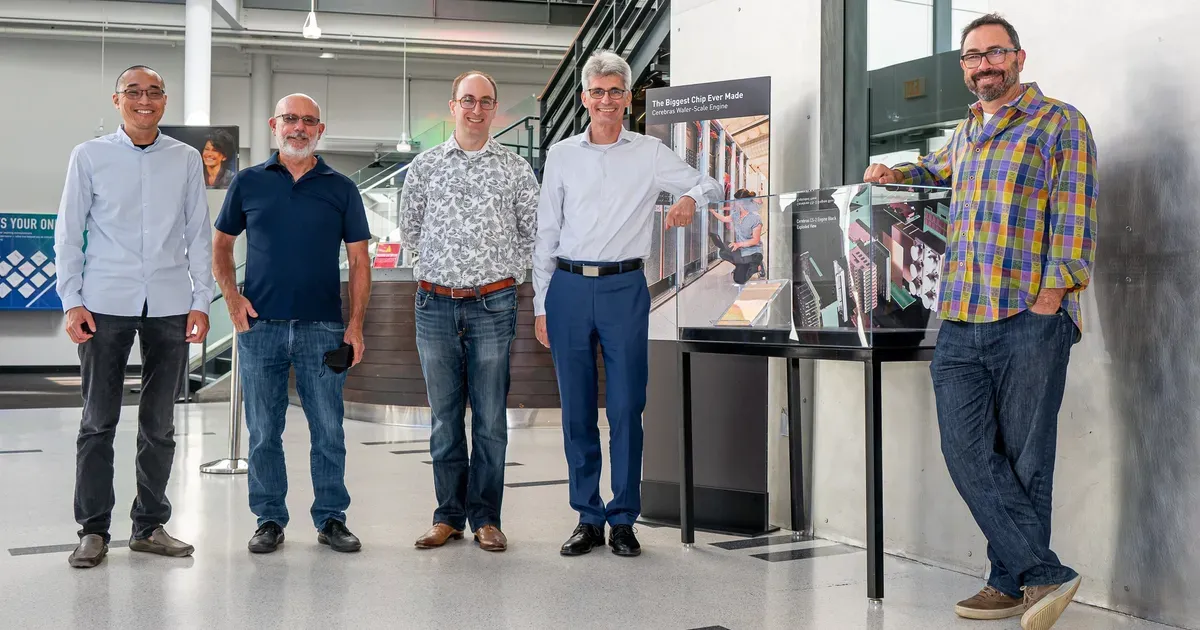 Cerebras Wafer-Scale Engine Inducted into the Computer History Museum - CerebrasCerebras
 100x Defect Tolerance: How Cerebras Solved the Yield Problem - CerebrasCerebras
 Cerebras Announces Six New AI Datacenters Across North America and Europe to Deliver Industry’sCerebras
