
What is LLM fine-tuning?
Fine-tuning helps us get more out of pretrained large language models (LLMs) by adjusting the model weights to better fit a specific task or domain.
 Glossary: LLM fine-tuning hyperparametersModal
How much VRAM do I need for LLM model fine-tuning?Modal
Fine-tuning a FLUX.1-dev style LoRAModal
Create a custom video generator by fine-tuning a Mochi LoRA on ModalModal
LoRA vs. QLoRA: Efficient fine-tuning techniques for LLMsModal
Llama3-405B: How to run an extra large open source LLM on ModalModal
 How Ramp automated receipt processing with fine-tuned LLMsModal
 Product updates: Running batch jobs with 1M inputs, ephemeral apps, and a new TensorRT-LLM exampleModal
 Beating proprietary models with a quick fine-tuneModal
 How we fine-tuned Llama2-70B to pass the US Medical License Exam in a weekCerebras
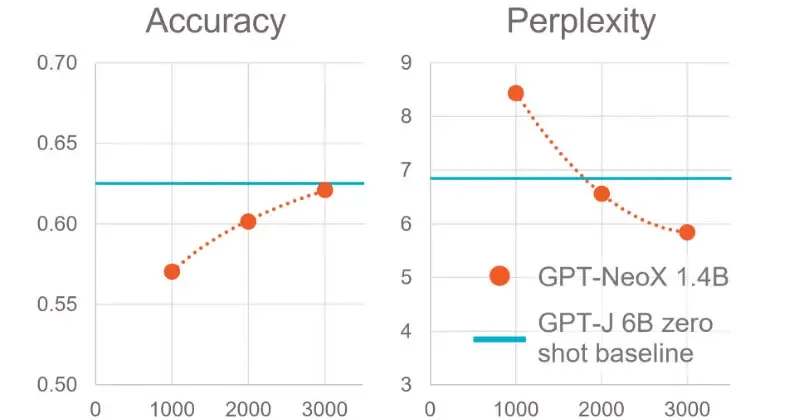 Fine-Tuning with Cerebras AI Model Studio Launchpad - CerebrasCerebras
 LLM-driven data pipelines with prompt() in MotherDuck and dbtMotherduck
 Extending LLM context with 99% less training tokens - CerebrasCerebras
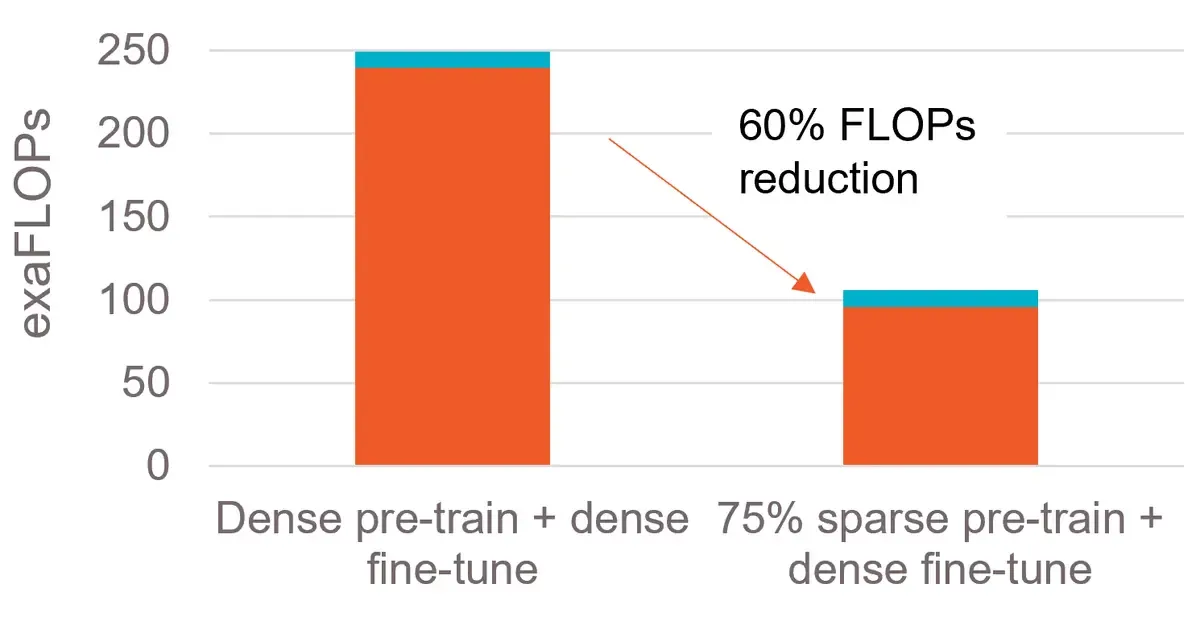 Accelerating Large GPT Training with Sparse Pre-Training and Dense Fine-Tuning [Updated] - CerebrasCerebras
 Cerebras and Qualcomm Unleash ~10X Inference Performance Boost with Hardware-Aware LLM TrainingCerebras
 Markdown export - MintlifyMintlify
 How an AI Agent Automates QA for the Cerebras Cloud ConsoleCerebras
 Introducing Kthena: LLM inference for the cloud native eraCncf
 LLM Gateway | AssemblyAIAssemblyai
 Stop Tuning Prompts. Build a Harness.Pulumi
