
We’re releasing an analysis showing that since 2012, the amount of compute used in the largest AI training runs has been increasing exponentially with a 3.4-month doubling time (by comparison, Moore’s Law had a 2-year doubling period)[^footnote-correction]. Since 2012, this metric has grown by more than 300,000x (a 2-year doubling period would yield only a 7x increase).
Recommended
Credit Saison achieves 954% ROI in a ChatGPT Enterprise pilotOpenai Making it easier for websites to express AI training preferencesOpenai Community safety report and new protections for teensOpenai Operation "Doppelganger": Russian influence activity targeting UkraineOpenai Everyday work with ChatGPT WorkOpenai Romance scams: AI-enabled romance scam workflowsOpenai Anthropic integration with Modal brings scalable compute to Claude ScienceModal
 Cerebras Systems Enables GPU-Impossible™ Long Sequence Lengths Improving Accuracy in NaturalCerebras
 Cerebras Systems Unveils the Industry’s First Trillion Transistor Chip - CerebrasCerebras
 You can just ship agentsVercel
 Modal Clusters are generally availableModal
 Cerebras Systems and National Energy Technology Laboratory Set New Milestones for High-PerformanceCerebras
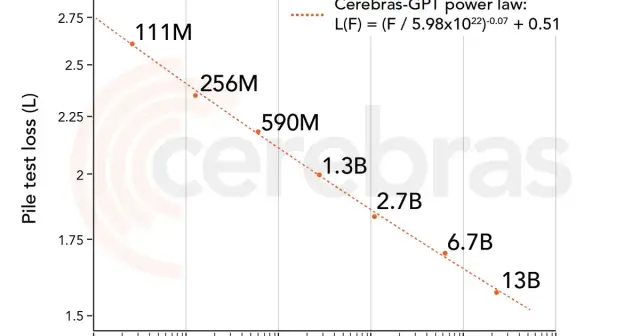 Cerebras-GPT: A Family of Open, Compute-efficient, Large Language Models - CerebrasCerebras
 How we used evals and inference-time compute scaling to generate beautiful QR codes that actuallyModal
 The Dive Gallery Is Live: Share Your Interactive Data Apps With the WorldMotherduck
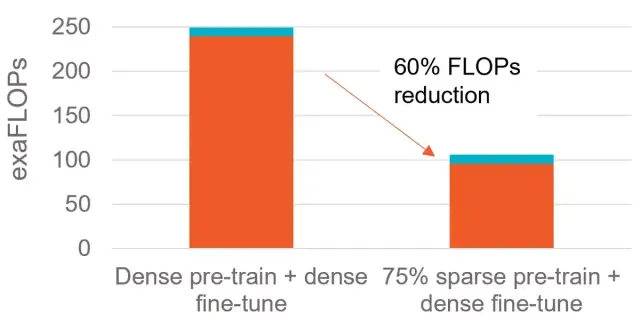 Accelerating Large GPT Training with Sparse Pre-Training and Dense Fine-Tuning [Updated] - CerebrasCerebras
 The Economics of AI ReasoningCerebras
 Green AI Cloud and Cerebras Systems Bring Industry-Leading AI Performance and Sustainability toCerebras
 Cerebras Systems and G42 to Partner to Bring High-Performance AI Compute to the Middle EastCerebras
 National Energy Technology Laboratory and Pittsburgh Supercomputing Center Pioneer First EverCerebras
