
We’re releasing highly-optimized GPU kernels for an underexplored class of neural network architectures: networks with block-sparse weights. Depending on the chosen sparsity, these kernels can run orders of magnitude faster than cuBLAS or cuSPARSE. We’ve used them to attain state-of-the-art results in text sentiment analysis and generative modeling of text and images.
Recommended
Credit Saison achieves 954% ROI in a ChatGPT Enterprise pilotOpenai Making it easier for websites to express AI training preferencesOpenai Community safety report and new protections for teensOpenai Operation "Doppelganger": Russian influence activity targeting UkraineOpenai Everyday work with ChatGPT WorkOpenai Romance scams: AI-enabled romance scam workflowsOpenai What is a CUDA Thread Block?Modal
What is a Load/Store Unit?Modal
 Cerebras Systems Enables GPU-Impossible™ Long Sequence Lengths Improving Accuracy in NaturalCerebras
What is a Tensor Core?Modal
 GPU Memory Snapshots: Supercharging sub-second startupModal
 Run GPU jobs from Airflow with ModalModal
 Two-Value Display Syntax (and Sometimes Three)Css Tricks
 Sparsity Made EasyCerebras
 Inside Modal Notebooks: How we built a cloud GPU notebook that boots in secondsModal
 Context is Everything: Why Maximum Sequence Length Matters - CerebrasCerebras
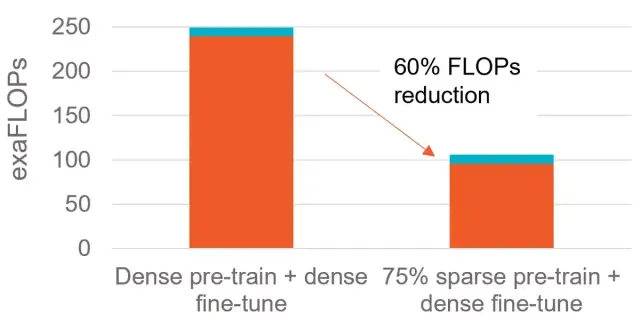 Accelerating Large GPT Training with Sparse Pre-Training and Dense Fine-Tuning [Updated] - CerebrasCerebras
 NVIDIA, RTXs, H100, and more: The Evolution of GPUDeepgram
 How to Run AI Agents on Kubernetes with PulumiPulumi
 Gafgyt Malware Variant Exploits GPU Power and Cloud Native EnvironmentsAquasec
