
We find that, just as a large transformer model trained on language can generate coherent text, the same exact model trained on pixel sequences can generate coherent image completions and samples. By establishing a correlation between sample quality and image classification accuracy, we show that our best generative model also contains features competitive with top convolutional nets in the unsupervised setting.
Recommended
Introducing new capabilities to GPT-RosalindOpenai The builder’s guide to GPT‑5.6Openai GPT-4V(ision) system cardOpenai GPT-6.1 Sol helps CodeRabbit strengthen security across complex codebasesOpenai Operation "Doppelganger": Russian influence activity targeting UkraineOpenai Everyday work with ChatGPT WorkOpenai How Hunch supercharged AI workflows with Modal SandboxesModal
 Introducing DocChat: GPT-4 Level Conversational QA Trained In a Few Hours - CerebrasCerebras
 Accelerating GPT-5.6 Sol UltrafastCerebras
 How to Use AI Image to Video Generator for Free to Create Dynamic VideosHeygen
 How we fine-tuned Llama2-70B to pass the US Medical License Exam in a weekCerebras
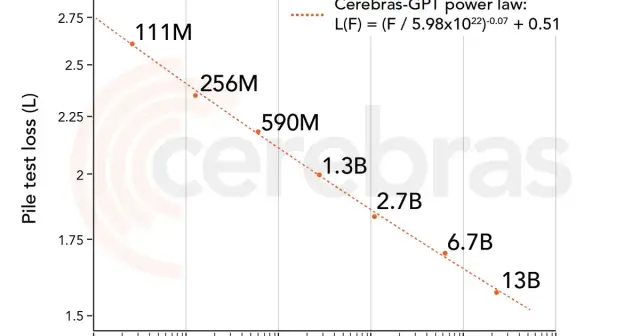 Cerebras-GPT: A Family of Open, Compute-efficient, Large Language Models - CerebrasCerebras
 Docker Scout health scores: Security grading for container images in your Docker Hub registryDocker
 What are AVIF images and what do we use it for?Bunny
What is a HEIF image extension and what is it used for?Bunny
 Install the Collector with DockerOpentelemetry
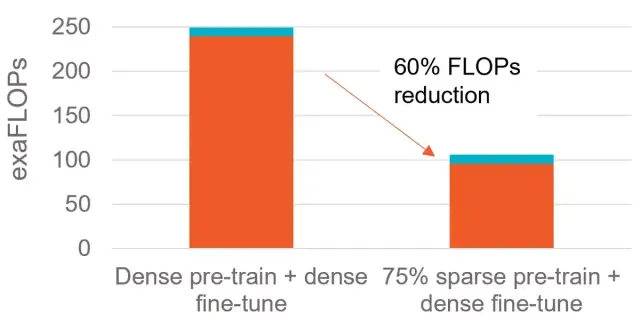 Accelerating Large GPT Training with Sparse Pre-Training and Dense Fine-Tuning [Updated] - CerebrasCerebras
 Questions to Ask Your Hardened Image ProviderDocker
 Let's talk AVIF - and why we're not adding support just yetBunny
 MIME type - GlossaryDeveloper Mozilla
