
Terminal X’s Eval Agent grades outputs against a 54-criterion rubric, catching 25% more deviances from a fund’s mandate with GPT-6.1 Sol.
Recommended
Introducing new capabilities to GPT-RosalindOpenai The builder’s guide to GPT‑5.6Openai GPT-4V(ision) system cardOpenai GPT-6.1 Sol helps CodeRabbit strengthen security across complex codebasesOpenai Credit Saison achieves 954% ROI in a ChatGPT Enterprise pilotOpenai Making it easier for websites to express AI training preferencesOpenai Introducing DocChat: GPT-4 Level Conversational QA Trained In a Few Hours - CerebrasCerebras
 Accelerating GPT-5.6 Sol UltrafastCerebras
 How Sky Italia Digitizes Learning Paths to Accelerate New Product Launches by 4xSynthesia
 How we fine-tuned Llama2-70B to pass the US Medical License Exam in a weekCerebras
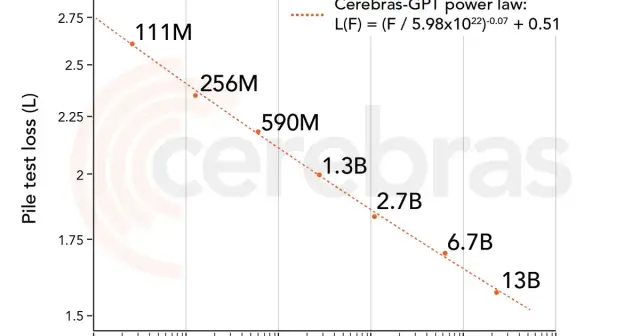 Cerebras-GPT: A Family of Open, Compute-efficient, Large Language Models - CerebrasCerebras
 vercel projectVercel
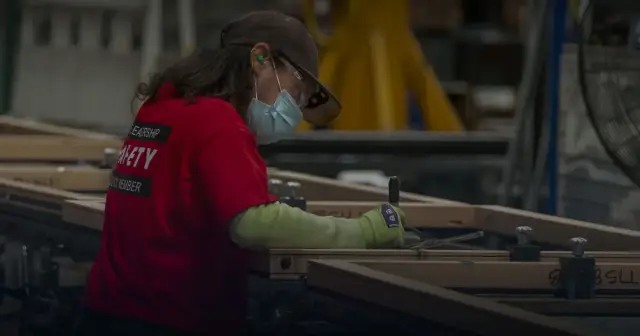 How JELD-WEN increased training output and learning engagement 8x with AI videoSynthesia
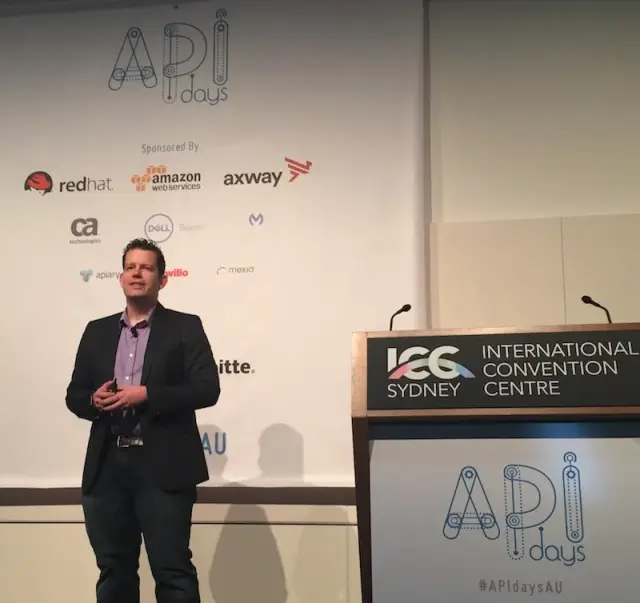 The Five Principles of Software EthicsThenewstack
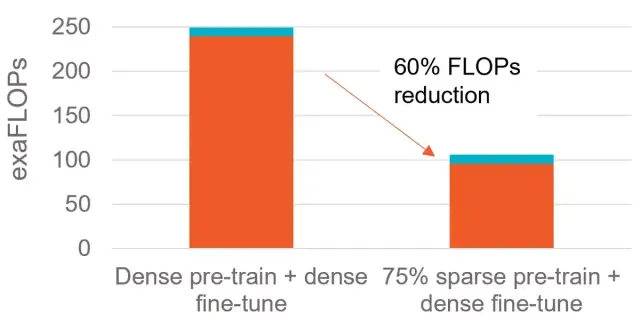 Accelerating Large GPT Training with Sparse Pre-Training and Dense Fine-Tuning [Updated] - CerebrasCerebras
 How Zoom accelerated training video production by 90%Synthesia
 How SimCorp enhanced its explainer videosSynthesia
 Cerebras Systems and Cirrascale Cloud Services® Introduce Cerebras AI Model Studio to TrainCerebras
 Which is faster: Gemini 3.5 Flash or Kimi K2.6 on CerebrasCerebras
 Building AI-powered Article Embeddings with Chroma and GPT-4Vercel
