
Jet-setting with Llama 2 + Grammars
How to use Llama 2 models with grammars for information extraction tasks.
 Some Things You Oughta Know When Working with Viewport UnitsCss Tricks
 Improving Pulumi’s Docker ImagesPulumi
 Setting up and using gccgo - The Go Programming LanguageGo
 Vary This, Vary That - Introducing New Custom Query Parameter Vary Cache SettingsBunny
 Default Behavior of “Git Push” without a Branch SpecifiedBetterstack
 Setting up and Customizing the Ant Design System in a Nuxt AppCss Tricks
 Istio Certified Associate (ICA)Cncf
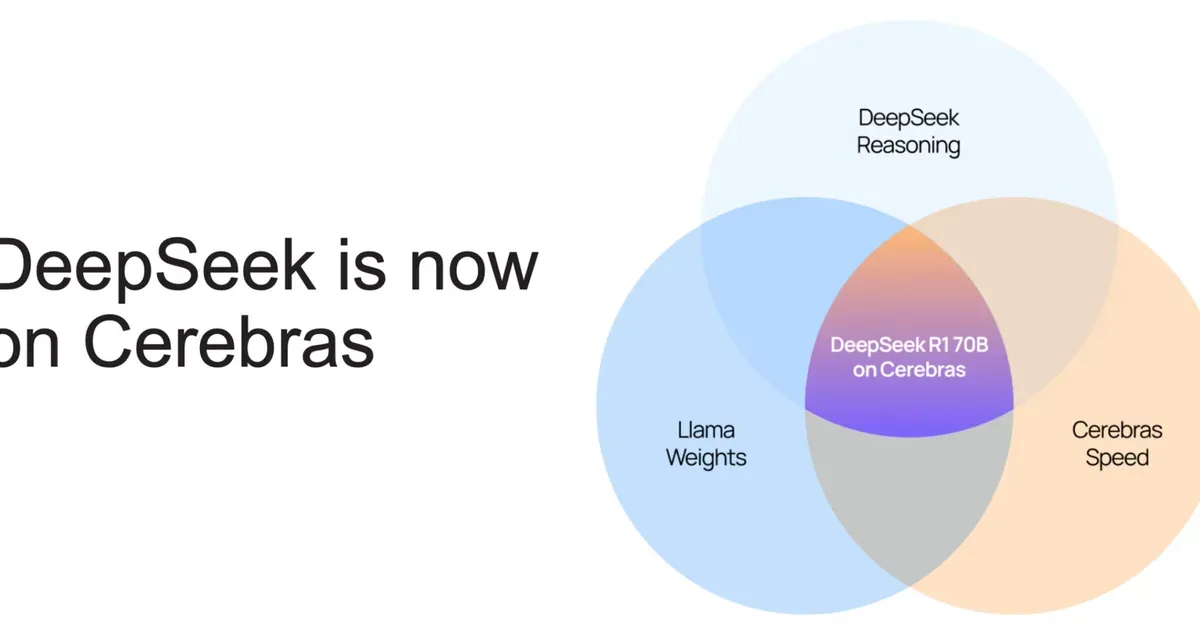 Cerebras Launches World Fastest DeepSeek R1 Llama-70B Inference - CerebrasCerebras
 Meta unleashes Llama API running 18x faster than OpenAI: Cerebras partnership delivers 2,600 tokensCerebras
 Meta Collaborates with Cerebras to Drive Fast Inference for Developers in New Llama APICerebras
 Org-only Template Gallery and Setting Default Repositories: Streamline Your DevelopmentPulumi
 Cerebras Powers Perplexity Sonar with Industry’s Fastest AI Inference - CerebrasCerebras
 Setting Up WebhooksVercel
 Agent Context Carryover: more accurate voice agent transcription on LiveKitAssemblyai
