
Torch compile caching for inference speed
Torch compile caching for inference speed We now cache torch.compile artifacts to reduce boot times for models that use Py Torch.
 Data Ingestion: 6 Ways to Speed Up Your ApplicationRedis
 DevSecOps: Why Security Shouldn’t be Sacrificed for SpeedThenewstack
 Cerebras Breaks Exascale Record for Molecular Dynamics Simulations - CerebrasCerebras
 The rise of slow personal assistantsCerebras
 Simulating Human Behavior with Cerebras - CerebrasCerebras
 100x Defect Tolerance: How Cerebras Solved the Yield Problem - CerebrasCerebras
 Cerebras Announces Six New AI Datacenters Across North America and Europe to Deliver Industry’sCerebras
 AMD and Cerebras Announce Disaggregated AI InferenceCerebras
 Cerebras Systems, Ranovus win $45 million US military deal to speed up chip connectionsCerebras
 Cerebras Systems Raises $250M in Funding for Over $4B Valuation to Advance the Future of ArtificialCerebras
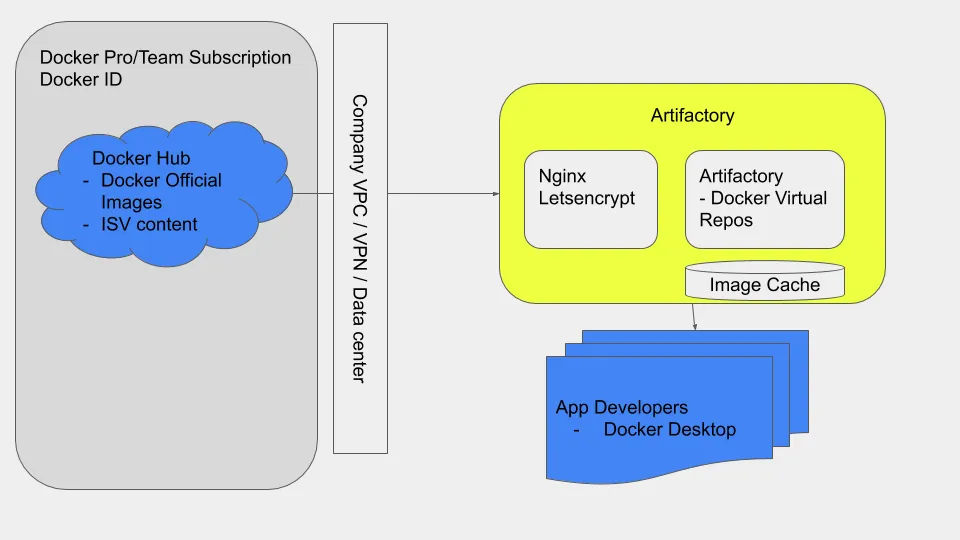 New Docker and JFrog Partnership Designed to Improve the Speed and Quality of App DevelopmentDocker
 Best AI Video Generator for TikTok in 2026 (Tried & Tested)Heygen
 Creating an AI Summary App with Next.js | Vercel AcademyVercel
 TroubleshootingOpentelemetry
