
Practical XPath for Web Scraping
XPath is a technology that uses path expressions to select nodes or node-sets in an XML document (or in our case an HTML document).
 Web Scraping with node-fetchScrapingBee
 Web Scraping with Scala - Easily Scrape and Parse HTMLScrapingBee
 Playwright for Python Web Scraping Tutorial with ExamplesScrapingBee
 Playwright web scraping: How to make your scripts fasterScrapingBee
 7 Best C# Web Scraping Libraries in 2026 (Compared & Ranked)ScrapingBee
 Web Scraping in C++ with libxml2 and libcurlScrapingBee
 Cloud Security Trends & Challenges: Complete GuideCybersecurity Exchange
 Security Implementation for Responsible AI: A Practical FrameworkCybersecurity Exchange
 5 ways to automate Browse AIZapier
 Grafana Is Not Worried About AWS CommercializationThenewstack
 Real Go Projects: SmartTwitter and web.go - The Go Programming LanguageGo
 The failed promise of Web ComponentsCss Tricks
 Practical Uses for AI in Your Data WorkflowsMotherduck
 PostgreSQL and Ducks: The Perfect Analytical PairingMotherduck
 Using Web AnalyticsVercel
 Configuration and settingsOpentelemetry
 Google Workspace automationZapier
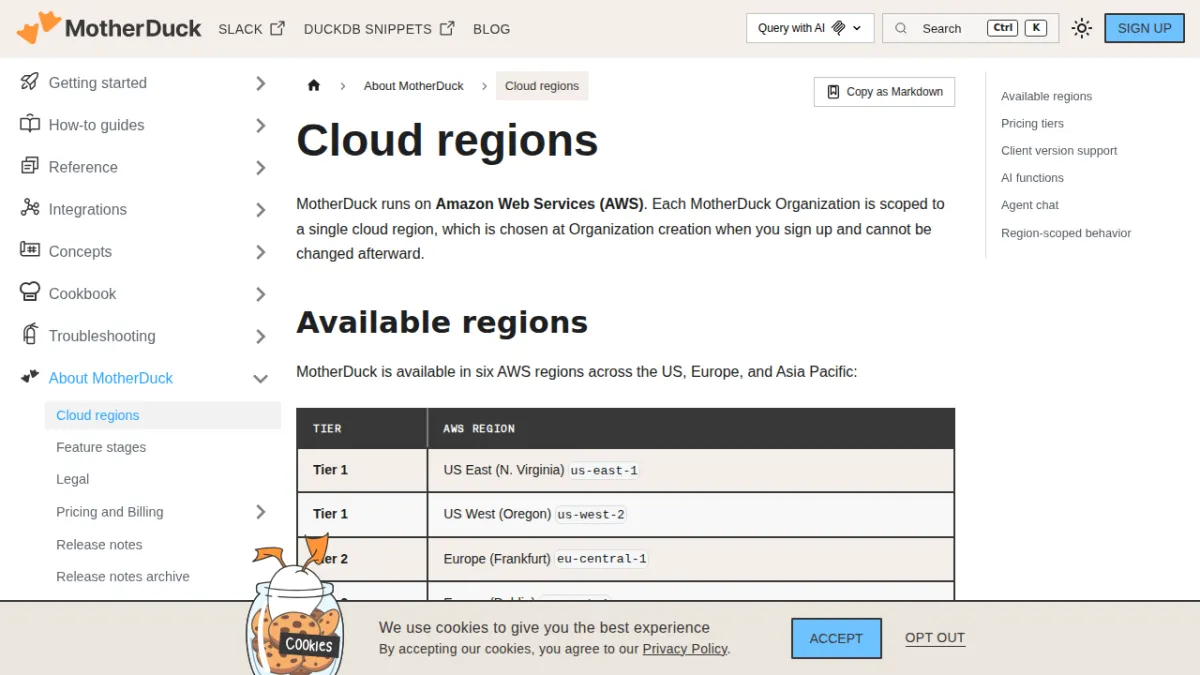 Cloud regionsMotherduck
 Microsoft Internet Explorer - GlossaryDeveloper Mozilla
 Web standards - GlossaryDeveloper Mozilla
