
Puppeteer Web Scraping Tutorial in Nodejs
This tutorial explores how to scrape Reddit using a headless Chrome instance in Node.js with the Puppeteer library.
 Playwright for Python Web Scraping Tutorial with ExamplesScrapingBee
 Web Scraping with node-fetchScrapingBee
 Web Scraping with Scala - Easily Scrape and Parse HTMLScrapingBee
 Playwright web scraping: How to make your scripts fasterScrapingBee
 7 Best C# Web Scraping Libraries in 2026 (Compared & Ranked)ScrapingBee
 Web Scraping in C++ with libxml2 and libcurlScrapingBee
 5 ways to automate Browse AIZapier
 Grafana Is Not Worried About AWS CommercializationThenewstack
 Real Go Projects: SmartTwitter and web.go - The Go Programming LanguageGo
 The failed promise of Web ComponentsCss Tricks
 Using Web AnalyticsVercel
 How to Use Voice to Control Music with Python and Deepgram - Deepgram Blog ⚡️Deepgram
 Configuration and settingsOpentelemetry
 Google Workspace automationZapier
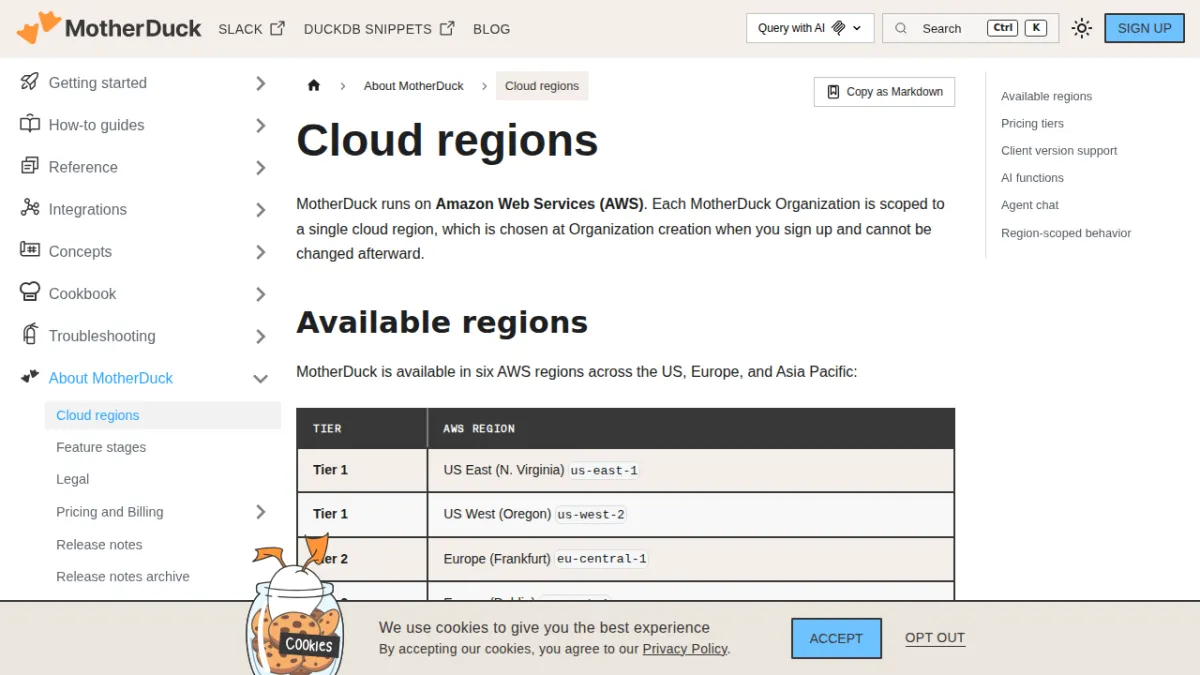 Cloud regionsMotherduck
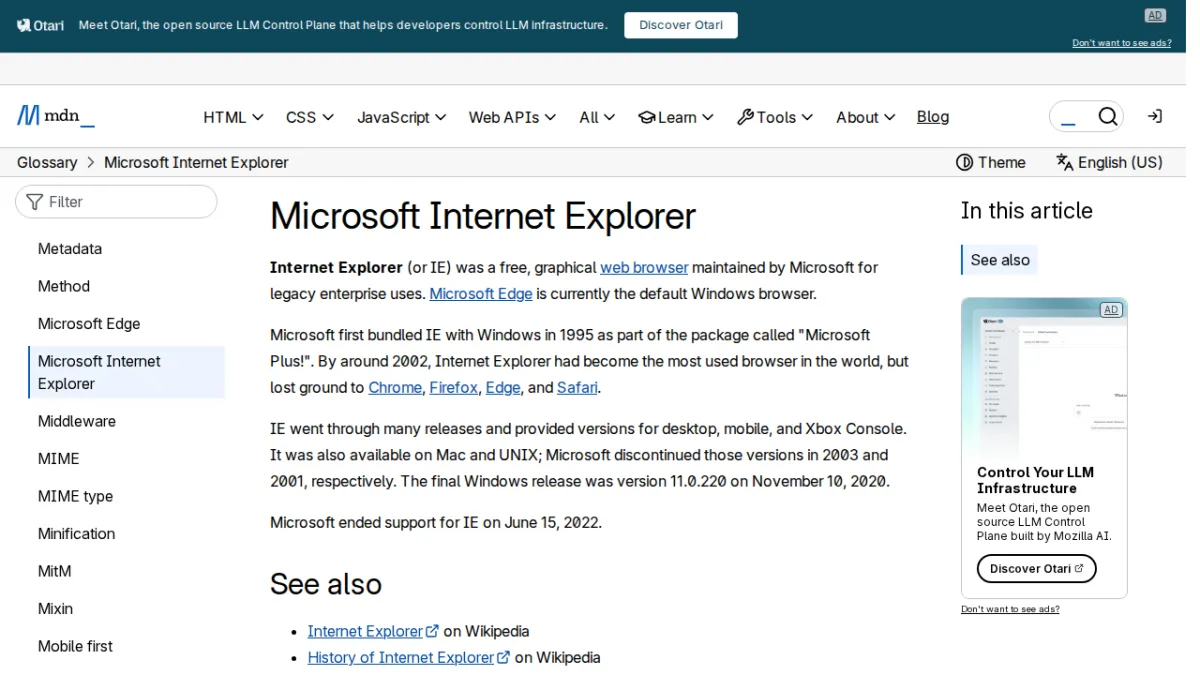 Microsoft Internet Explorer - GlossaryDeveloper Mozilla
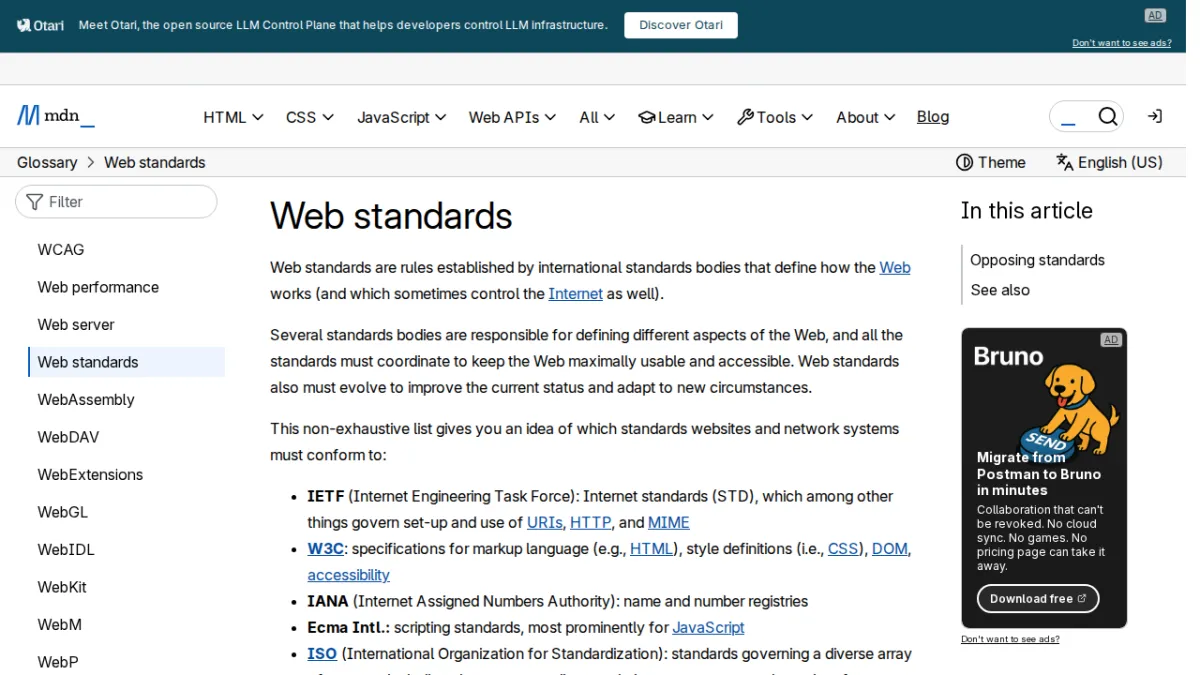 Web standards - GlossaryDeveloper Mozilla
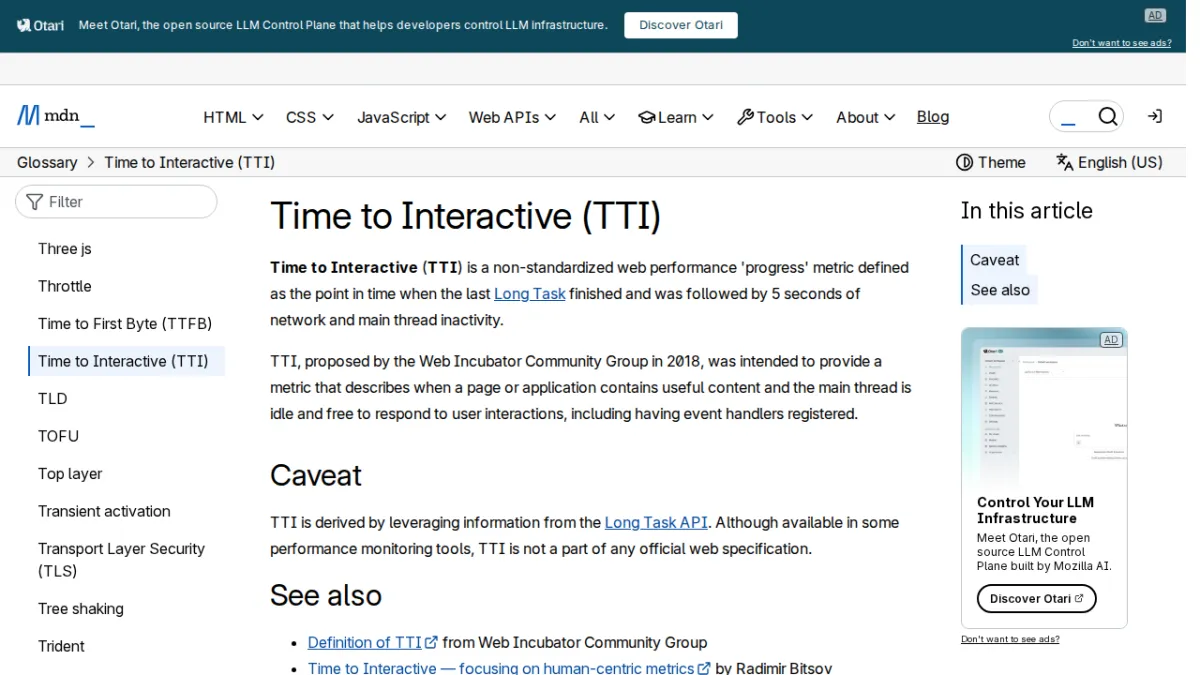 Time to Interactive (TTI) - GlossaryDeveloper Mozilla
 with JupyterLab as a Docker ExtensionDocker
 DockerCon Workshops: Getting Started with Docker, AI/ML, Secure DevelopmentDocker
