
Accelerate RL rollouts by up to 50% with distribution-aware speculative decoding
Distribution-aware speculative decoding (DAS) is a novel framework that significantly alleviates the rollout bottleneck in RL post-training — delivering up to 50% speedup without touching model outputs.
 Intel Unveils Next Generation Neuromorphic Computing ChipThenewstack
 Announcing the New Pulumi Partner ProgramPulumi
 From ASR to CSR: Why Conversation Changes EverythingDeepgram
 Using instrumentation librariesOpentelemetry
 How Sky Italia Digitizes Learning Paths to Accelerate New Product Launches by 4xSynthesia
 Speculation Is All You NeedModal
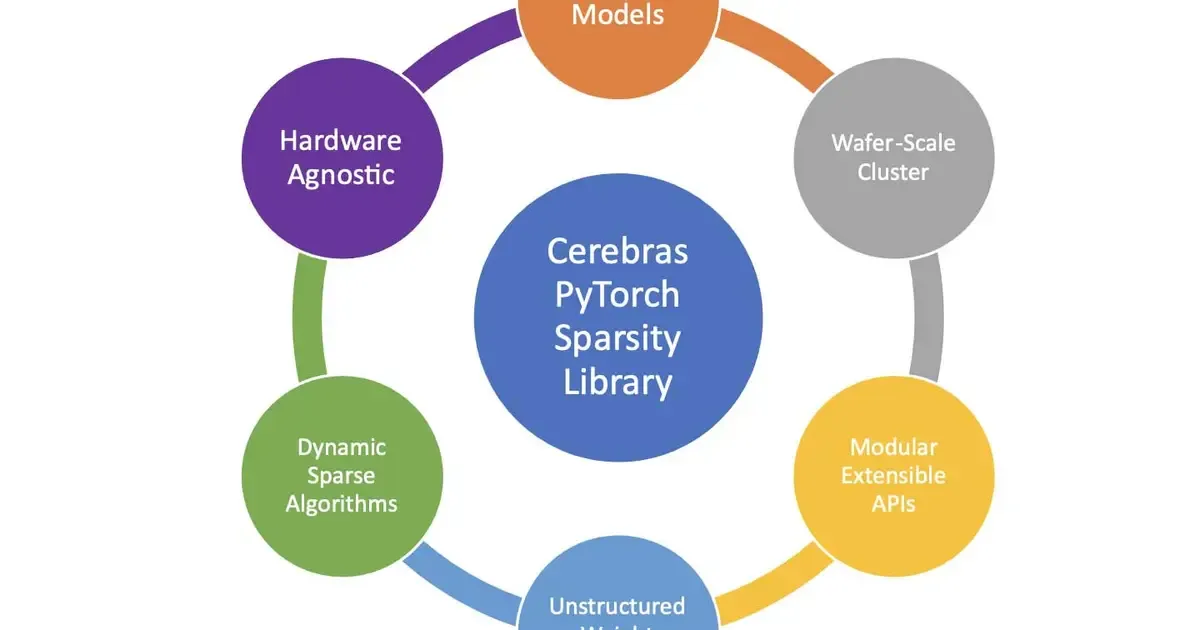 Sparsity Made EasyCerebras
 Mental Health Marketing: A Responsible 2026 GuideHeygen
 Partnering with Shutterstock to accelerate our AI research effortsSynthesia
 Biome Announces v2.0 Beta with Plugin System and Type Information SupportSocket
 Dense Memcached with Nonvolatile MemoryThenewstack
 Autoscaling Autoresearch: Give your agents elastic GPUs on ModalModal
 Cerebras Systems Launches “Cerebras for Nations” -- A Global Initiative to Accelerate and ScaleCerebras
 Cerebras and Qualcomm Unleash ~10X Inference Performance Boost with Hardware-Aware LLM TrainingCerebras
