
Boosting DeepSeek-R1’s Speed with Customized Speculative Decoding
TLDR: In this blog post, we show that using a custom speculator—trained on your own Deepseek-R1 inference traffic—can yield 1.23-1.45 x speedups during decoding (tokens/second), and ~25% reduction in overall cost (same throughput with fewer GPU-hours), relative to Together’s state-of-the-art base speculator.
 Data Ingestion: 6 Ways to Speed Up Your ApplicationRedis
 7 ways to use Zapier's Zendesk integrationZapier
 DevSecOps: Why Security Shouldn’t be Sacrificed for SpeedThenewstack
 Cerebras Breaks Exascale Record for Molecular Dynamics Simulations - CerebrasCerebras
 KAUST and Cerebras Named Gordon Bell Award Finalist for Solving Multi-Dimensional SeismicCerebras
 Cerebras Systems, Ranovus win $45 million US military deal to speed up chip connectionsCerebras
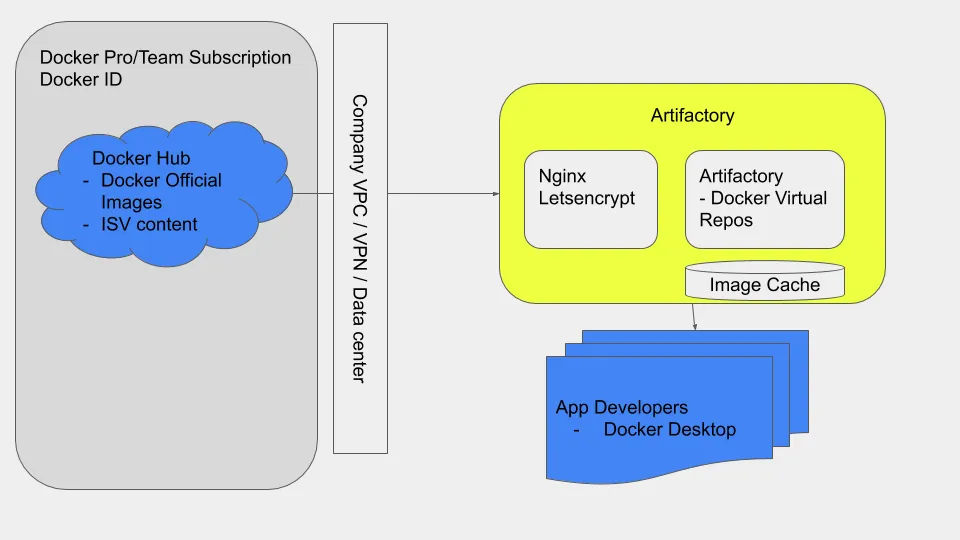 New Docker and JFrog Partnership Designed to Improve the Speed and Quality of App DevelopmentDocker
 Best AI Video Generator for TikTok in 2026 (Tried & Tested)Heygen
 How Contextual AI automated CI with Modal GPUsModal
 Speculation Is All You NeedModal
 Cerebras: January 2025 Happenings - CerebrasCerebras
 Cerebras Is Coming to AWS Bedrock for Fast AI InferenceCerebras
 Innovation at the edge: How Edge Storage makes content delivery really hopBunny
 vercel projectVercel
