
Foundational research powering efficient inference at scale
AI has spent years in the spotlight for training: the massive, GPU-intensive process of building models.
 How we grew Mintlify by doing things that don't scaleMintlify
 How to implement AI training for employeesZapier
 Pancakes Are Delicious and Data Centers Are for Free StuffThenewstack
 Transform and Future-Proof Your Architecture with MACHThenewstack
 Selecting the Right Database for Your MicroservicesThenewstack
 The rise of slow personal assistantsCerebras
 Real-Time Computational Physics with Wafer-Scale Processing [updated]Cerebras
 Simulating Human Behavior with Cerebras - CerebrasCerebras
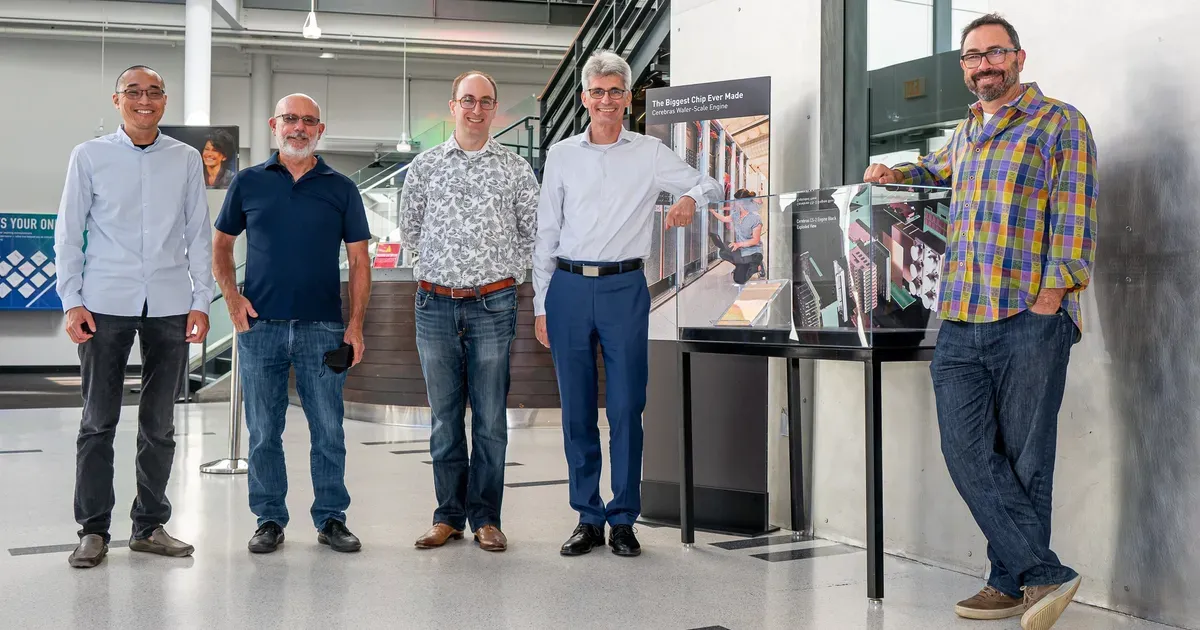 Cerebras Wafer-Scale Engine Inducted into the Computer History Museum - CerebrasCerebras
 100x Defect Tolerance: How Cerebras Solved the Yield Problem - CerebrasCerebras
 Cerebras Announces Six New AI Datacenters Across North America and Europe to Deliver Industry’sCerebras
 AMD and Cerebras Announce Disaggregated AI InferenceCerebras
 Cerebras Systems, Ranovus win $45 million US military deal to speed up chip connectionsCerebras
 Cerebras Systems Raises $250M in Funding for Over $4B Valuation to Advance the Future of ArtificialCerebras
