
Blogs
Llama-2-7B-32K-Instruct
We’re excited to release Llama-2-7 B-32 K-Instruct, a long-context instruction model fine-tuned using Together API!
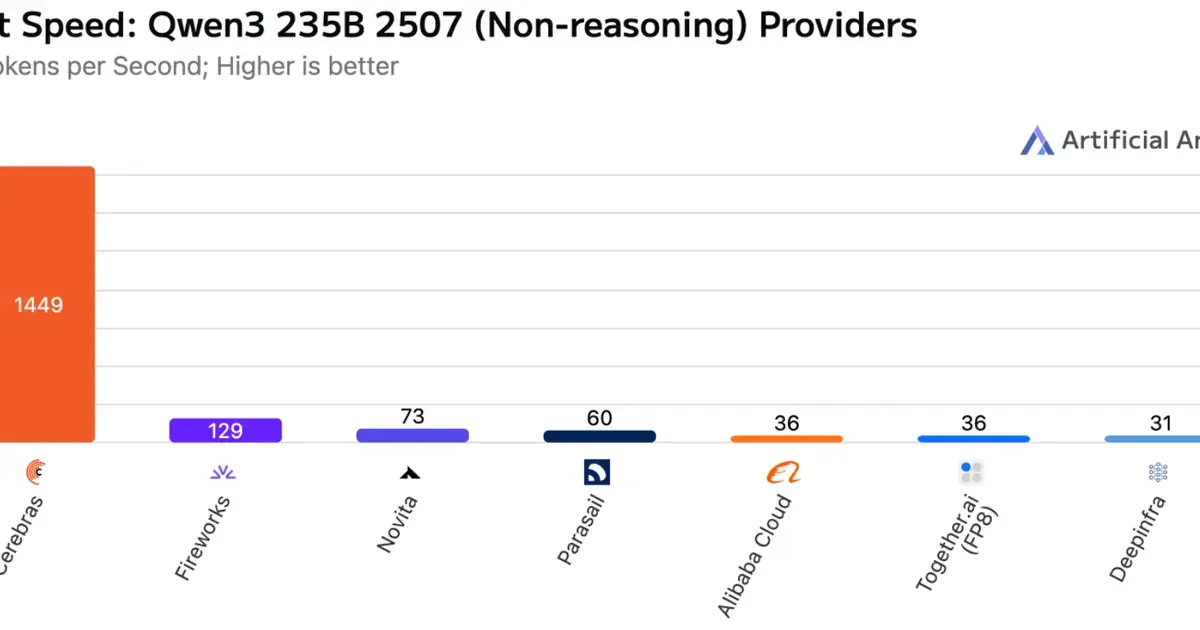 Qwen3 235B 2507 Instruct Now Available on CerebrasCerebras
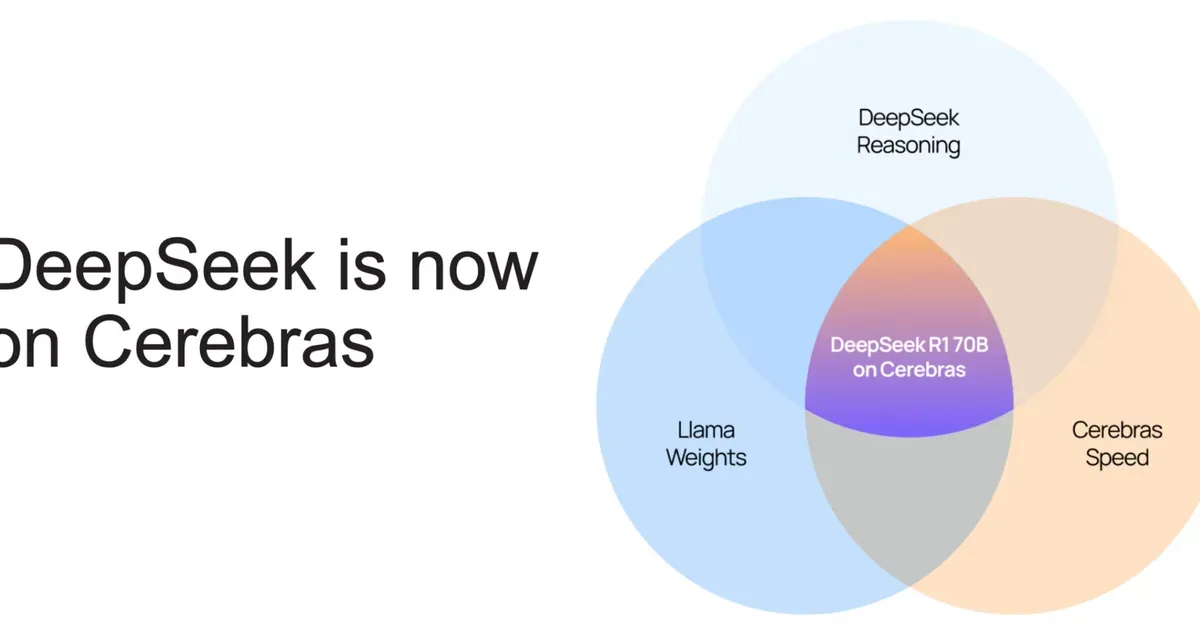 Cerebras Launches World Fastest DeepSeek R1 Llama-70B Inference - CerebrasCerebras
 Meta unleashes Llama API running 18x faster than OpenAI: Cerebras partnership delivers 2,600 tokensCerebras
 Meta Collaborates with Cerebras to Drive Fast Inference for Developers in New Llama APICerebras
 Cerebras Powers Perplexity Sonar with Industry’s Fastest AI Inference - CerebrasCerebras
 Llama 4 Maverick 17B Instruct API & PricingVercel
Simplifying Code Infilling with Code Llama and Fireworks.aiFireworks
Why do all LLMs need structured output modes?Fireworks
Building a RAG with Astro, FastAPI, SurrealDB and Llama 3.1Fireworks
Qwen3 Coder 480B is Live on CerebrasCerebras
Cerebras Triples its Industry-Leading Inference Performance, Setting New All Time Record - CerebrasCerebras
Optimizing Llama 4 Maverick on FireworksFireworks
 Resumable Llama.cpp Downloads + Model RunnerDocker
 Llama 4 Scout 17B 16E Instruct API & PricingVercel
