
Efficient Inference with SGLang: Text and Image Generation
Learn how LLM inference works under the hood and implement caching optimizations, including KV cache and RadixAttention, to make text and image generation faster and cheaper.
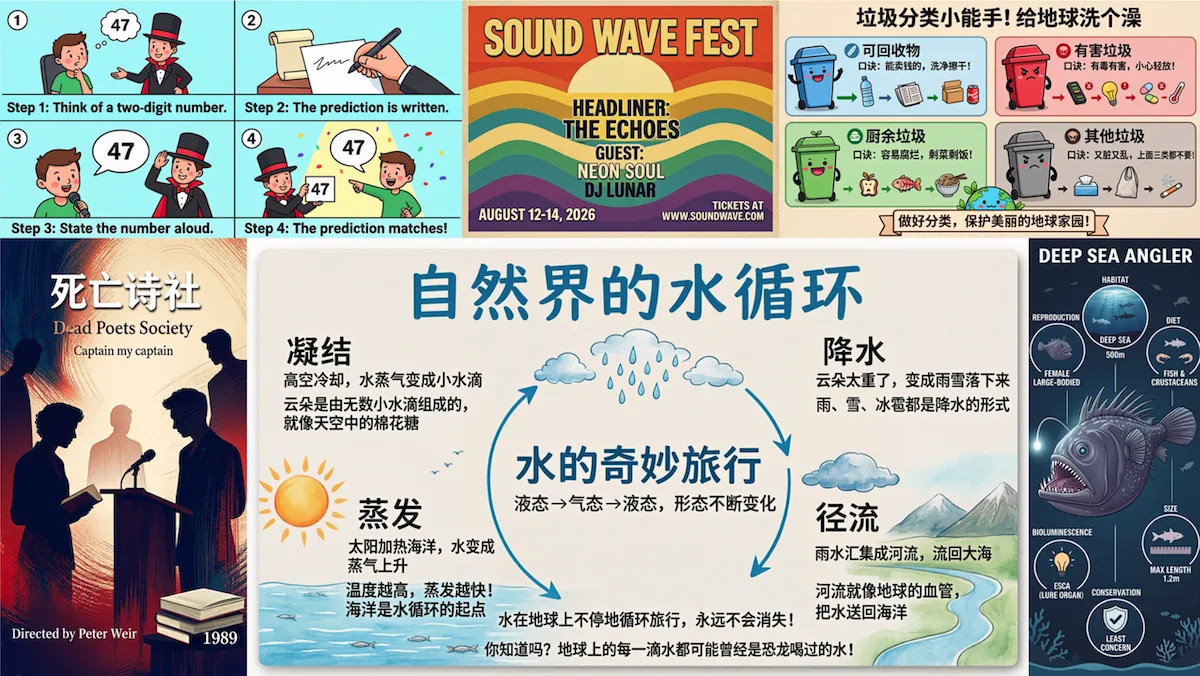 Zhipu’s GLM-Image Blends Transformer and Diffusion Architectures For Better Text in Imagesdeeplearning.ai
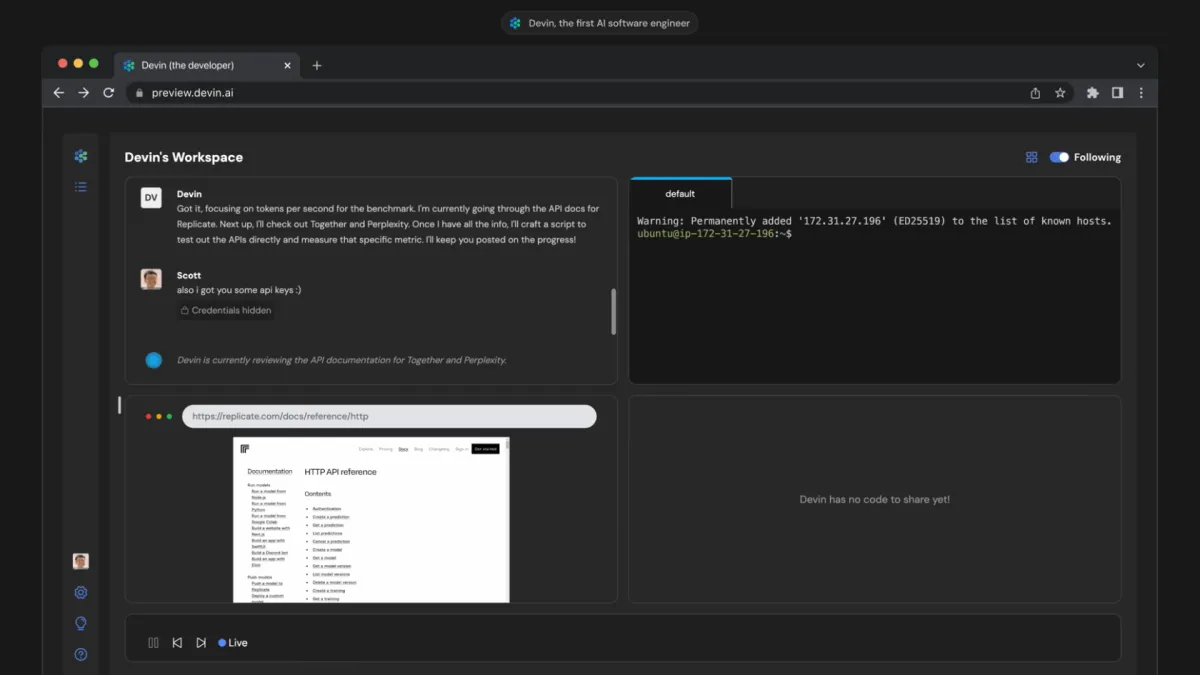 Next-Generation Coding Tools Empower Developers with Agent-Style Interactionsdeeplearning.ai
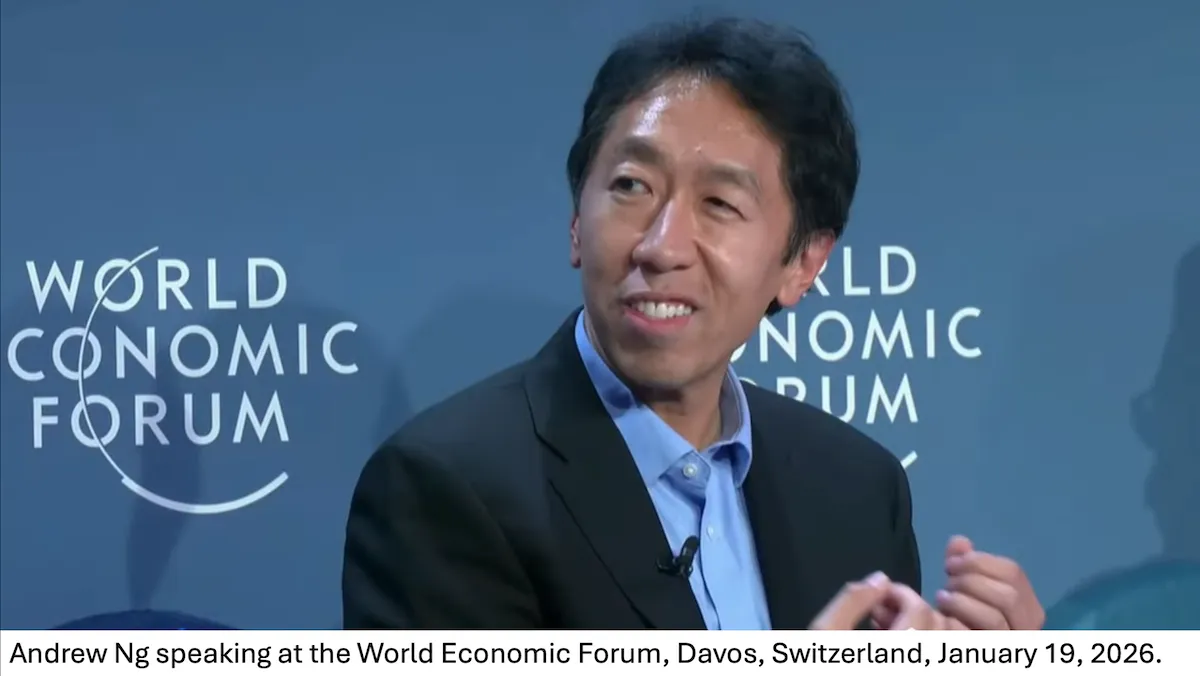 From AI Experiments to AI Productsdeeplearning.ai
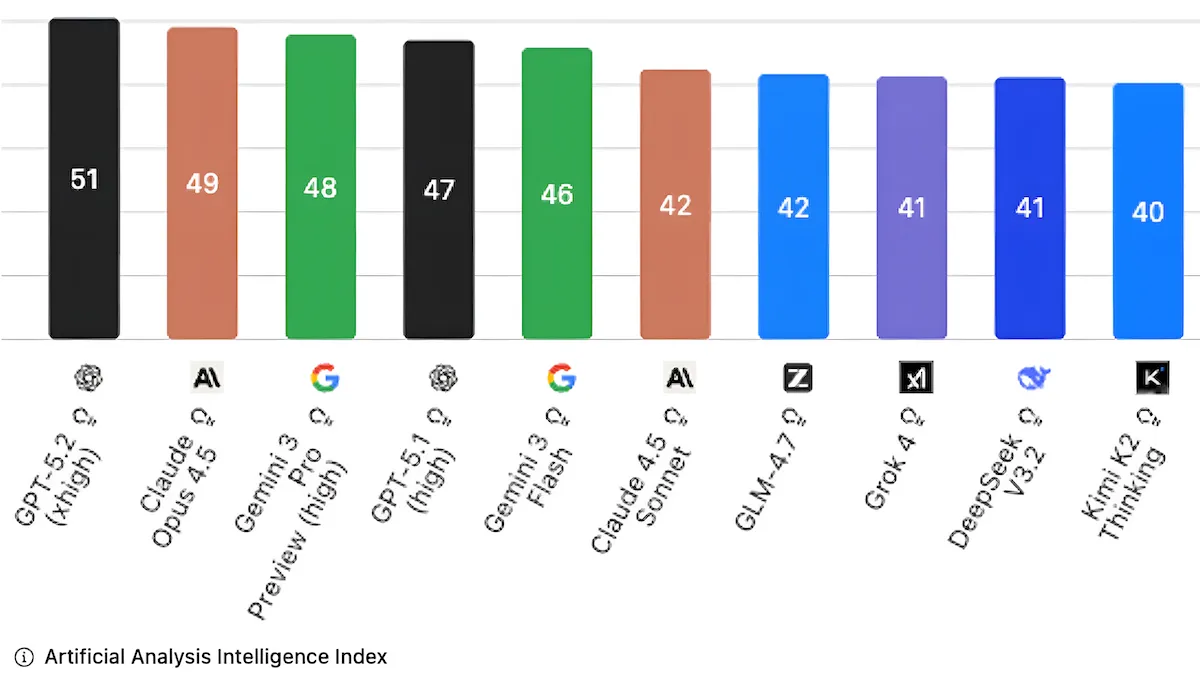 Independent AI Testing Authority Turns From Saturated Knowledge Benchmarks to Harder Business Testsdeeplearning.ai
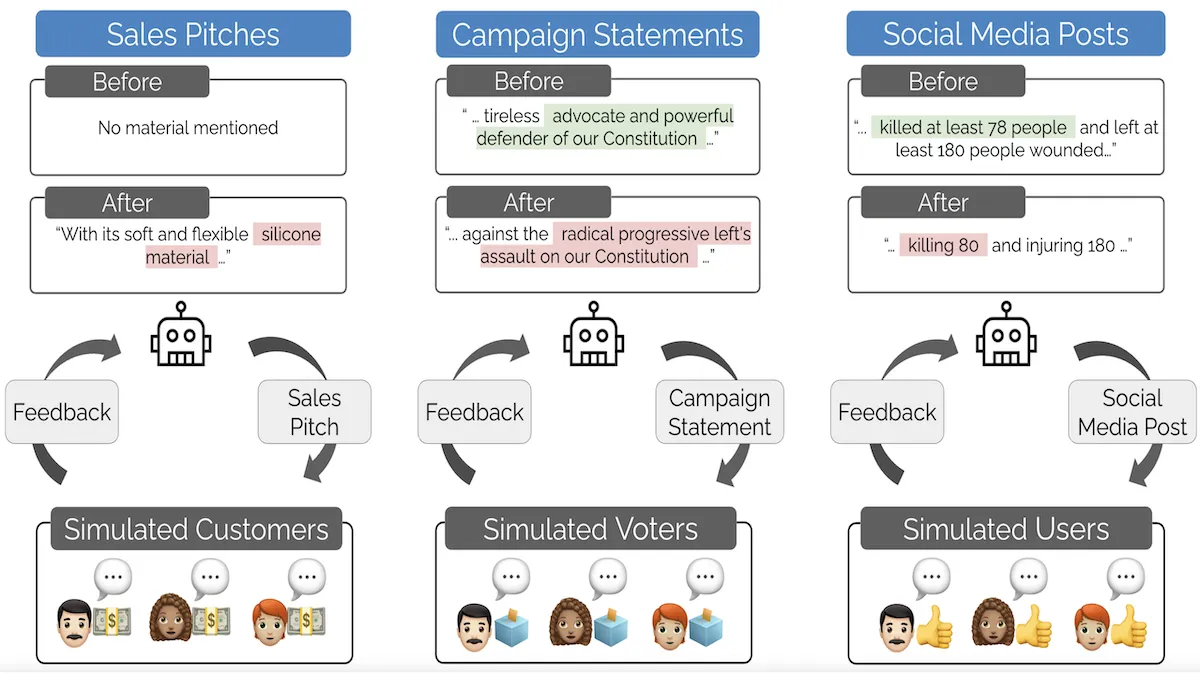 Stanford Researchers Coin “Moloch’s Bargain,” Show Fine-Tuning Can Affect Social Valuesdeeplearning.ai
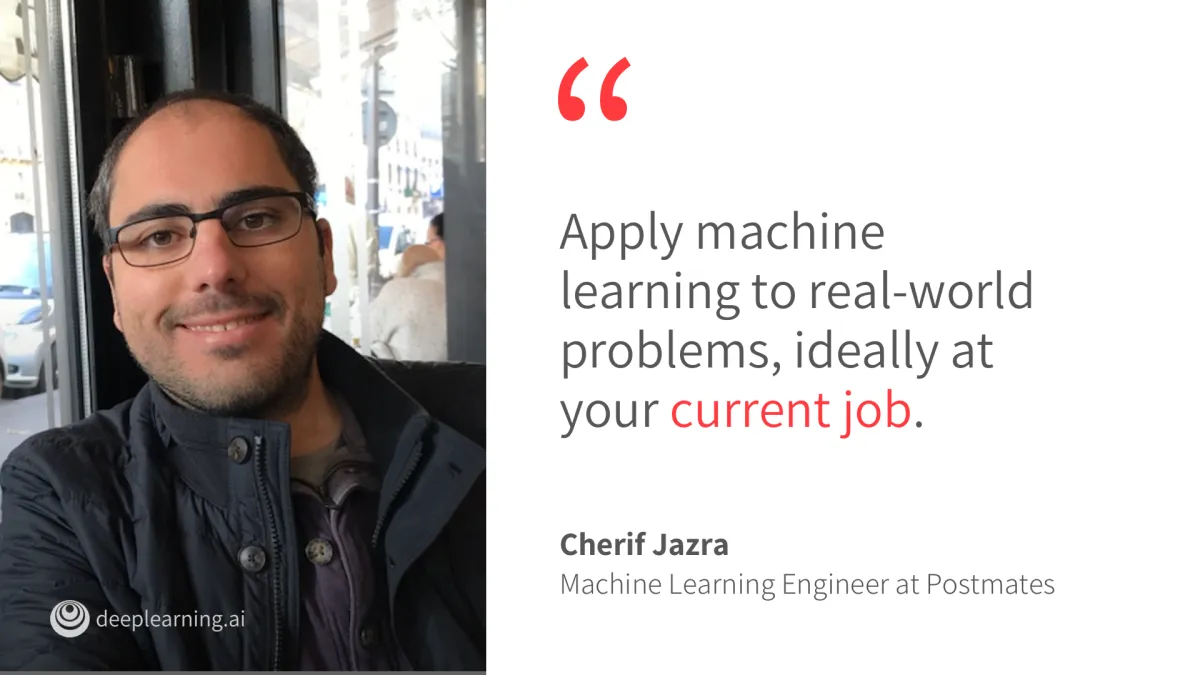 Breaking into AI: Advocating for Machine Learning in the Real Worlddeeplearning.ai
 Docs-as-code solutions for API teams: how to choose the right platform in 2026Mintlify
 Format text - MintlifyMintlify
 Top 3 Use Cases for Speech-to-Text in Gaming - Deepgram Blog ⚡️Deepgram
 Tagalog Speech to TextDeepgram
 Looping by Zapier: Repeat actions for itemsZapier
 Intel Unveils Next Generation Neuromorphic Computing ChipThenewstack
 How Hunch supercharged AI workflows with Modal SandboxesModal
 Building an RL theorem-proving workflow on ModalModal
 4 Ways to Animate the Color of a Text Link on HoverCss Tricks
 The rise of slow personal assistantsCerebras
 Simulating Human Behavior with Cerebras - CerebrasCerebras
 KAUST and Cerebras Named Gordon Bell Award Finalist for Solving Multi-Dimensional SeismicCerebras
 100x Defect Tolerance: How Cerebras Solved the Yield Problem - CerebrasCerebras
 Cerebras Announces Six New AI Datacenters Across North America and Europe to Deliver Industry’sCerebras
