
Efficiently Serving LLMs
Understand how LLMs predict the next token and how techniques like KV caching can speed up text generation. Write code to serve LLM applications efficiently to multiple users.
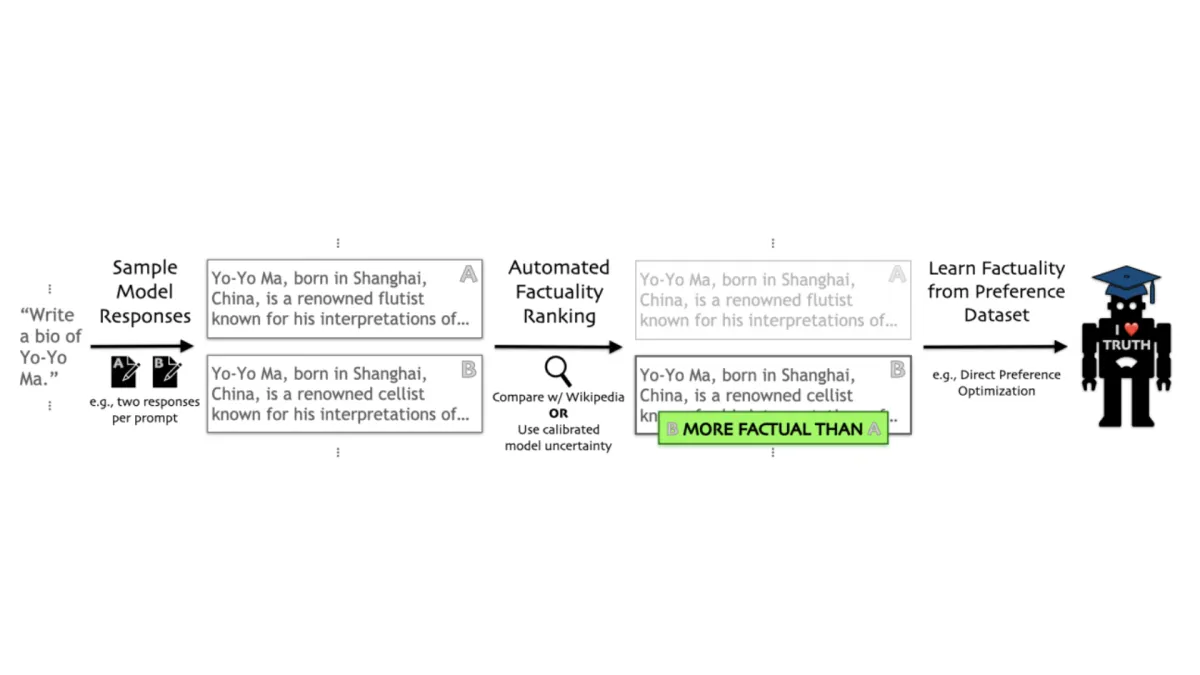 FactTune, A Method to Fine-Tune LLMs for Factual Accuracy Without Human Feedbackdeeplearning.ai
 From AI Experiments to AI Productsdeeplearning.ai
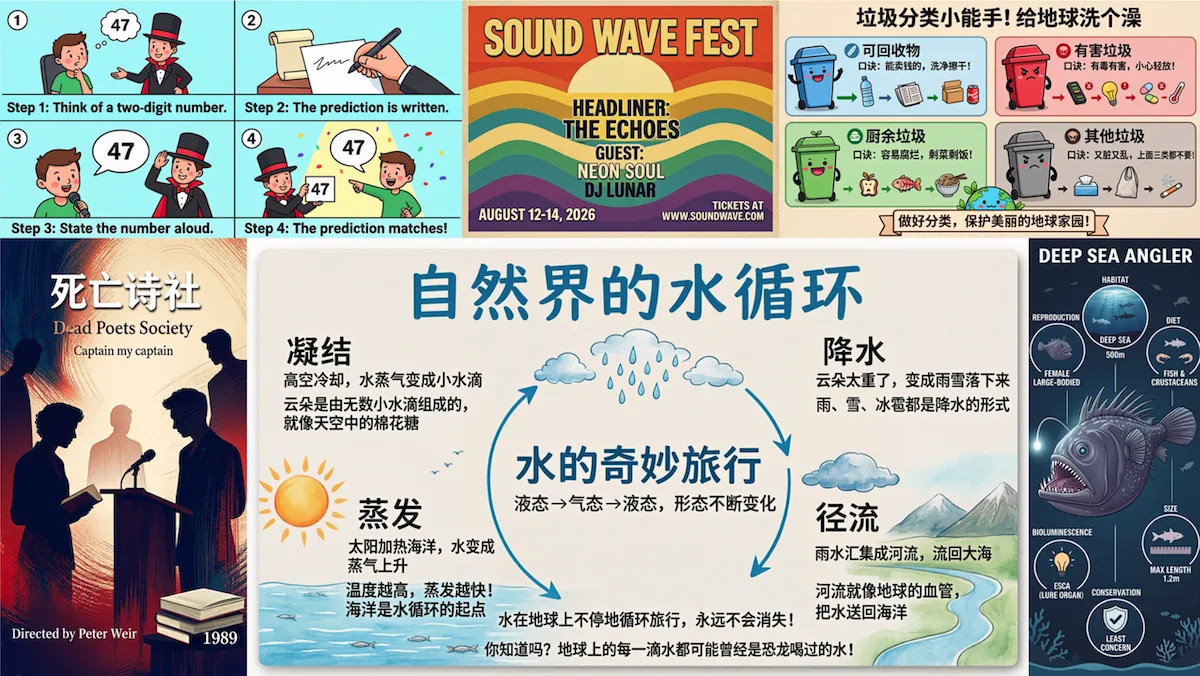 Zhipu’s GLM-Image Blends Transformer and Diffusion Architectures For Better Text in Imagesdeeplearning.ai
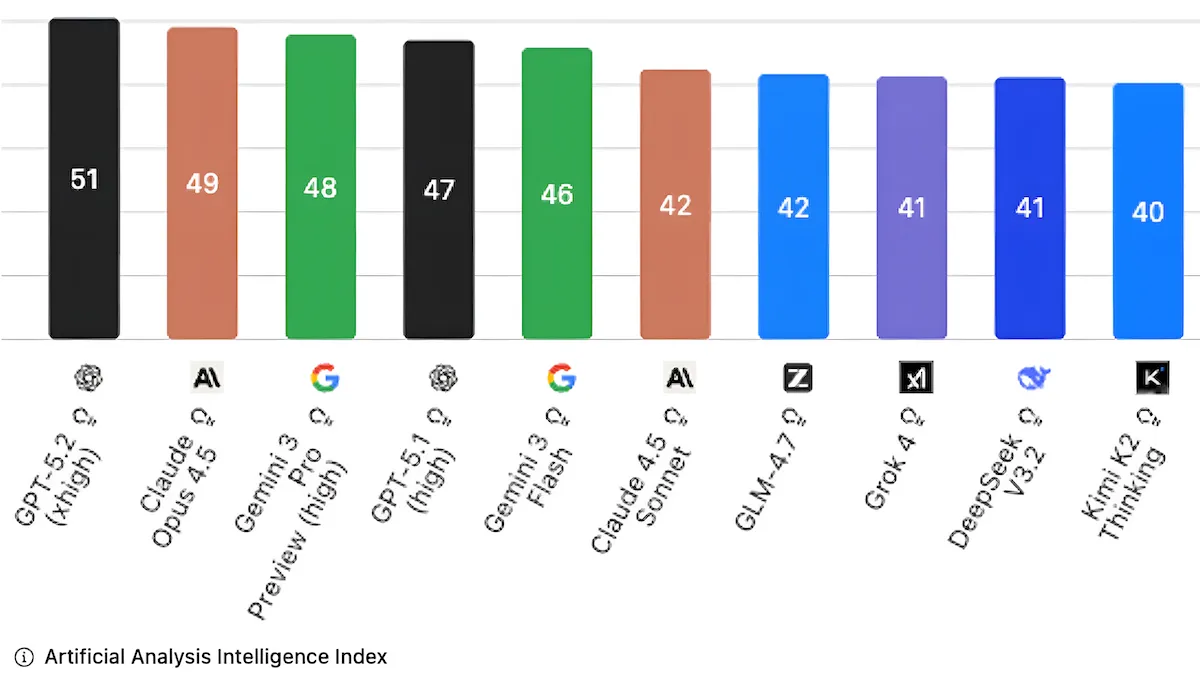 Independent AI Testing Authority Turns From Saturated Knowledge Benchmarks to Harder Business Testsdeeplearning.ai
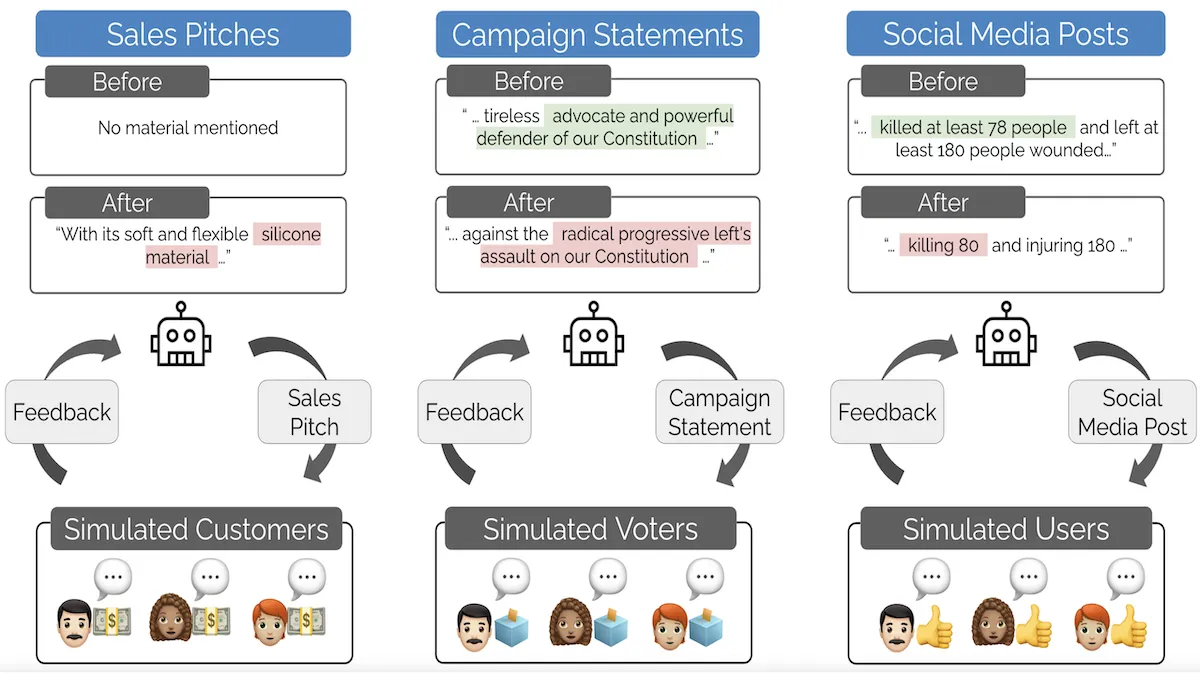 Stanford Researchers Coin “Moloch’s Bargain,” Show Fine-Tuning Can Affect Social Valuesdeeplearning.ai
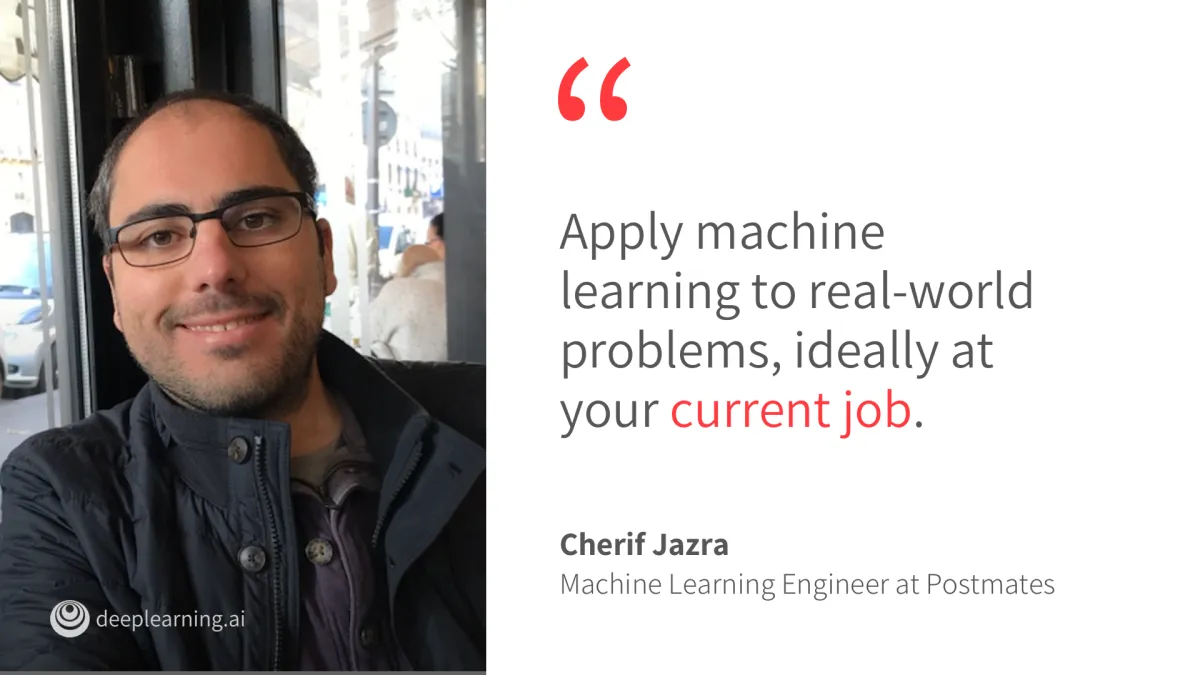 Breaking into AI: Advocating for Machine Learning in the Real Worlddeeplearning.ai
 How to implement AI training for employeesZapier
 Grafana Is Not Worried About AWS CommercializationThenewstack
 How Ramp automated receipt processing with fine-tuned LLMsModal
 How to serve trillions of tokens for trillion-parameter coding agentsModal
 Building an RL theorem-proving workflow on ModalModal
 Duck Duck Stream: How to Efficiently Load Data into DuckLake with EstuaryMotherduck
 How AI Assistants Can Decode GitHub Repos for UI WritersDocker
 6 tips every developer should know when using Cursor and Windsurf AIMintlify
 Modal Clusters are generally availableModal
 Webinar: Migrate from Legacy Platforms to Datadog with AeginDatadoghq
 Maximizing Video Creation with AI ToolsHeygen
 How to structure documentation for both AI and human readersMintlify
 SuperGLUE: Understanding a Sticky Benchmark for LLMsDeepgram
 ChatGPT: Putting the “AI” in “Plagiarism” worldwide?Deepgram
