
Fast LLM Inference with Cerebras
This course, built in partnership with Cerebras and taught by Zhenwei Gao, Sebastian Duerr, and Sarah Chieng of Cerebras, shows you how to build LLM applications that respond in real time on Cerebras' Wafer-Scale Engine (WSE-3). It's a chip large enough to hold a model's weights on-chip, right next to the compute units. You'll run fast inference and see where that speed matters most: latency-sensitive use cases like…
 From AI Experiments to AI Productsdeeplearning.ai
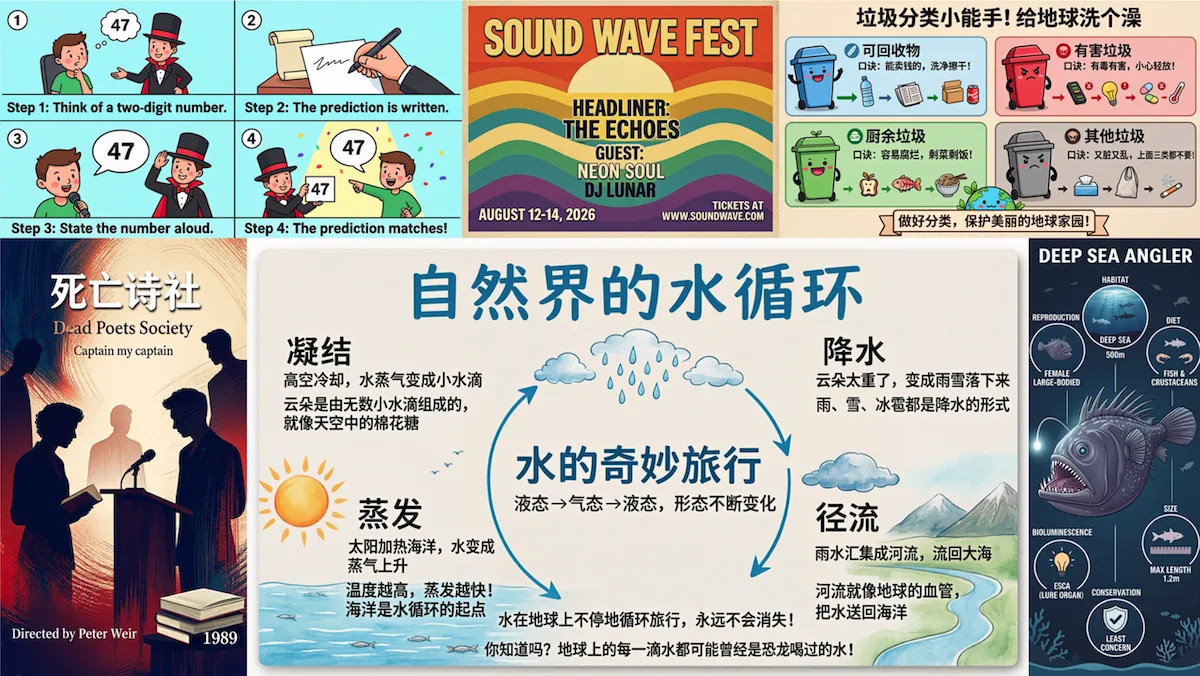 Zhipu’s GLM-Image Blends Transformer and Diffusion Architectures For Better Text in Imagesdeeplearning.ai
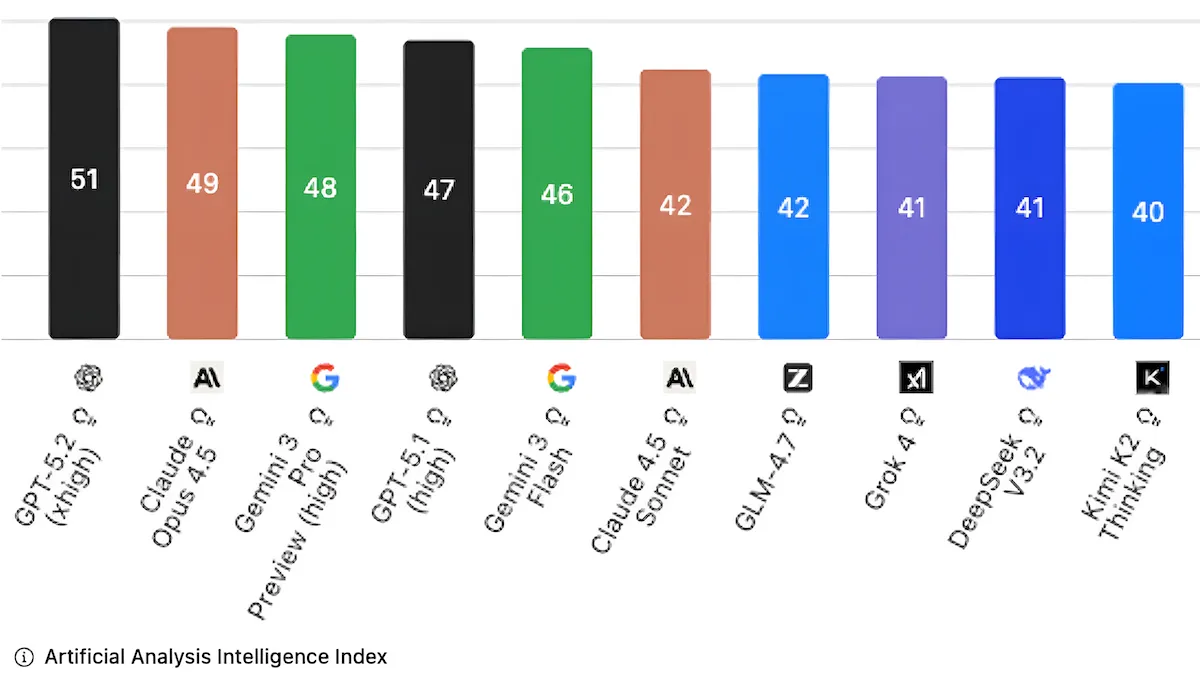 Independent AI Testing Authority Turns From Saturated Knowledge Benchmarks to Harder Business Testsdeeplearning.ai
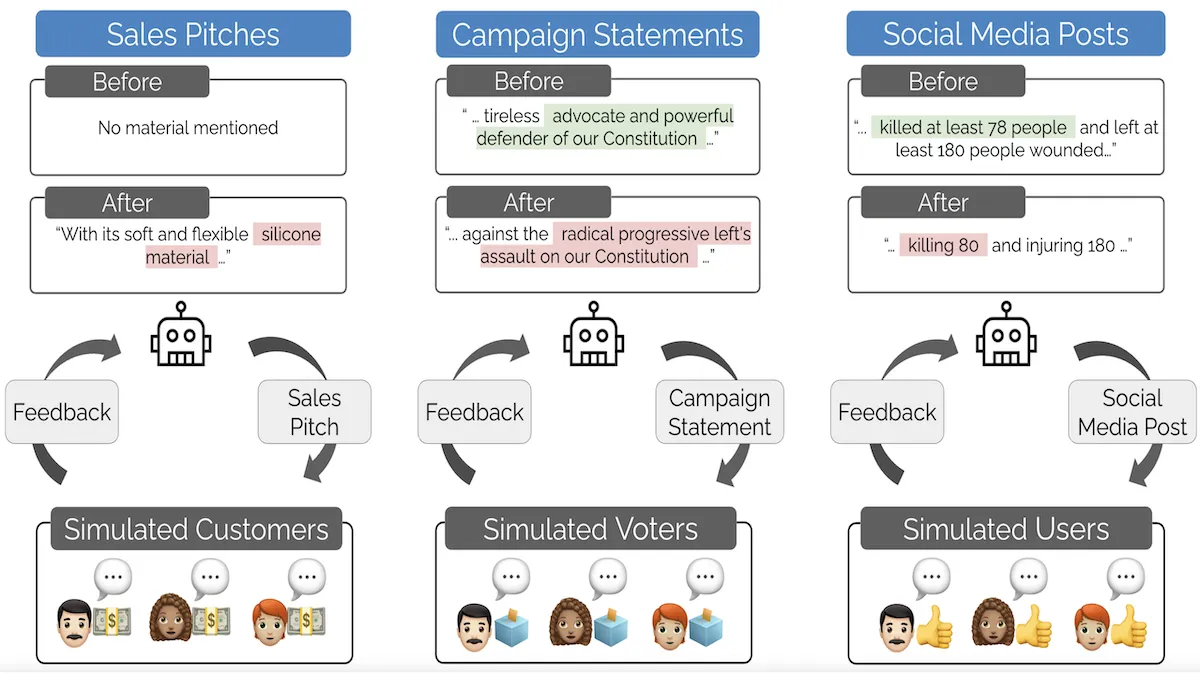 Stanford Researchers Coin “Moloch’s Bargain,” Show Fine-Tuning Can Affect Social Valuesdeeplearning.ai
 Breaking into AI: Advocating for Machine Learning in the Real Worlddeeplearning.ai
 Working AI: At the Office with Research Scientist Archis Joglekardeeplearning.ai
 NoSQLNow! 2014 Case Study: Bleacher Report on Redis LabsRedis
Redis Enterprise Rising!Redis
The Proven Redis PerformanceRedis
Rapid `14 Q1 Growth, 23K+ Customers, 45K+ Instances, 4 Clouds (and 10 Regions)Redis
Redis Labs’ Customers Award Accolades!Redis
Money! Money! Money!Redis
Redis Cloud PrivateRedis
How Redis is Used in Practice | RedisRedis
An Introduction to Redis-ML. Part OneRedis
A Success Story Worth Sharing: Glide.me and Redis LabsRedis
Redis Hacking at the HSHacks III HackathonRedis
Redis Achieves ISO 27001 Cybersecurity CertificationRedis
Local Kubernetes Development Using Minikube and Redis EnterpriseRedis
Ringing in the New Year with a New Office in LondonRedis
