
Fine-tuning & RL for LLMs: Intro to Post-training
Learn how to apply fine-tuning and reinforcement learning techniques to shape model behavior, improve reasoning, and make LLMs safer and more reliable.
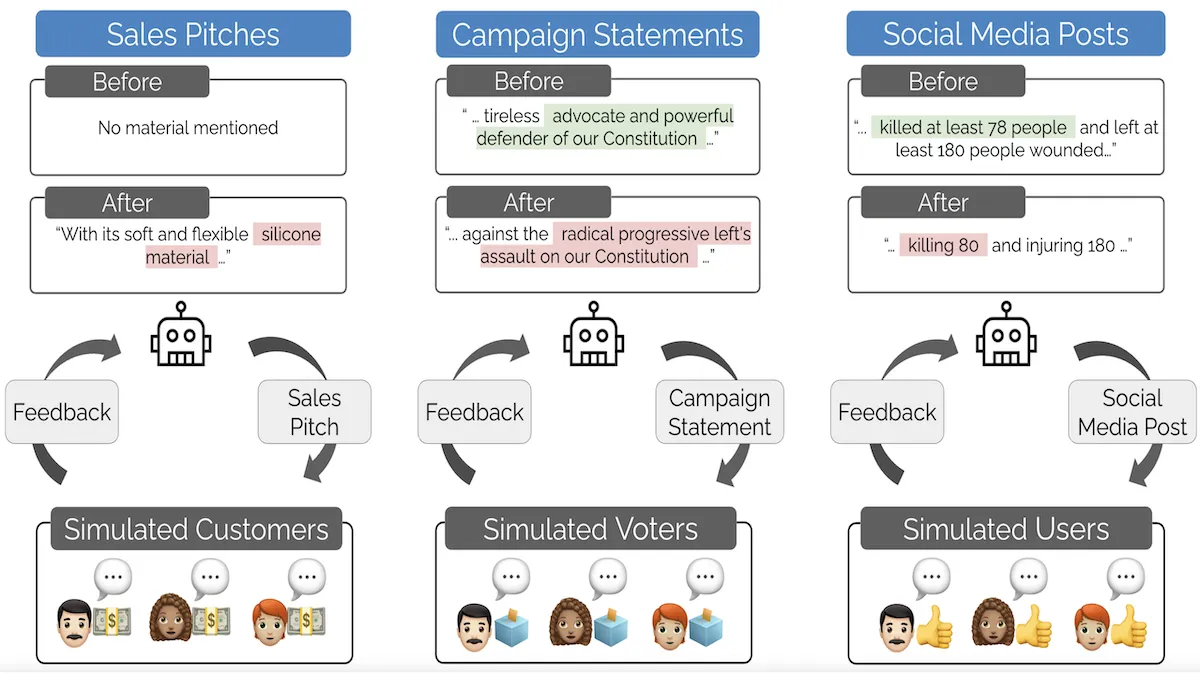 Stanford Researchers Coin “Moloch’s Bargain,” Show Fine-Tuning Can Affect Social Valuesdeeplearning.ai
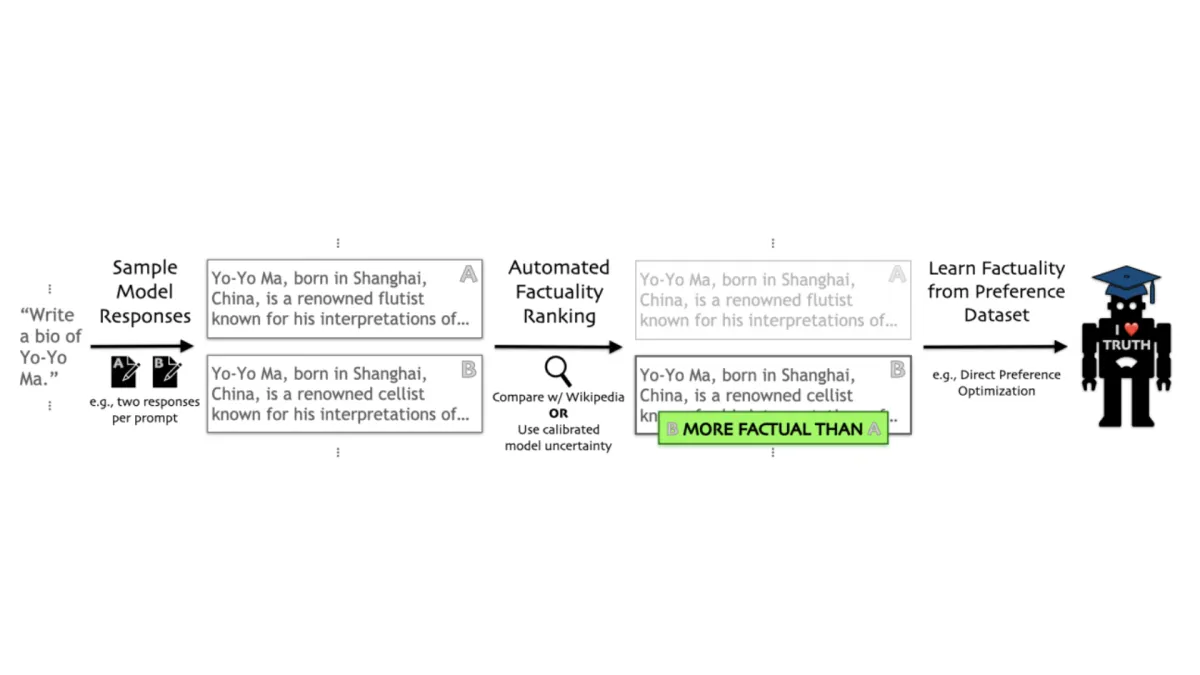 FactTune, A Method to Fine-Tune LLMs for Factual Accuracy Without Human Feedbackdeeplearning.ai
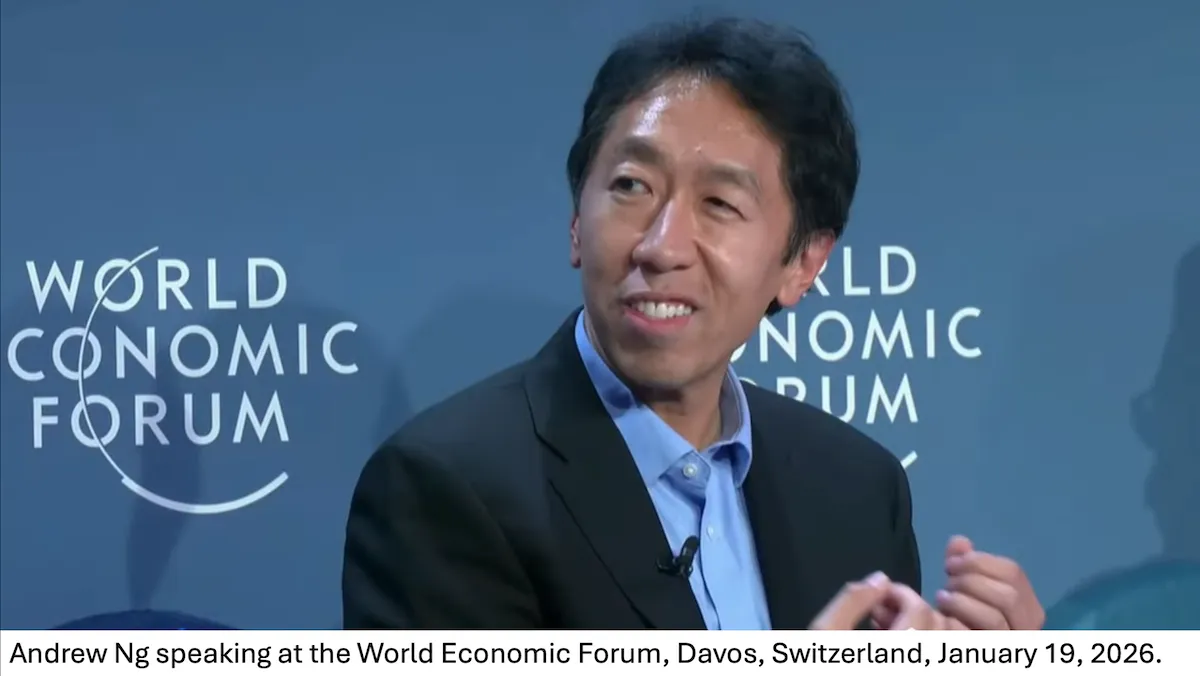 From AI Experiments to AI Productsdeeplearning.ai
 Zhipu’s GLM-Image Blends Transformer and Diffusion Architectures For Better Text in Imagesdeeplearning.ai
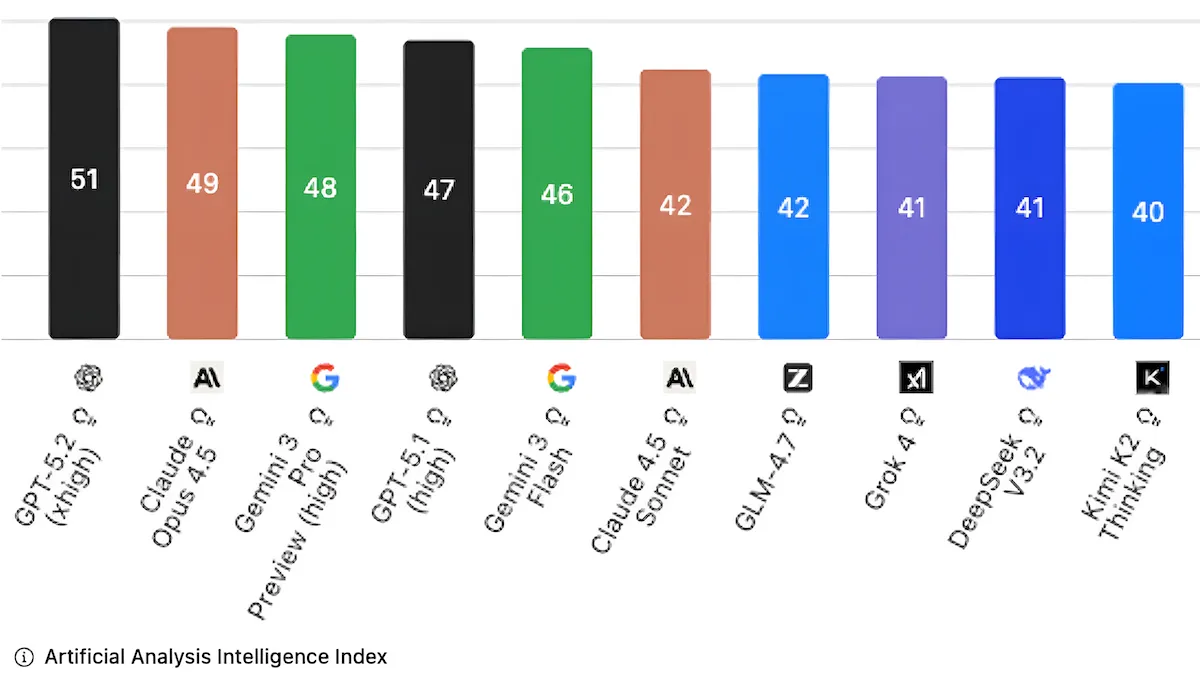 Independent AI Testing Authority Turns From Saturated Knowledge Benchmarks to Harder Business Testsdeeplearning.ai
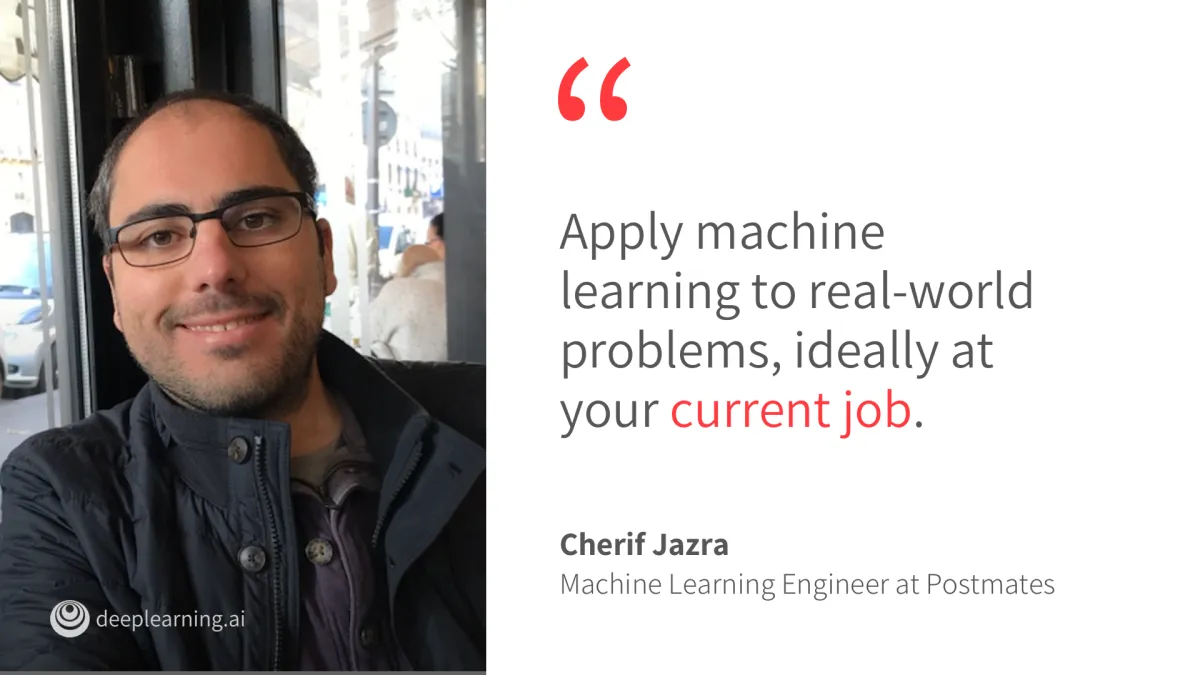 Breaking into AI: Advocating for Machine Learning in the Real Worlddeeplearning.ai
 The Most Important Work in AI Training Is Also the Most Overlooked - Deepgram Blog ⚡️Deepgram
 How to implement AI training for employeesZapier
 AI frameworks: Definition, types, and how to chooseZapier
 New Policy as Code Capabilities with CrossGuardPulumi
 How Ramp automated receipt processing with fine-tuned LLMsModal
 Pseudo-Randomly Adding Illustrations with CSS | CSS-TricksCss Tricks
 Cerebras Raises $1 Billion Series H at $23 Billion ValuationCerebras
 How AI Assistants Can Decode GitHub Repos for UI WritersDocker
 Multi Face Swap Video: How to Swap Multiple Faces in a Single Video with AIHeygen
 Interactive Training Videos (+ How to Create One with AI)Synthesia
 How Beyond Retro scaled its retail operations trainingSynthesia
 How to Create an Online Training CourseSynthesia
 How Mondelez Accelerates Supply Chain Training Across 150+ Global Manufacturing PlantsSynthesia
 Training: Hard Work Pays off for Data/AI ProsThenewstack
