
Reinforcement Fine-Tuning LLMs With GRPO
Improve LLM reasoning with reinforcement fine-tuning and reward functions.
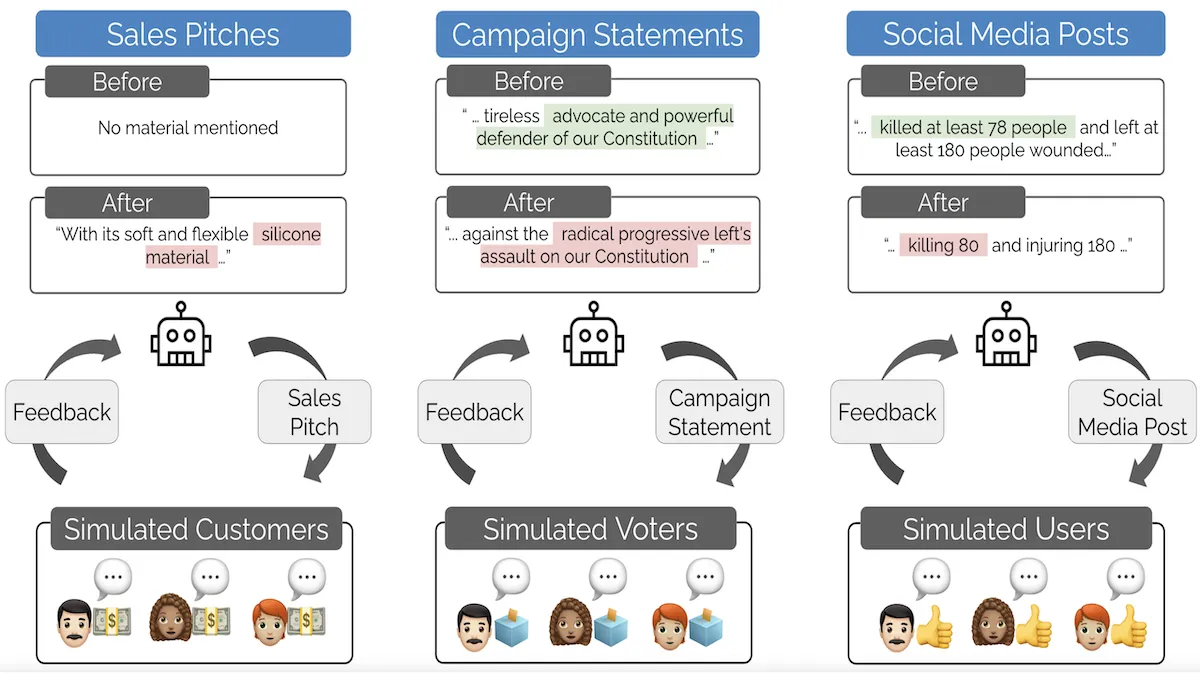 Stanford Researchers Coin “Moloch’s Bargain,” Show Fine-Tuning Can Affect Social Valuesdeeplearning.ai
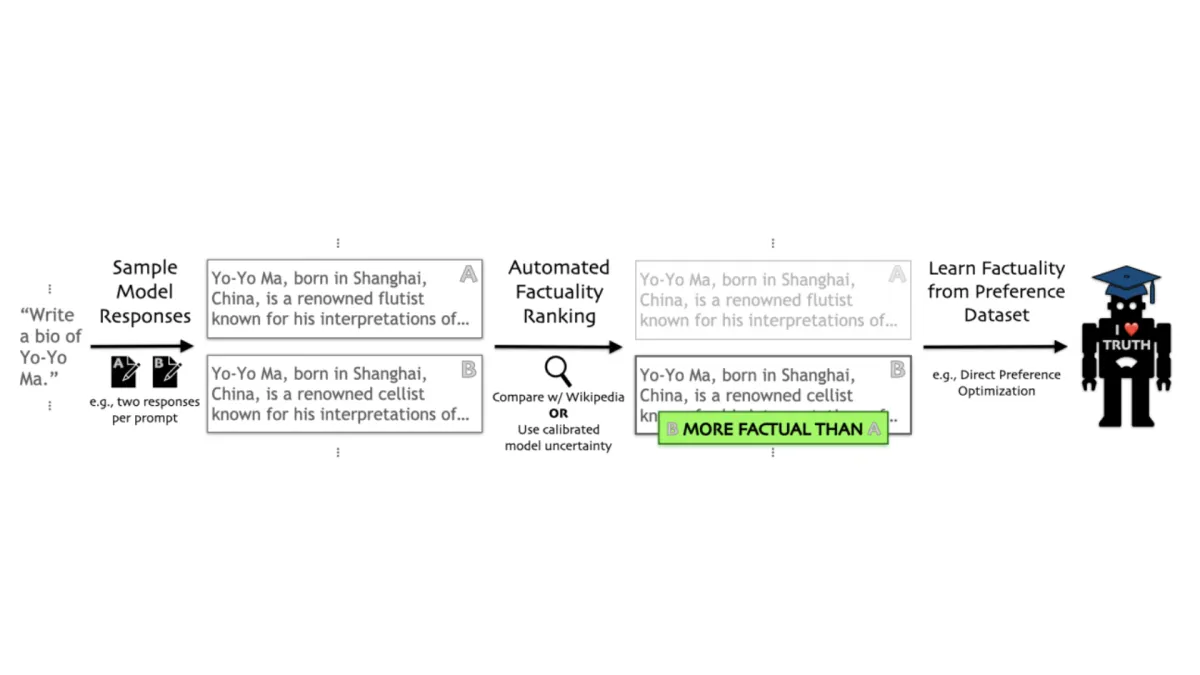 FactTune, A Method to Fine-Tune LLMs for Factual Accuracy Without Human Feedbackdeeplearning.ai
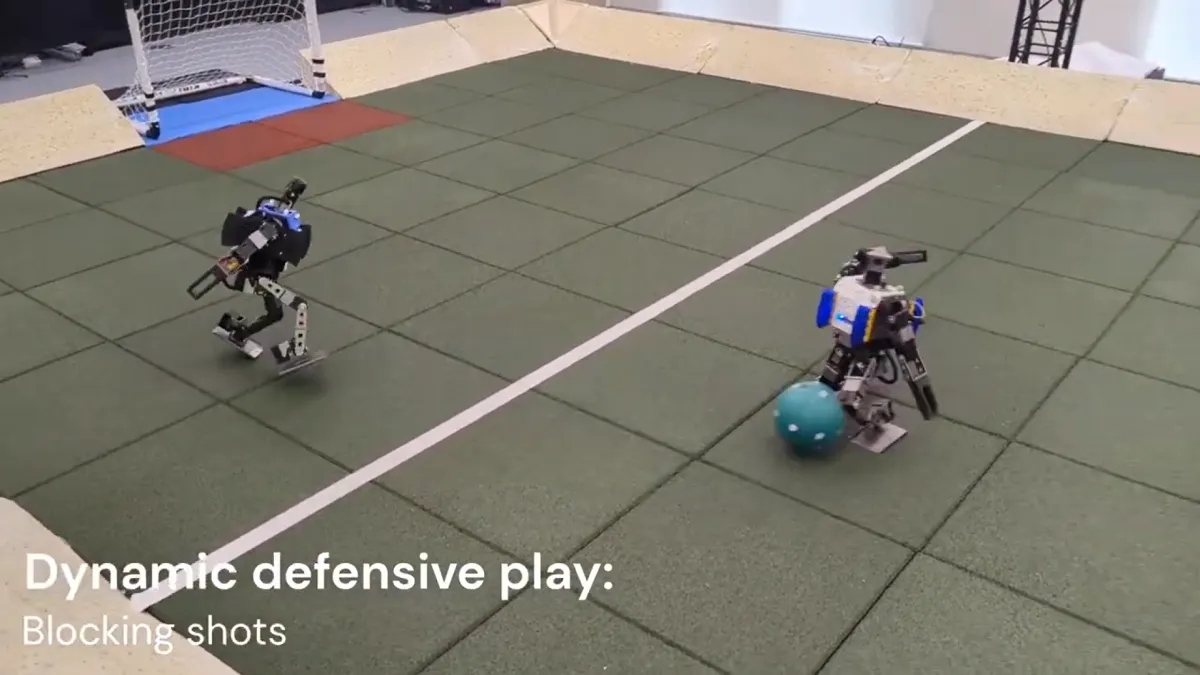 Reinforcement Learning Powers Humanoid Robots to Play Footballdeeplearning.ai
 From AI Experiments to AI Productsdeeplearning.ai
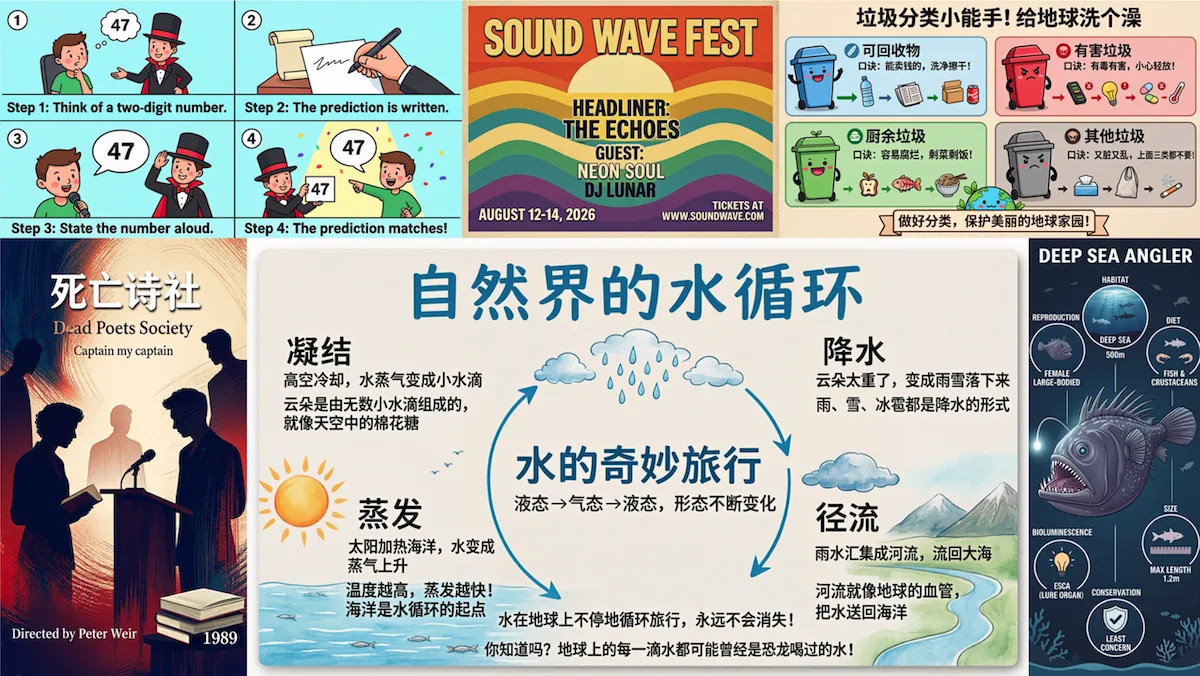 Zhipu’s GLM-Image Blends Transformer and Diffusion Architectures For Better Text in Imagesdeeplearning.ai
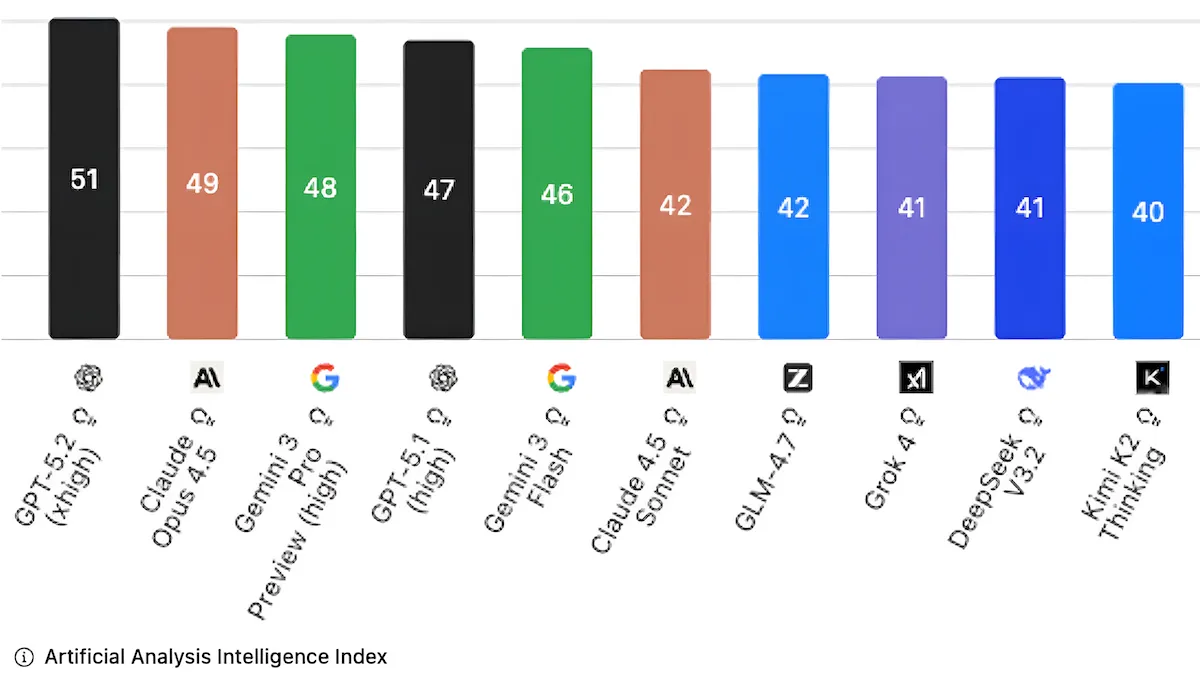 Independent AI Testing Authority Turns From Saturated Knowledge Benchmarks to Harder Business Testsdeeplearning.ai
 How Ramp automated receipt processing with fine-tuned LLMsModal
 How AI Assistants Can Decode GitHub Repos for UI WritersDocker
 Beating proprietary models with a quick fine-tuneModal
 How we fine-tuned Llama2-70B to pass the US Medical License Exam in a weekCerebras
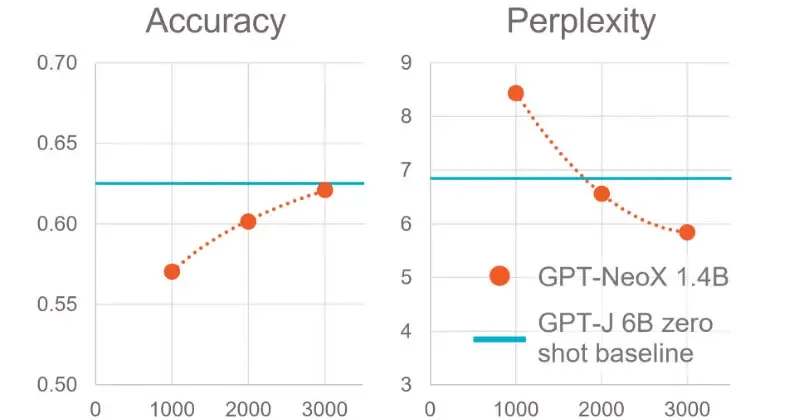 Fine-Tuning with Cerebras AI Model Studio Launchpad - CerebrasCerebras
 How to structure documentation for both AI and human readersMintlify
 SuperGLUE: Understanding a Sticky Benchmark for LLMsDeepgram
 ChatGPT: Putting the “AI” in “Plagiarism” worldwide?Deepgram
 What is RetoolGPT? How we built an internal AI assistantRetool
 Just Enough SQL to Safely Use AI for Data AnalysisMotherduck
 Cerebras 2024 Predictions for Generative AI, LLMs, and HPCCerebras
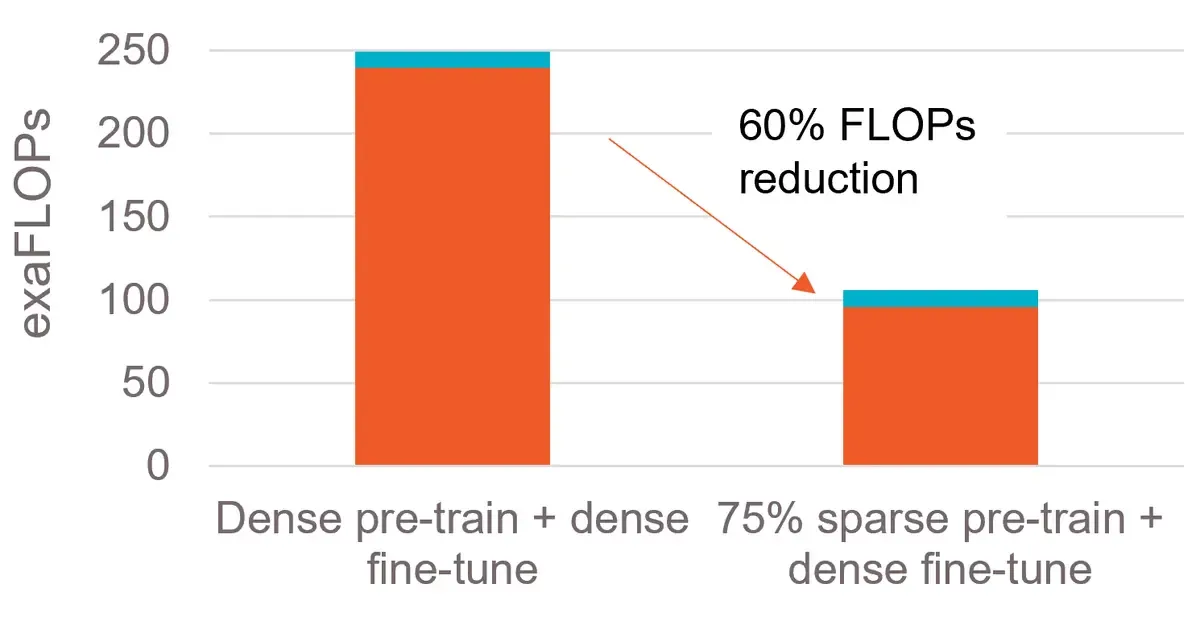 Accelerating Large GPT Training with Sparse Pre-Training and Dense Fine-Tuning [Updated] - CerebrasCerebras
 Free llms.txt generator: create AI-optimized documentation filesMintlify
 Everything you need to know about Voice AI AgentsDeepgram
