
Reinforcement Learning From Human Feedback
Get an introduction to tuning and evaluating LLMs using Reinforcement Learning from Human Feedback (RLHF) and fine-tune the Llama 2 model.
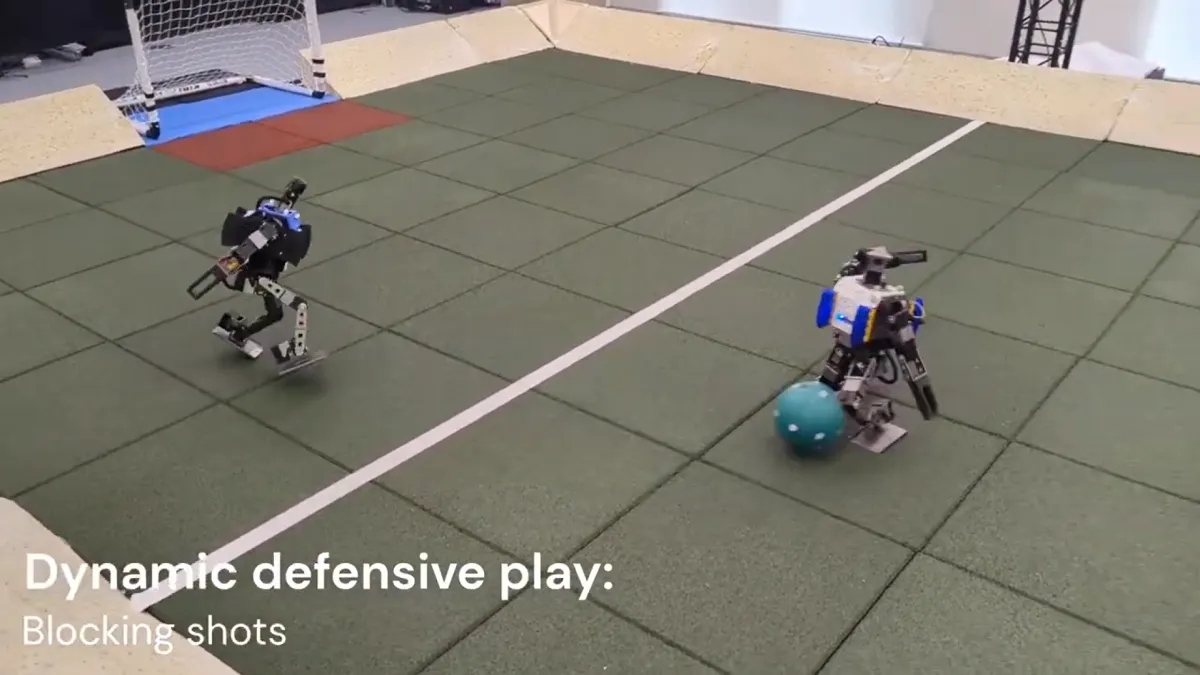 Reinforcement Learning Powers Humanoid Robots to Play Footballdeeplearning.ai
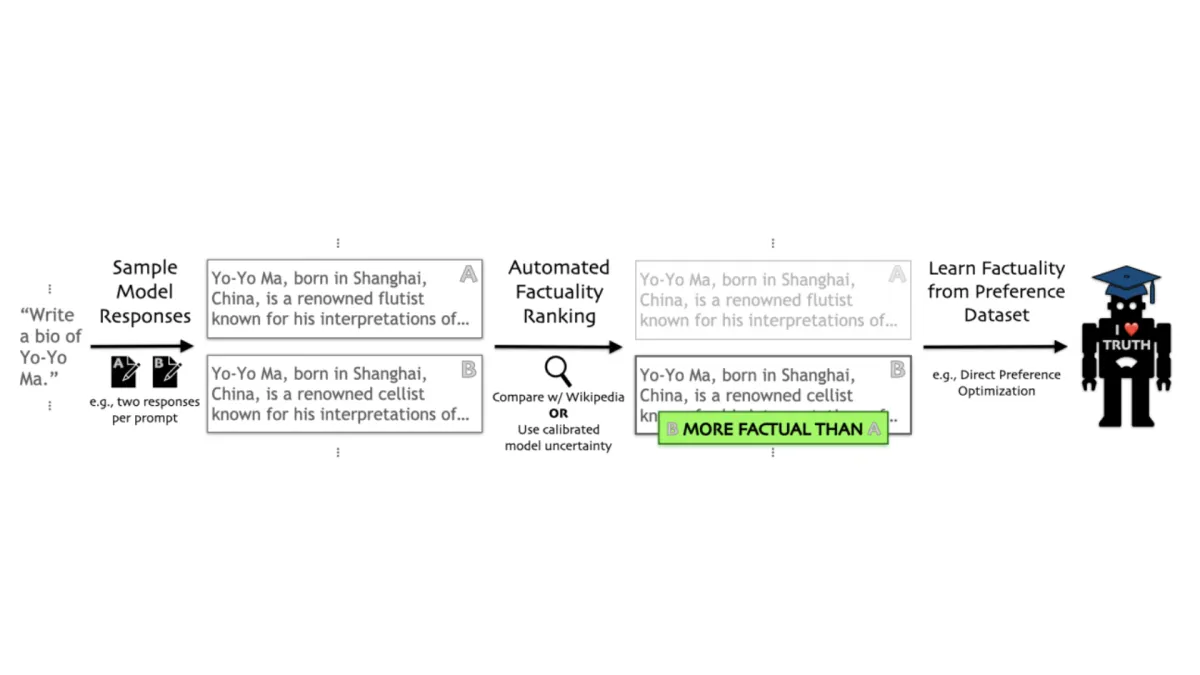 FactTune, A Method to Fine-Tune LLMs for Factual Accuracy Without Human Feedbackdeeplearning.ai
 Breaking into AI: Advocating for Machine Learning in the Real Worlddeeplearning.ai
 From AI Experiments to AI Productsdeeplearning.ai
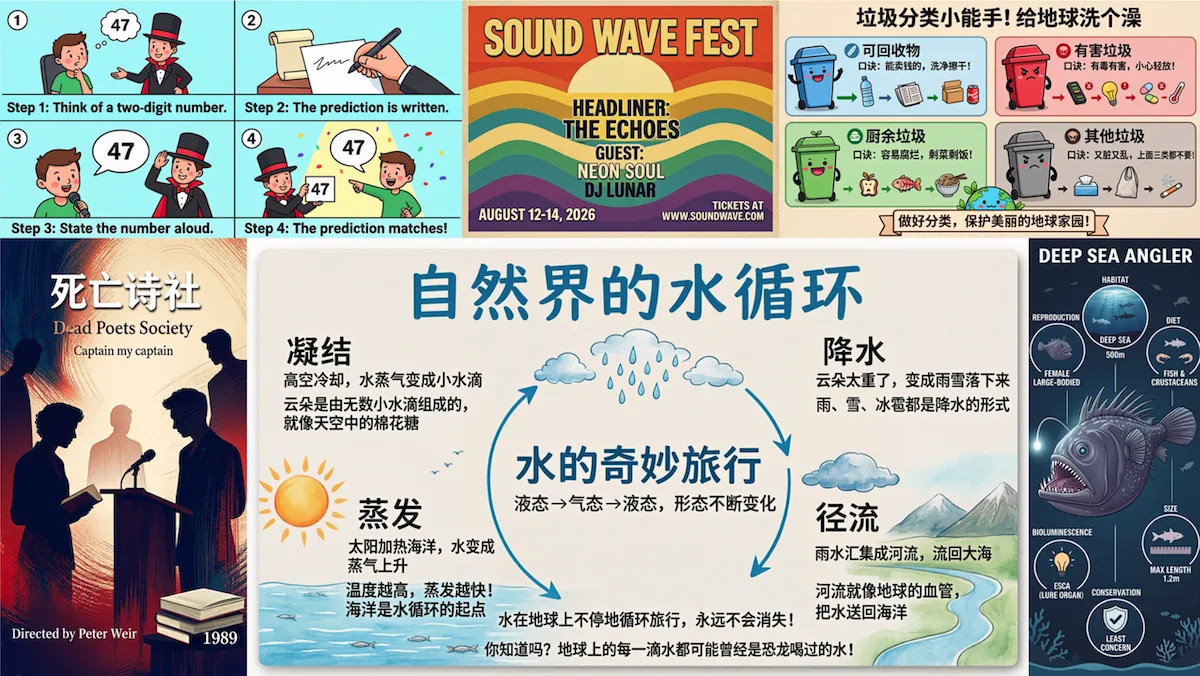 Zhipu’s GLM-Image Blends Transformer and Diffusion Architectures For Better Text in Imagesdeeplearning.ai
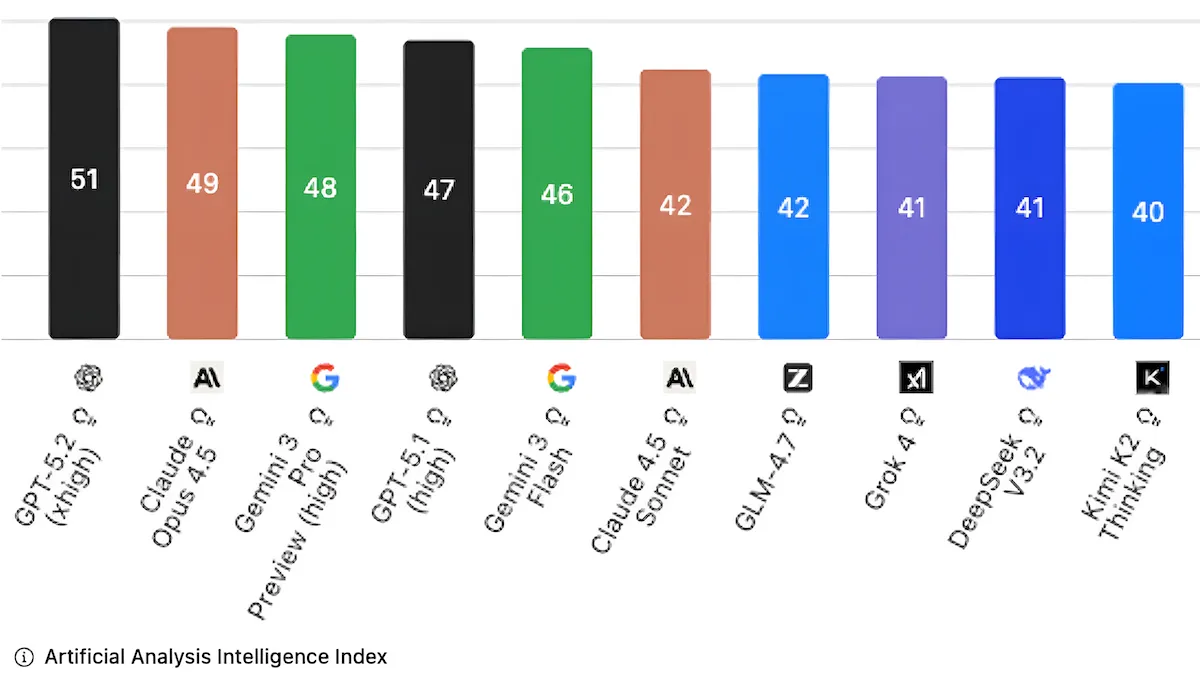 Independent AI Testing Authority Turns From Saturated Knowledge Benchmarks to Harder Business Testsdeeplearning.ai
 10 best AI observability tools for monitoring and evaluating agents in 2026Mintlify
 Lessons Swift Designer Chris Lattner Has Learned about LeadershipThenewstack
 Summer Data Engineering RoadmapMotherduck
 Revolutionizing Life Science and Healthcare with Generative AI - CerebrasCerebras
 Simulating Human Behavior with Cerebras - CerebrasCerebras
 The Livecycle Docker Extension: Instantly Share Changes and Get Feedback in ContextDocker
 How To Create and Use Avatars in eLearningHeygen
 Export analytics to CSV - MintlifyMintlify
 From Hawking to Siri: The Evolution of Speech SynthesisDeepgram
 How Sky Italia Digitizes Learning Paths to Accelerate New Product Launches by 4xSynthesia
 How EPOS achieved a 90% learning completition rate with AI video.Synthesia
 How Mondelez Accelerates Supply Chain Training Across 150+ Global Manufacturing PlantsSynthesia
 Training: Hard Work Pays off for Data/AI ProsThenewstack
 Breakdown: The Kubernetes-Run AI Video Generation Pipeline for NIUS.TVThenewstack
