
How to extract content from a Shadow DOM
Certain websites may hide all of their page content inside a shadow root, which makes scraping them quite challenging.
 How to extract CSS selectors using ChromeScrapingBee
How to extract a tableScrapingBee
How to handle infinite scroll pages in NodeJSScrapingBee
Retry failed requests in C#ScrapingBee
What is Cheerio in JavaScript?ScrapingBee
How to Retry Failed Requests in RubyScrapingBee
 Pancakes Are Delicious and Data Centers Are for Free StuffThenewstack
 Transform and Future-Proof Your Architecture with MACHThenewstack
 Selecting the Right Database for Your MicroservicesThenewstack
 Svelte for the Experienced React DevCss Tricks
 Scaling Organizations Should Consider Building a Website Backed by a CRM PlatformCss Tricks
 Supporting the jsDelivr open source CDN with bandwidth for developersBunny
 Best AI Video Generator for TikTok in 2026 (Tried & Tested)Heygen
 Facebook Subscription Groups for ContentHeygen
 View - MintlifyMintlify
 This Week in Programming: Google Gets into the Open Source Insights GameThenewstack
 Linux Foundation: Why Open Source Needs Research NowThenewstack
 Push vs. Pull in GitOps: Is There Really a Difference?Thenewstack
 Magma Brings a Systems Approach to Wireless NetworkingThenewstack
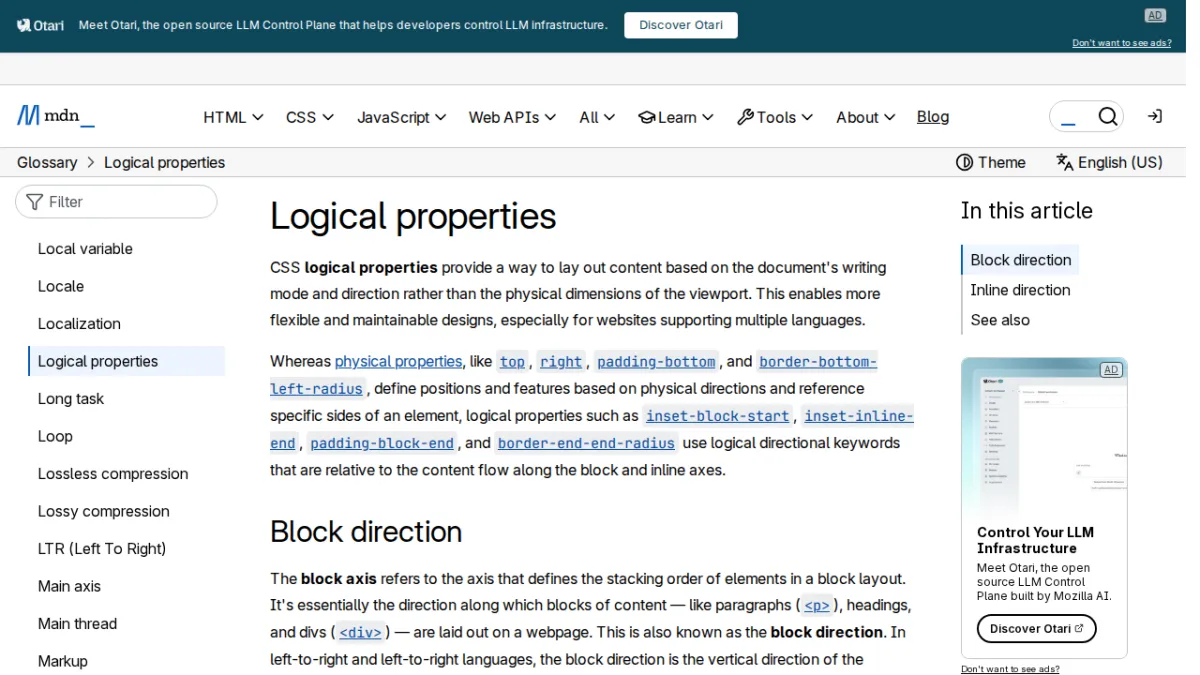 Logical properties - GlossaryDeveloper Mozilla
