
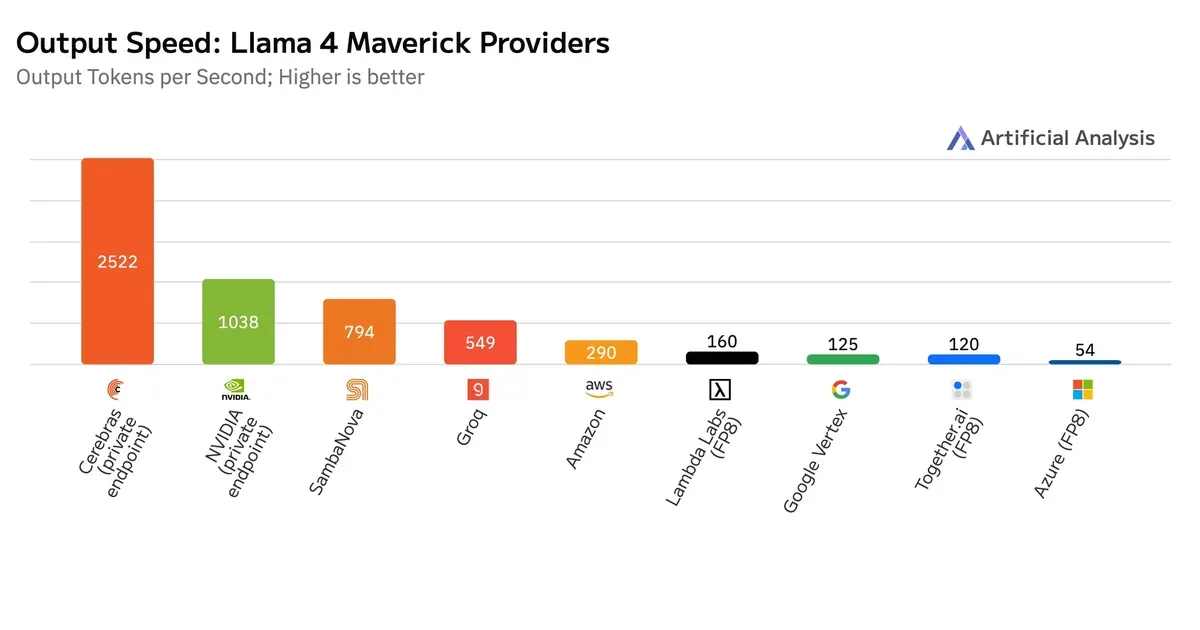
Cerebras beats NVIDIA Blackwell: Llama 4 Maverick Inference
At over 2,500 t/s, Cerebras has set a world record for LLM inference speed on the 400B parameter Llama 4 Maverick model, the largest in the Llama 4 family.
 AMD and Cerebras Announce Disaggregated AI InferenceCerebras
 Cerebras Systems Announces Filing of Registration Statement for Proposed Initial Public OfferingCerebras
 KAUST and Cerebras Named Gordon Bell Award Finalist for Solving Multi-Dimensional SeismicCerebras
 Cerebras Raises $1 Billion Series H at $23 Billion ValuationCerebras
Cerebras Announces Six New AI Datacenters Across North America and Europe to Deliver Industry’sCerebras
Cerebras Systems Enables GPU-Impossible™ Long Sequence Lengths Improving Accuracy in NaturalCerebras
 Introducing: H100s on ModalModal
 The rise of slow personal assistantsCerebras
 Simulating Human Behavior with Cerebras - CerebrasCerebras
 100x Defect Tolerance: How Cerebras Solved the Yield Problem - CerebrasCerebras
 Cerebras Systems, Ranovus win $45 million US military deal to speed up chip connectionsCerebras
 Cerebras Systems Raises $250M in Funding for Over $4B Valuation to Advance the Future of ArtificialCerebras
Cerebras Is Coming to AWS Bedrock for Fast AI InferenceCerebras
Cerebras Systems Announces Filing of Registration Statement for Proposed Initial Public OfferingCerebras
 Gemma 4 on Cerebras—The Fastest Inference is Now MultimodalCerebras
 Documentation - JS Projects Utilizing TypeScriptTypescriptlang
 How we used evals and inference-time compute scaling to generate beautiful QR codes that actuallyModal
 Introducing: B200s and H200s on ModalModal
 What are the CUDA Binary Utilities?Modal
Cerebras April HighlightsCerebras
