
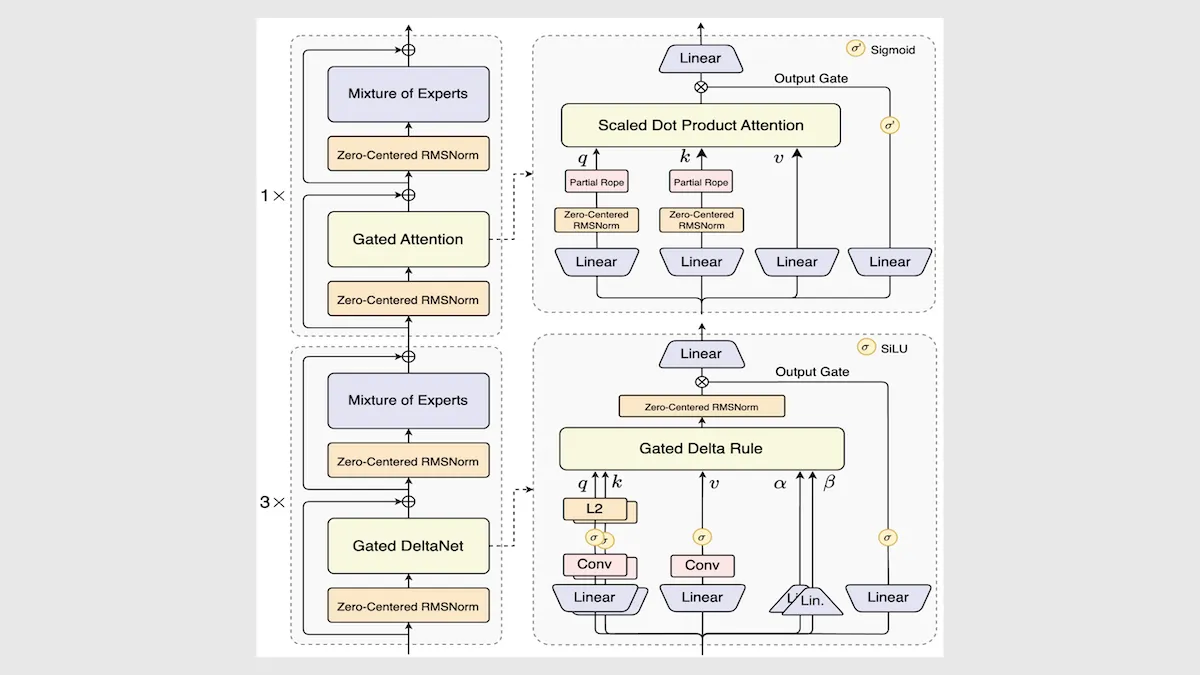
Alibaba’s New Model Uses Hybrid Attention Layers and a Sparse MoE Architecture For Speed and
Alibaba updated its popular Qwen3 open-weights models with a number of fresh, speed-boosting tweaks.
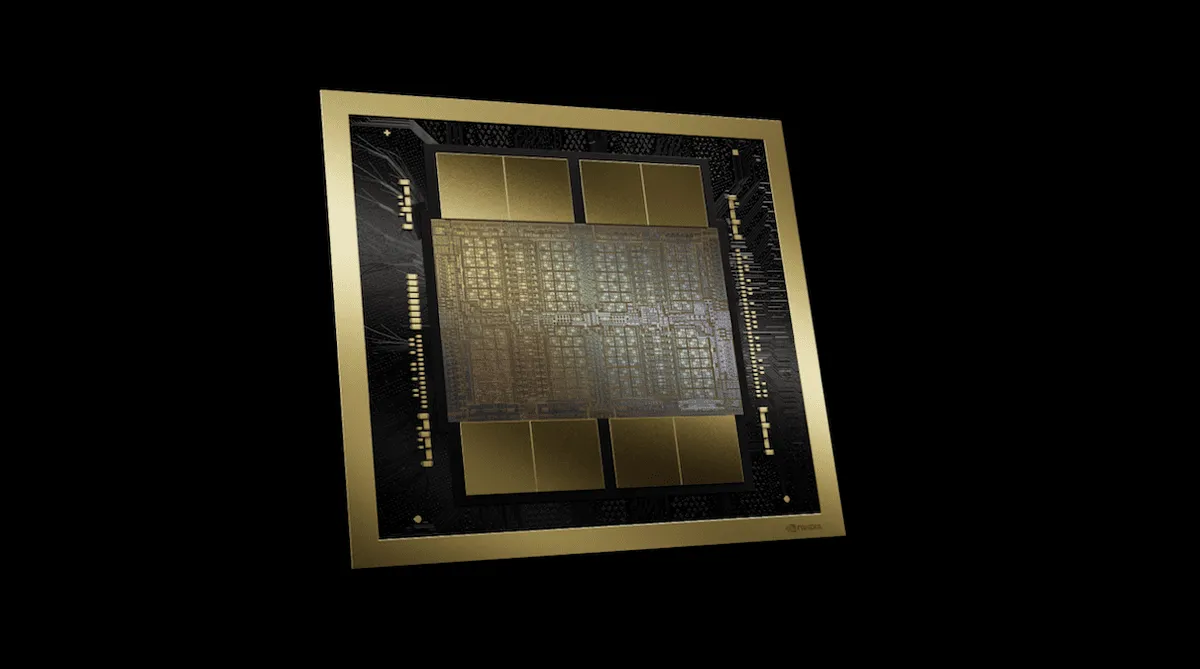 All About Nvidia's New Blackwell Architecture and B200 GPUdeeplearning.ai
 From AI Experiments to AI Productsdeeplearning.ai
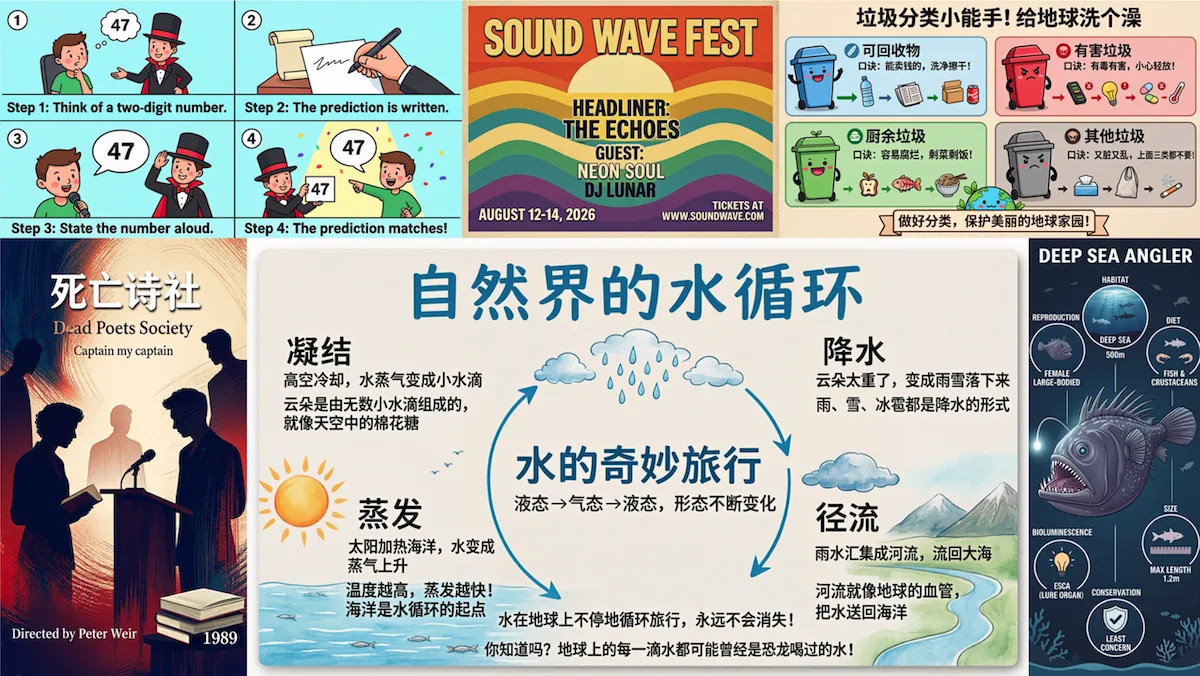 Zhipu’s GLM-Image Blends Transformer and Diffusion Architectures For Better Text in Imagesdeeplearning.ai
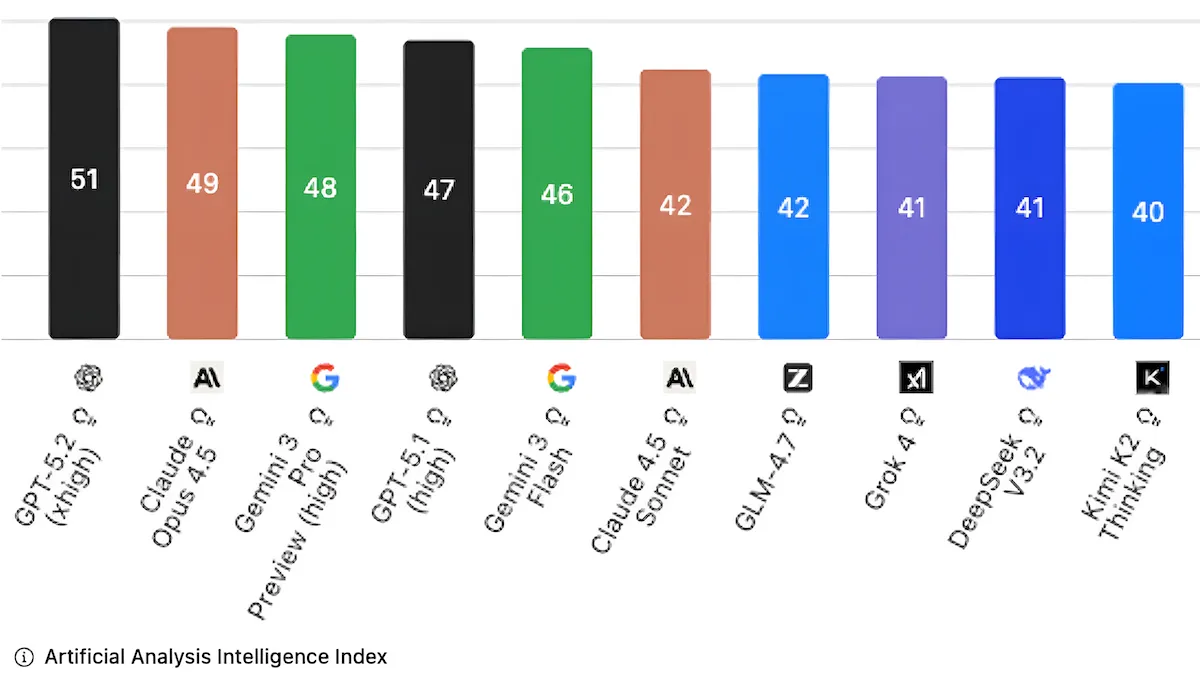 Independent AI Testing Authority Turns From Saturated Knowledge Benchmarks to Harder Business Testsdeeplearning.ai
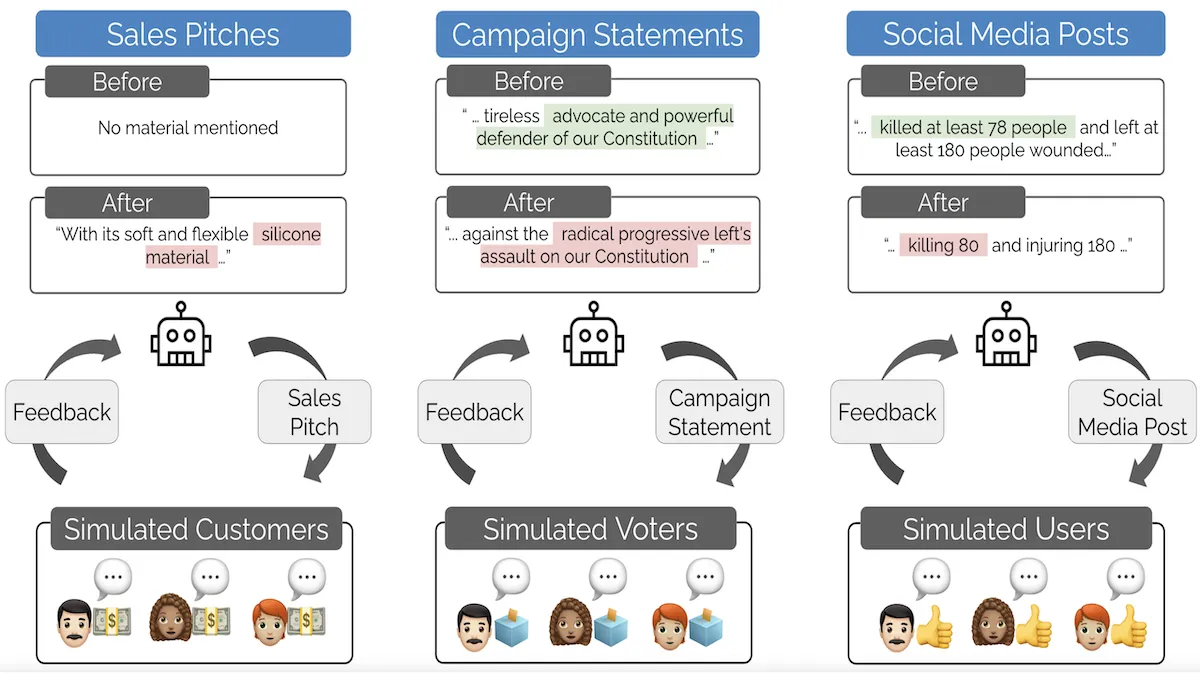 Stanford Researchers Coin “Moloch’s Bargain,” Show Fine-Tuning Can Affect Social Valuesdeeplearning.ai
 Secretary of War Pete Hegseth Calls Claude a Security Risk, Replaces It With GPT Modelsdeeplearning.ai
 New Spanish and Turkish Language Models and Updated General Models - Deepgram Blog ⚡️Deepgram
 Data Ingestion: 6 Ways to Speed Up Your ApplicationRedis
 How CoverDoc uses AI to revolutionize cover letter writingZapier
 From Automation Veteran to AI Pioneer: How Evan Nison transformed his agency with Zapier MCPZapier
 DevSecOps: Why Security Shouldn’t be Sacrificed for SpeedThenewstack
 Three Key Design Considerations for an Event-Driven ArchitectureThenewstack
 Transform and Future-Proof Your Architecture with MACHThenewstack
 Introducing CORPS: The 5 Pillars for a Robust Cloud Architecture FrameworkThenewstack
 Supporting Kubernetes with Faster, Easier Test EnvironmentsPulumi
 The Go Memory Model - The Go Programming LanguageGo
Managing dependencies - The Go Programming LanguageGo
Module version numbering - The Go Programming LanguageGo
 What is a CUDA Thread Block?Modal
 How Ramp automated receipt processing with fine-tuned LLMsModal
