
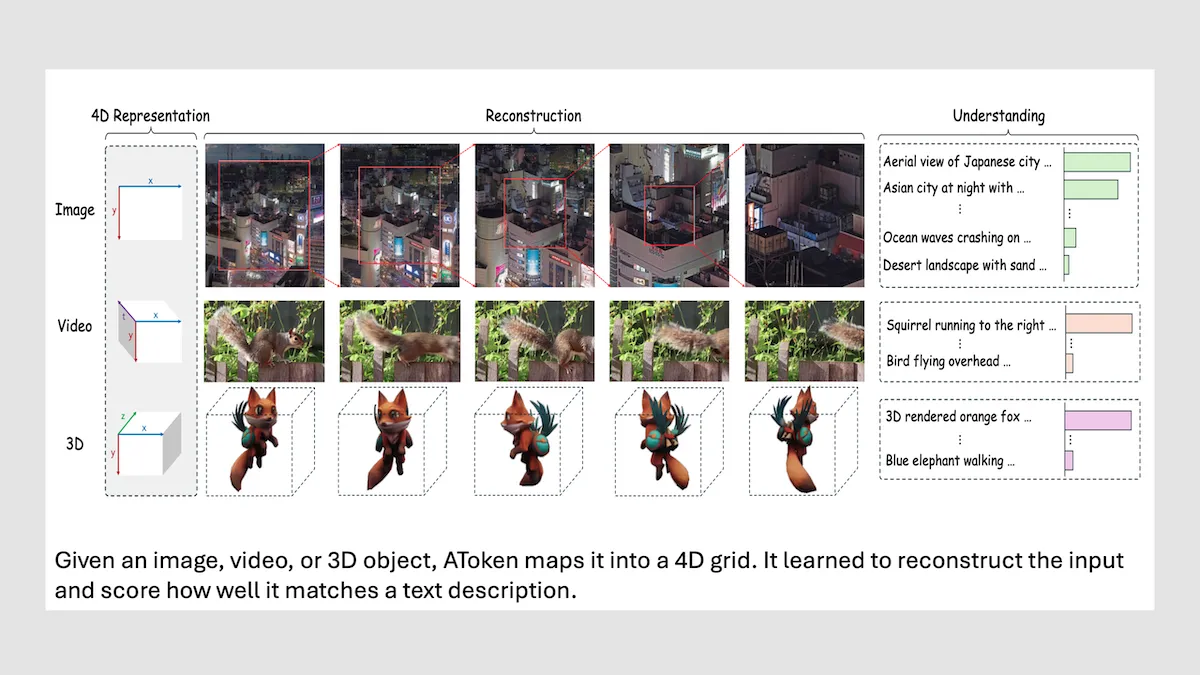
Apple’s AToken, a Multimodal Model with a Single Encoder and Tokenizer for Images, Videos, and 3D
Multimodal models typically use different tokenizers to embed different media types, and different encoders when training to generate media rather...
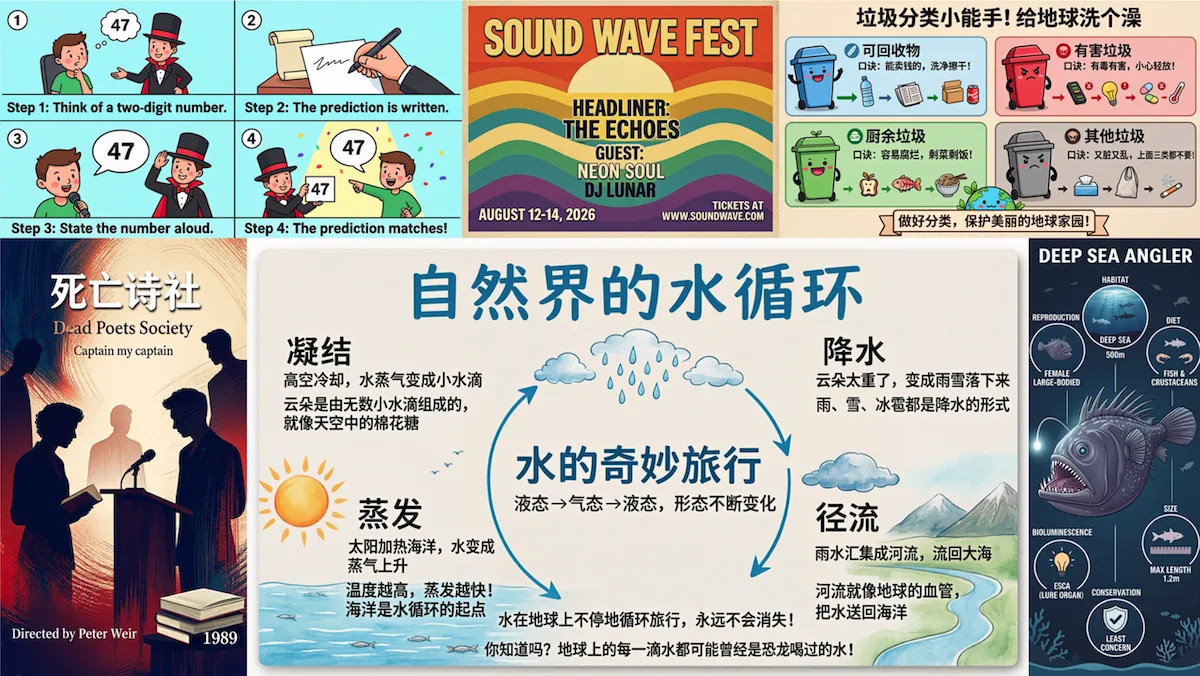 Zhipu’s GLM-Image Blends Transformer and Diffusion Architectures For Better Text in Imagesdeeplearning.ai
 From AI Experiments to AI Productsdeeplearning.ai
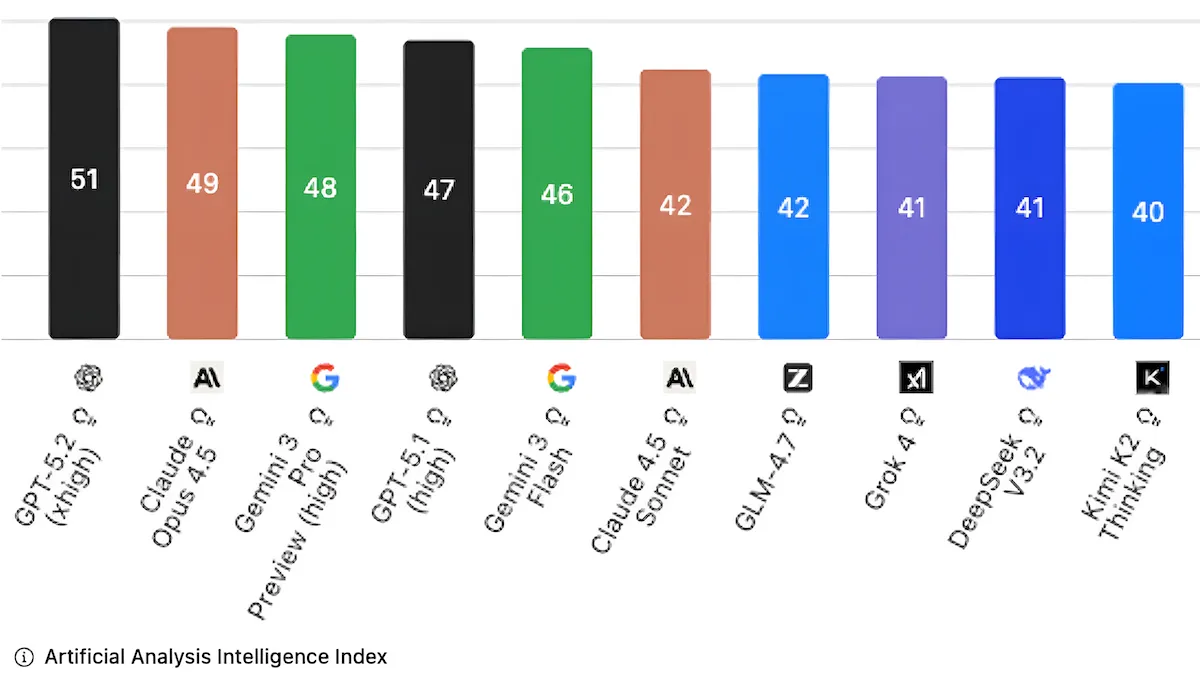 Independent AI Testing Authority Turns From Saturated Knowledge Benchmarks to Harder Business Testsdeeplearning.ai
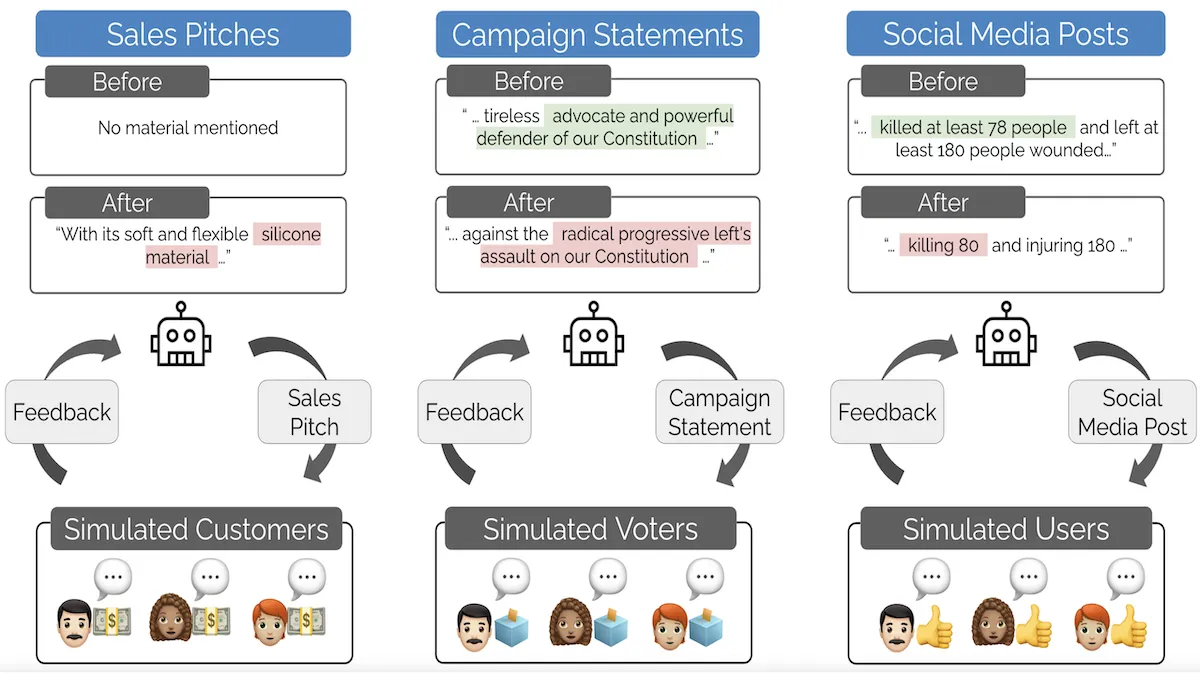 Stanford Researchers Coin “Moloch’s Bargain,” Show Fine-Tuning Can Affect Social Valuesdeeplearning.ai
 Secretary of War Pete Hegseth Calls Claude a Security Risk, Replaces It With GPT Modelsdeeplearning.ai
 Data Points: The latest in AI from Mar. 21 to Mar. 27, 2024deeplearning.ai
 New Spanish and Turkish Language Models and Updated General Models - Deepgram Blog ⚡️Deepgram
 Read Every Single ErrorPulumi
 Introducing New Slimmer Docker ImagesPulumi
 The Go Memory Model - The Go Programming LanguageGo
 What is a CUDA Thread Block?Modal
 How to Use Your Own RegistryDocker
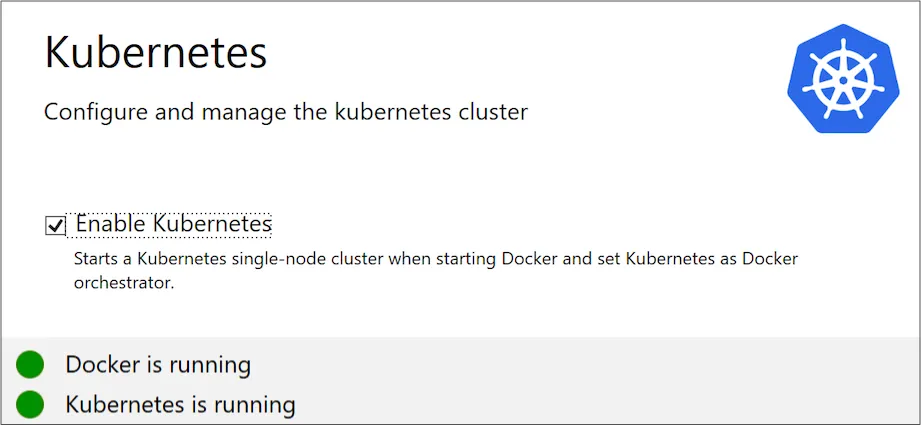 Docker for Windows Desktop with KubernetesDocker
 A prompt guide to get the most out of HeyGen's new Video AgentHeygen
 How to Create a Spokesperson on AI Video GeneratorHeygen
 How to Use AI Image to Video Generator for Free to Create Dynamic VideosHeygen
 How to Use Google NotebookLM: The AI-Powered Research AssistantHeygen
 How to Make AI Videos Look Professional in 2025Heygen
 Multi Face Swap Video: How to Swap Multiple Faces in a Single Video with AIHeygen
 You can just ship agentsVercel
