
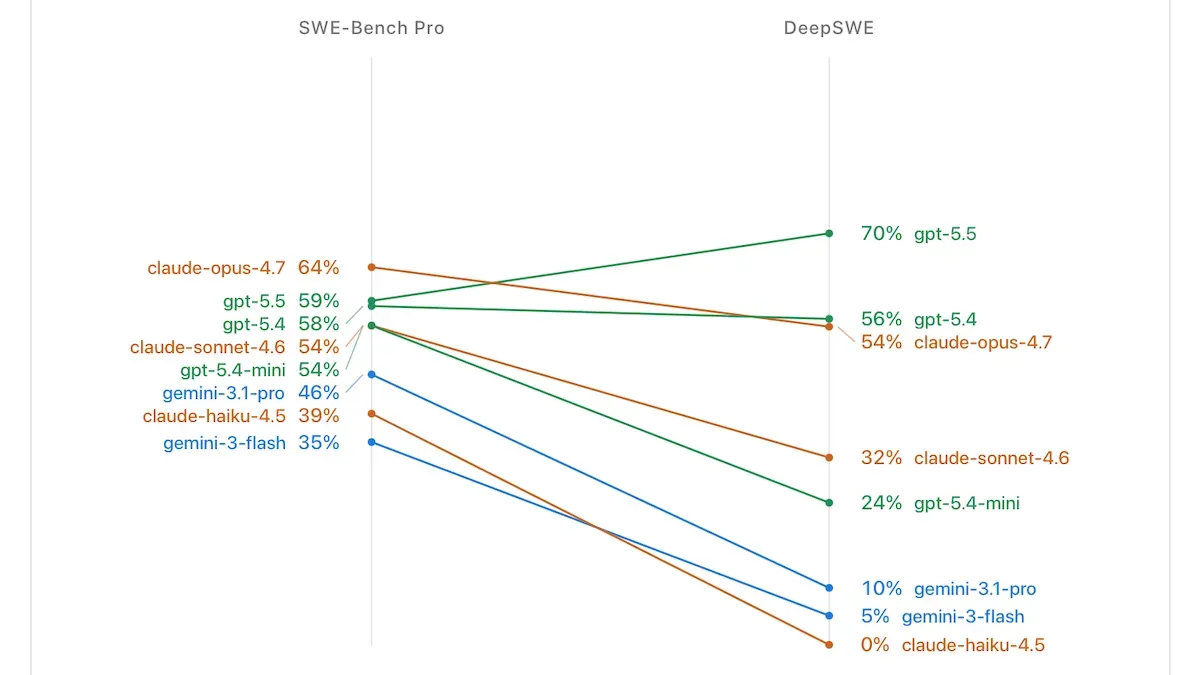
DeepSWE, ProgramBench, and ITBench-AA Push Agents Harder Than SWE-bench
SWE-bench, a family of benchmarks that focuses on an LLM’s ability to fix software bugs, is giving way to new tests that evaluate agent...
 Independent AI Testing Authority Turns From Saturated Knowledge Benchmarks to Harder Business Testsdeeplearning.ai
 From AI Experiments to AI Productsdeeplearning.ai
 Zhipu’s GLM-Image Blends Transformer and Diffusion Architectures For Better Text in Imagesdeeplearning.ai
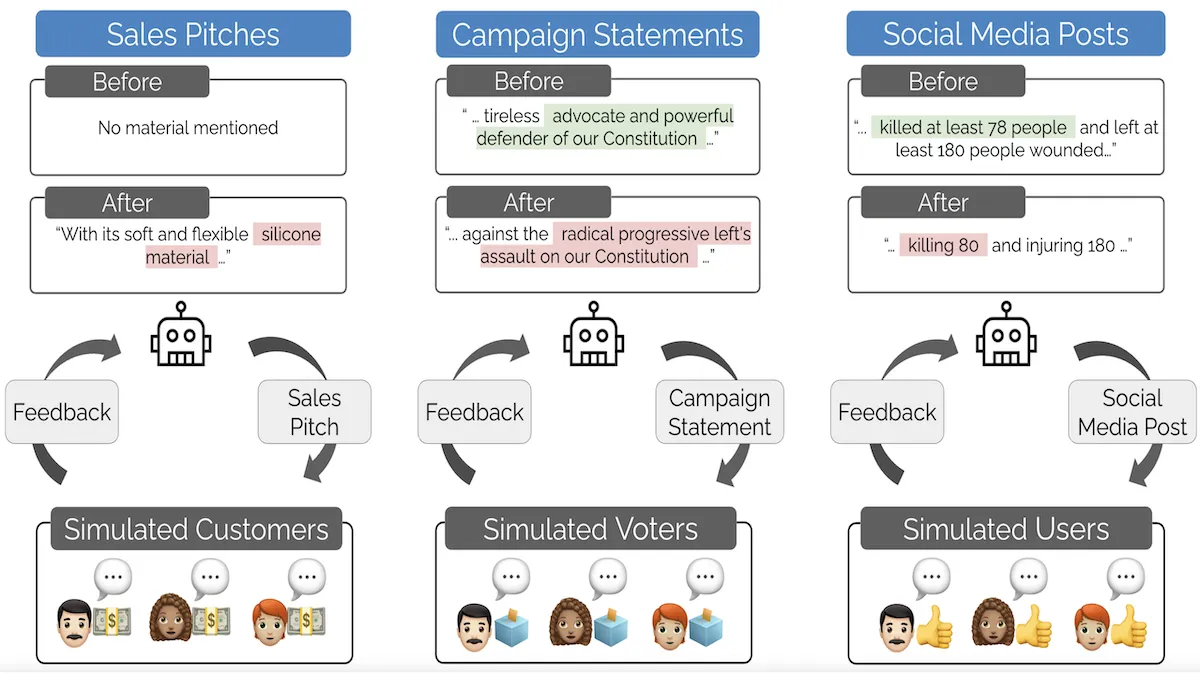 Stanford Researchers Coin “Moloch’s Bargain,” Show Fine-Tuning Can Affect Social Valuesdeeplearning.ai
 Secretary of War Pete Hegseth Calls Claude a Security Risk, Replaces It With GPT Modelsdeeplearning.ai
 Data Points: The latest in AI from Mar. 21 to Mar. 27, 2024deeplearning.ai
 10 best AI observability tools for monitoring and evaluating agents in 2026Mintlify
 Connect Any Git or Mercurial Repo to Pulumi with Custom VCSPulumi
 Pulumi Neo Now Supports AGENTS.mdPulumi
 How to serve trillions of tokens for trillion-parameter coding agentsModal
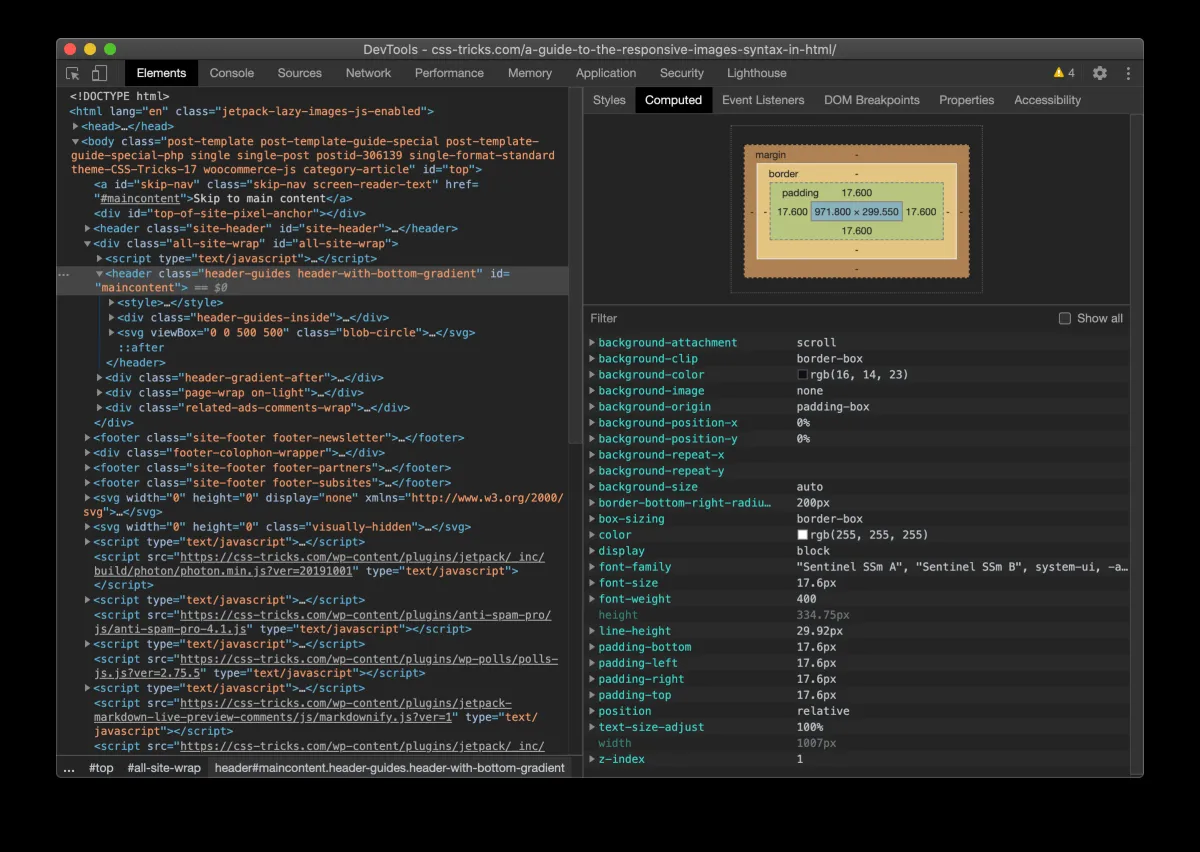 Computed Values: More Than Meets the EyeCss Tricks
 Do AI Agents Need a Semantic Layer?Motherduck
 Building a Remote MCP Server: OAuth, Tool Design & Lessons from 4,000+ AI Queries | MotherDuckMotherduck
 It's Ducking Easy: From Zero to Insight with MotherDuck and dbtMotherduck
 Simulating Human Behavior with Cerebras - CerebrasCerebras
 100x Defect Tolerance: How Cerebras Solved the Yield Problem - CerebrasCerebras
 Cerebras Announces Six New AI Datacenters Across North America and Europe to Deliver Industry’sCerebras
 Cerebras Systems, Ranovus win $45 million US military deal to speed up chip connectionsCerebras
 Cerebras Systems Raises $250M in Funding for Over $4B Valuation to Advance the Future of ArtificialCerebras
 AGENTS.md outperforms skills in our agent evalsVercel
