
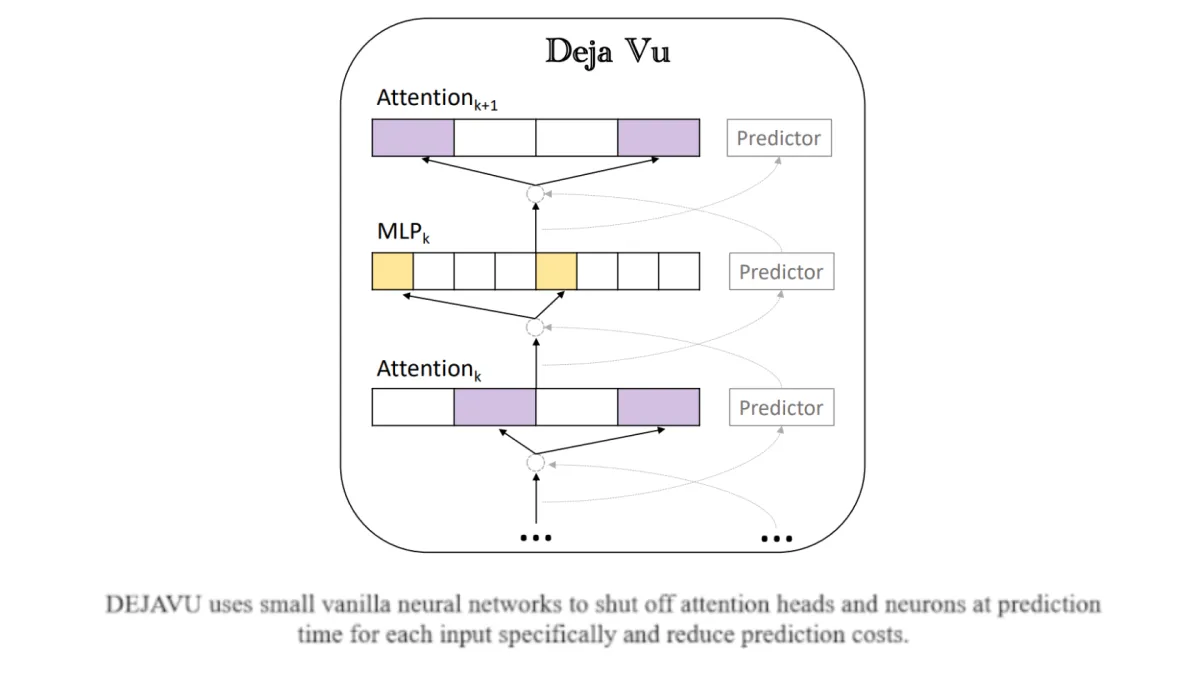
Deja Vu, a Method That Boosts LLM Speed by Activating Only Essential Neural Parts
It’s not necessary to activate all parts of a large language model to process a given input. Using only the necessary parts saves processing...
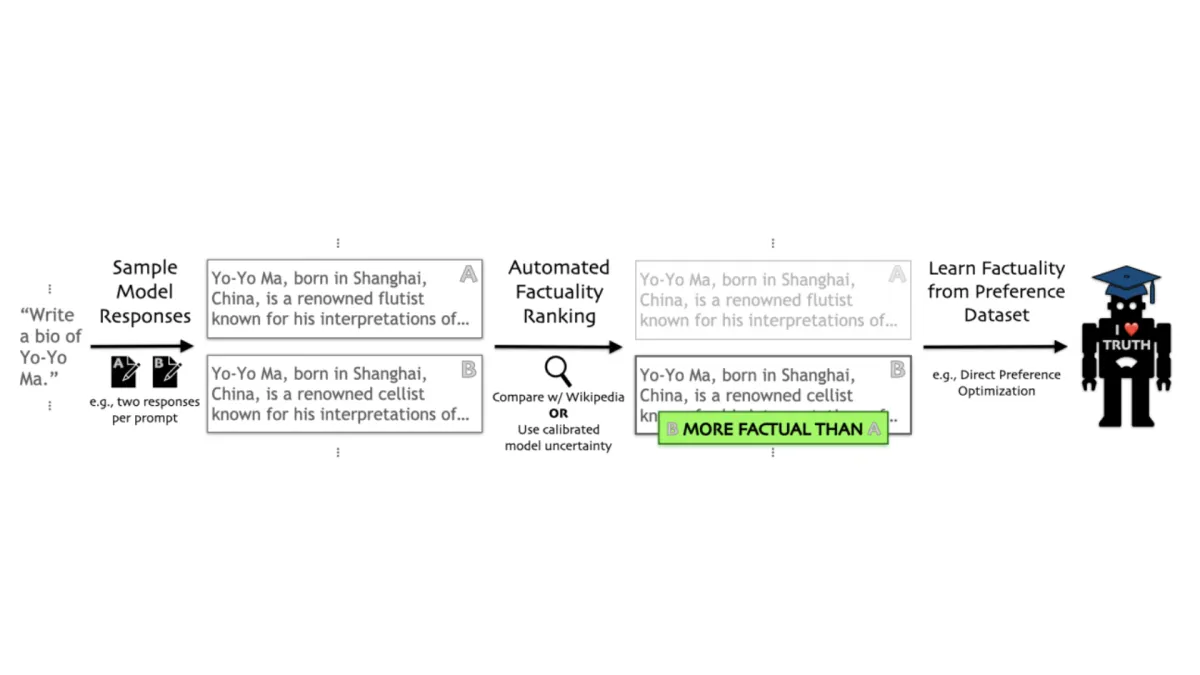 FactTune, A Method to Fine-Tune LLMs for Factual Accuracy Without Human Feedbackdeeplearning.ai
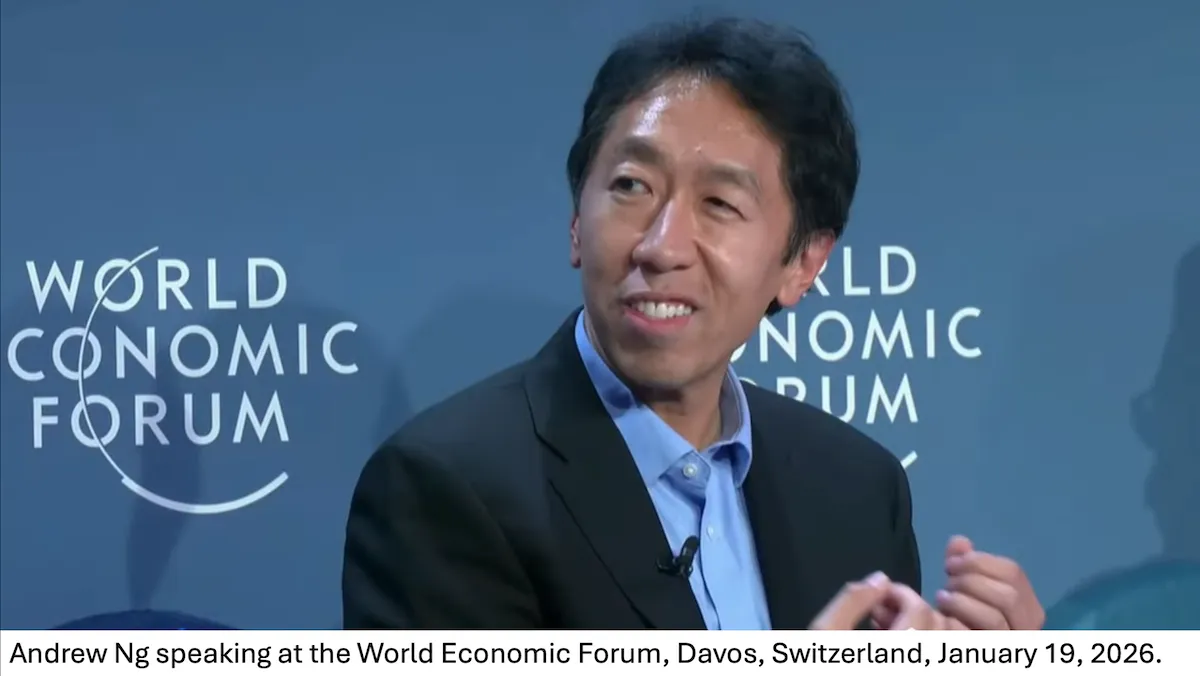 From AI Experiments to AI Productsdeeplearning.ai
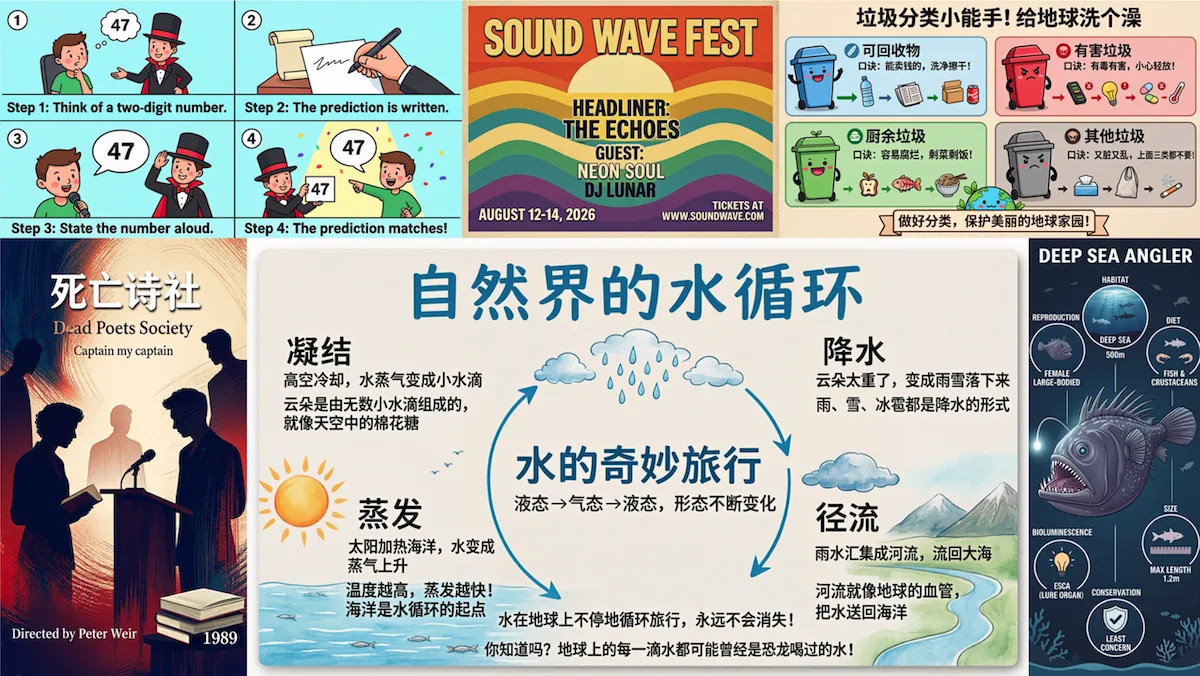 Zhipu’s GLM-Image Blends Transformer and Diffusion Architectures For Better Text in Imagesdeeplearning.ai
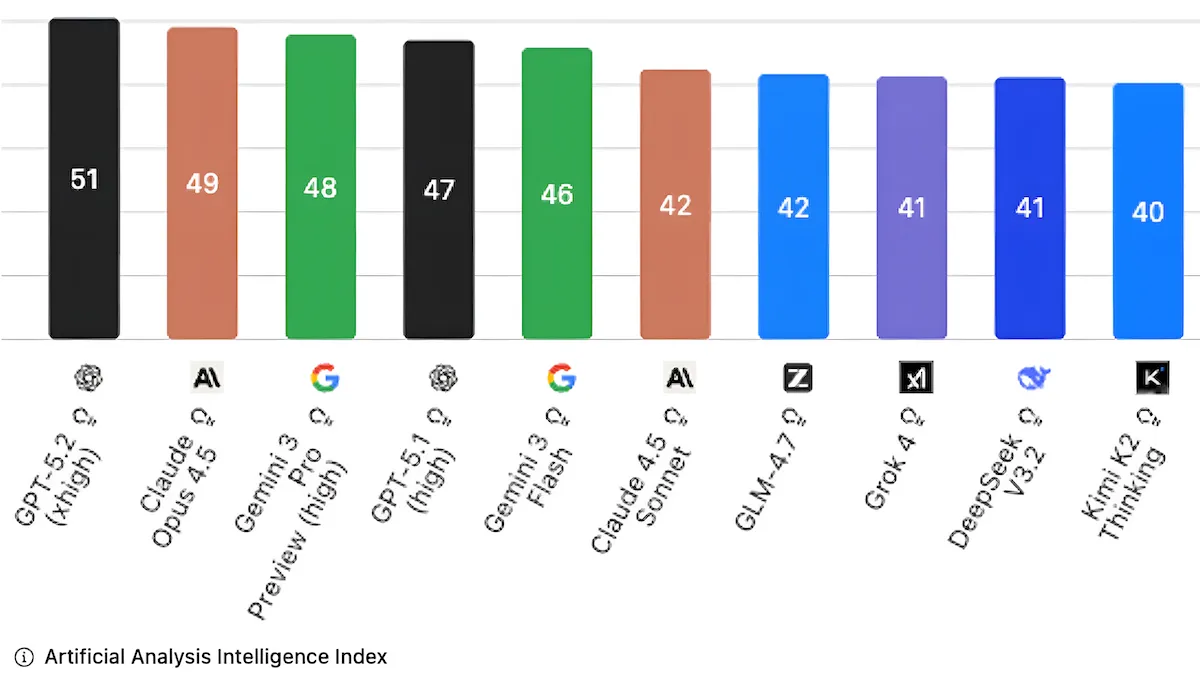 Independent AI Testing Authority Turns From Saturated Knowledge Benchmarks to Harder Business Testsdeeplearning.ai
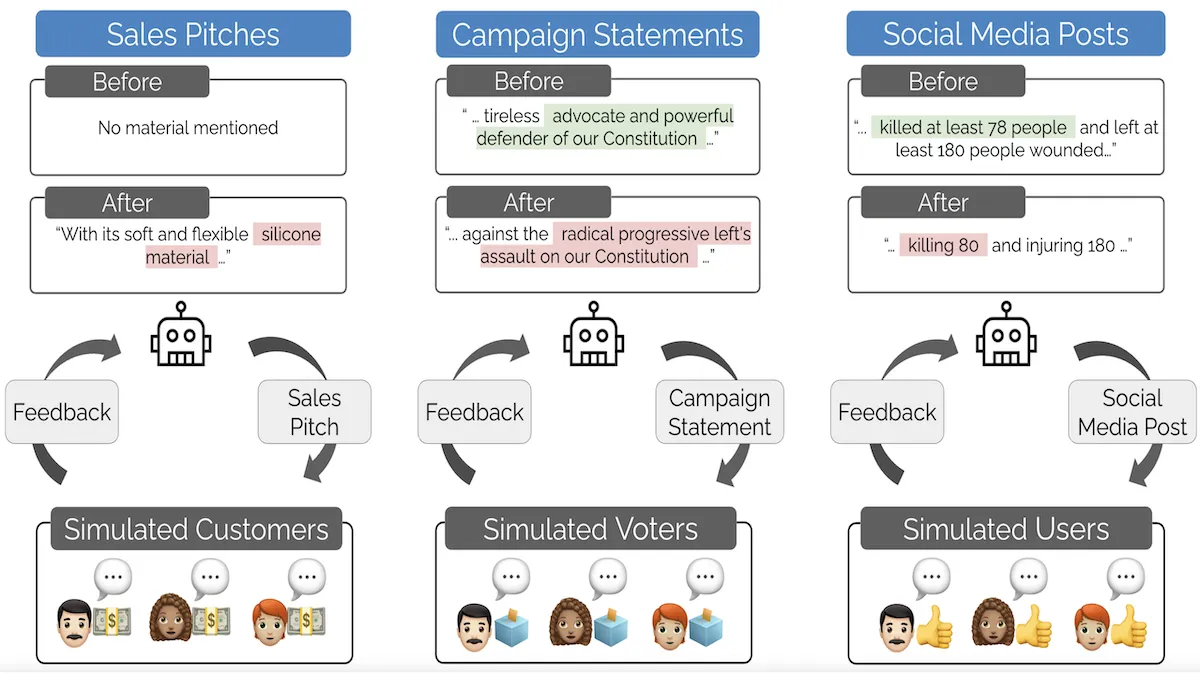 Stanford Researchers Coin “Moloch’s Bargain,” Show Fine-Tuning Can Affect Social Valuesdeeplearning.ai
 Secretary of War Pete Hegseth Calls Claude a Security Risk, Replaces It With GPT Modelsdeeplearning.ai
 The Simplest Possible Neural Network, Explained - Deepgram Blog ⚡️Deepgram
 Data Ingestion: 6 Ways to Speed Up Your ApplicationRedis
 DevSecOps: Why Security Shouldn’t be Sacrificed for SpeedThenewstack
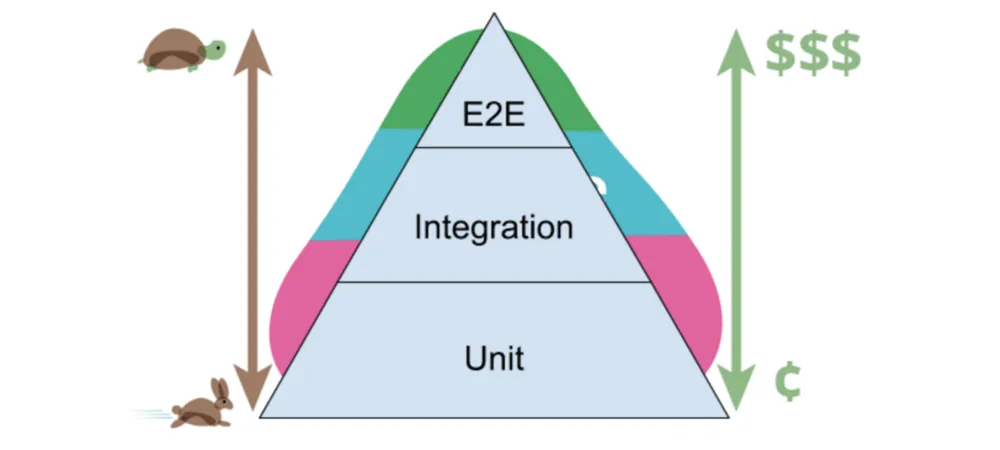 Develop, Preview, TestCss Tricks
 PostgreSQL and Ducks: The Perfect Analytical PairingMotherduck
 Cerebras Breaks Exascale Record for Molecular Dynamics Simulations - CerebrasCerebras
 Cerebras Systems, Ranovus win $45 million US military deal to speed up chip connectionsCerebras
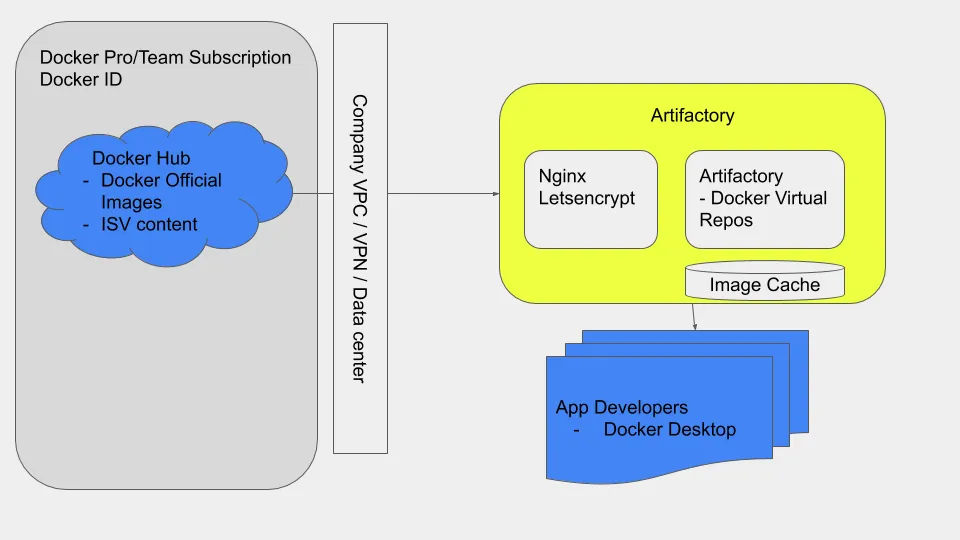 New Docker and JFrog Partnership Designed to Improve the Speed and Quality of App DevelopmentDocker
 Instagram Video Resizing GuideHeygen
 Best AI Video Generator for TikTok in 2026 (Tried & Tested)Heygen
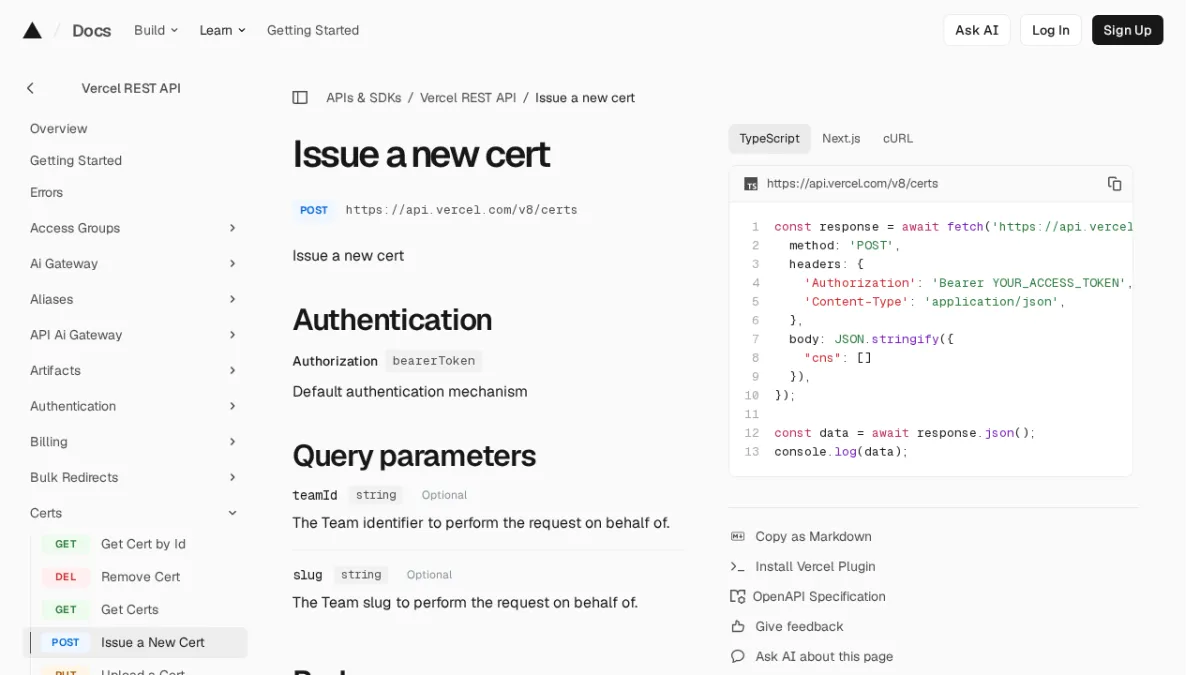 Issue a new certVercel
 You can just ship agentsVercel
 Autogenerating API documentation from OpenAPIMintlify
 GitOps Best Practices I Wish I Had Known BeforePulumi
